在 Scikit-Learn 流水线中用 Scikit-LLM 做 LLM 摘要
作者:Iván Palomares Carrascosa,KDnuggets 技术内容专家,2026年11月3日,发表于 Language Models 栏目
在文本上使用传统、轻量级的机器学习分类器时,通常需要将冗长且往往含有噪声的原始文本压缩为干净信号,才能取得成功。因此,考虑在将更干净的文本送入下游分类模型之前,先使用大语言模型(LLM)进行文本摘要,作为预处理阶段,这并不离谱。如果我们能把这无缝地作为传统、基于 scikit-learn 的流水线的一部分来完成,让 LLM 驱动的摘要与传统数据预处理、训练和推理共存,会怎样?如果我们能完全使用免费工具完成这一切,又会怎样?无需再找了。
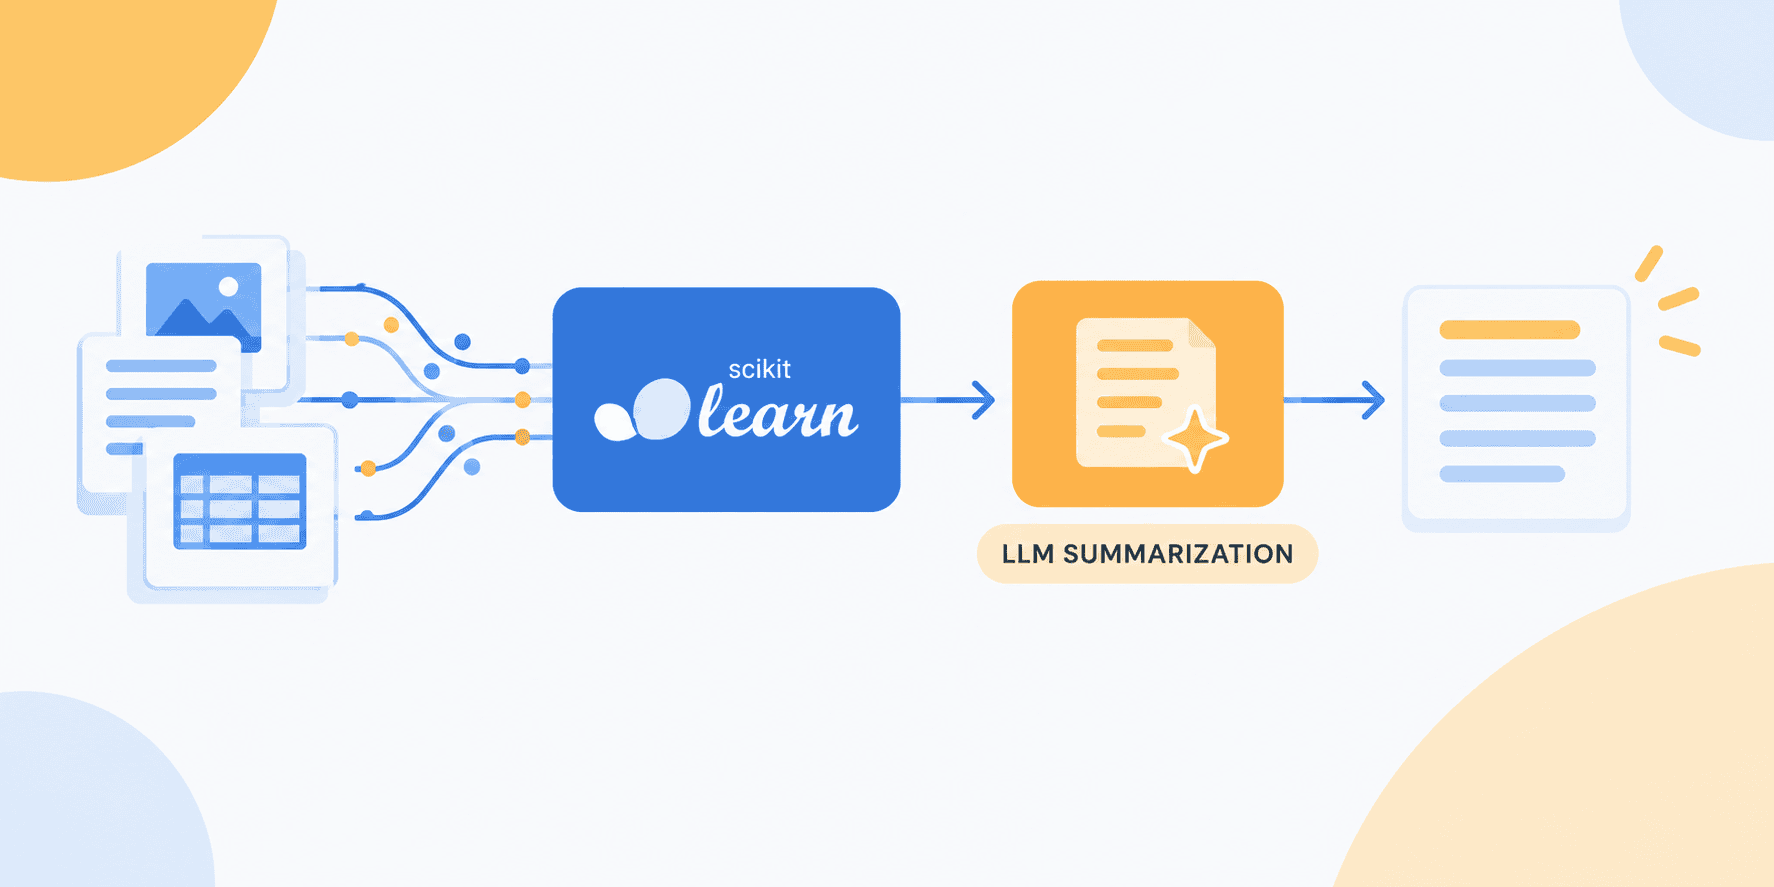
在本文中,我们将学习如何构建一种架构,将用于文本摘要的 Scikit-LLM 估计器与传统的 scikit-learn 方法融合到一个单一、统一的流水线中,用于对原始、杂乱文本进行摘要和分类,从而汇聚两个领域的最佳之处:LLM 与经典机器学习模型。
在机器学习流水线中集成 LLM 驱动的摘要
本示例可以完全在 Google Colab notebook 中运行。它使用 Groq 的 LLM API,从而完全依赖免费模型。前提条件是访问 Groq 网站、注册并生成你自己的 API key。生成后,请仔细复制你的 API key(它只显示一次),并将其粘贴为 Google Colab 中一个新的“Secret”变量,该变量位于 Colab 左侧的钥匙图标处。将该 secret 变量命名为 GROQ_API_KEY。
之后,我们通过安装 Scikit-LLM 来开始我们的 notebook:
!pip install scikit-llm -q
现在进入 Python 代码部分。第一步是配置 Scikit-LLM 周围的环境,把我们的请求经由 Groq 的 API 路由,而不是默认的 OpenAI API。这有助于我们利用 Groq 免费、友好且高效的预训练模型,从而避开按 Token 计费的成本。
from google.colab import userdata from skllm.config import SKLLMConfig # 获取 API key 并路由到 Groq 免费额度的 OpenAI 兼容端点 groq_key = userdata.get('GROQ_API_KEY') SKLLMConfig.set_gpt_url("https://api.groq.com/openai/v1") SKLLMConfig.set_openai_key(groq_key)
接下来,我们定义“训练”数据。它由一小组初始文档及其对应的标签组成。这些文档刻意写得冗长、带有一定噪声且啰嗦,就像许多真实场景中那样。如果不先做一次摘要,从文本中提取相关信号,那么直接从这些文本中获得数值化、适合机器学习的表示,必然会把噪声一并传播下去:
# 原始的长文档及其对应的类别标签 X_long_texts = [ "得益于新型钙钛矿层,新型太阳能电池板技术的效率提升了 15%,显著降低了住宅使用的门槛,并让安装比以往任何时候都更便宜、更快捷,从而推动绿色能源的普及。", "在央行意外加息之后,金融市场今日大幅下挫,科技板块出现大规模抛售,波动率指数被推升至三年多来的最高点。", "这种新型关节炎药物的临床试验显示出令人鼓舞的结果,在对照组中使关节肿胀减轻了 40%,且未出现严重副作用;该药物正等待 FDA 批准,获批后可能为数百万自身免疫性疾病患者带来缓解。" ] y_labels = ["Energy", "Finance", "Healthcare"]
与少样本分类类似,我们只需要一小批具有代表性的训练样本,就能让之后要加载的 LLM 知道该如何推理。整个过程并不会对 LLM 进行任何实际训练。
下一步可以说是最关键的:我们正在定义一套三步流水线,即先由 LLM 驱动摘要,再进行机器学习驱动的分类,从而把 Scikit-LLM 的能力——将预训练 LLM 适配到特定任务——集成进更广泛的机器学习流水线中。下面的代码使用 GPTSummarizer 对象封装一个兼容的 Groq 模型用于摘要,即 openai/gpt-oss-20b。随后它把摘要步骤嵌入 scikit-learn 流水线,接着使用词频-逆文档频率(TF-IDF)获取摘要文本的文本表示,而不是原始的长文本。最后,它使用此前定义的标签集定义并训练一个逻辑回归分类器。
from sklearn.pipeline import Pipeline from sklearn.feature_extraction.text import TfidfVectorizer from sklearn.linear_model import LogisticRegression from skllm.models.gpt.text2text.summarization import GPTSummarizer # 用于文本分类的三步机器学习流水线,前置摘要步骤 # 1. 摘要器:使用 Groq 上的兼容模型压缩长文档 # 2. 向量化器:将简洁的摘要转换为数值化的 TF-IDF 向量 # 3. 分类器:使用标准逻辑回归学习对 TF-IDF 向量进行分类 text_pipeline = Pipeline([ ('summarizer', GPTSummarizer( model="custom_url::openai/gpt-oss-20b", max_words=20 )), ('vectorizer', TfidfVectorizer()), ('classifier', LogisticRegression()) ]) # 端到端拟合整个流水线 text_pipeline.fit(X_long_texts, y_labels)
你可能会想,为什么 X_long_texts 里仅仅三个训练实例就足以训练最后一级的逻辑回归分类器。这并不是因为分类器真正学会了“能源”“金融”和“医疗”这些宽泛的概念。它之所以奏效,是因为流水线中有两个机制在协同作用:LLM 首先充当一个精确的过滤器,把嘈杂的文本压缩成“规范”关键词。此后,下游的向量化器自然会把整个词表限制在剩下这几个词上,从而把分类任务变成一个相当简单、几乎微不足道的关键词匹配游戏。
接下来,我们看看为这三个训练样本生成的摘要,以验证它们是否合理:
# 检查“训练”样本的摘要,访问 'summarizer' 对象 train_summaries = text_pipeline.named_steps['summarizer'].transform(X_long_texts) print("--- TRAINING DATA SUMMARIES ---") for label, original, summary in zip(y_labels, X_long_texts, train_summaries): print(f"[{label.upper()}]\nOriginal: {original}\nSummary: {summary}\n")
--- 训练数据摘要 --- [能源] 原文:得益于新型钙钛矿层,新太阳能电池板技术的效率提高了15%,显著降低了住宅使用的准入门槛,并推动绿色能源的采用…… 摘要:新型钙钛矿太阳能电池板将效率提升15%,降低成本并加速住宅绿色能源的采用。 [金融] 原文:在央行意外加息后,金融市场今日大幅下挫,导致科技板块出现大规模抛售,并引发波动率指数飙升…… 摘要:意外加息后市场暴跌,引发科技板块抛售和高波动。 [医疗] 原文:针对新型关节炎药物的临床试验显示出有前景的结果,在对照组中使关节肿胀减轻40%,且无严重副作用,目前等待FDA批准…… 摘要:新型关节炎药物试验使肿胀减轻40%,无严重副作用,等待FDA批准。
既然这些摘要看起来相当合理,我们现在可以收尾了:创建一些测试样例,并将它们整体传入流水线,通过先摘要再分类的方式完成分类:
X_new = [ "一项针对季节性流感毒株的突破性 mRNA 疫苗,在 3 期临床试验中于多样化患者人群中显示出 85% 的有效性,为明年冬季建立更强健的全球免疫防线铺平了道路。", "研究人员开发出一种电网级钠离子电池,有望以远低于锂的成本储存过剩的风能和太阳能电力,可能解决可再生能源的间歇性问题。", "随着科技股从昨日跌势中反弹,股市在尾盘走高,主要半导体厂商的强劲财报和乐观的 GDP 增长预期是主要推动力。" ] # 该流水线会自动对未见过的文本进行摘要、向量化和分类 predictions = text_pipeline.predict(X_new) # 访问未见数据的中间摘要以便展示它们 new_summaries = text_pipeline.named_steps['summarizer'].transform(X_new) print("\n--- 未见数据的预测结果 ---") for text, summary, prediction in zip(X_new, new_summaries, predictions): print(f"原始文档: '{text}'") print(f"中间摘要: '{summary}'") print(f"最终预测类别: {prediction}\n" + "-" * 70)
这些就是我们最终得到的结果——相当不错!
原文较长,译文为节选;译文由英文原文机器翻译,术语按行业惯例统一,可在文末展开原文核对。
查看英文原文(Using LLM Summarization in Your Scikit-Learn Pipelines with Scikit-LLM)
By Iván Palomares Carrascosa, KDnuggets Technical Content Specialist on November 3, 2026 in Language Models
Using traditional, lightweight machine learning classifiers on text frequently requires condensing lengthy, often noisy raw text into clean signals to succeed. Therefore, it wouldn't be crazy to think of using a large language model (LLM) for text summarization as a preprocessing stage before feeding cleaner texts to the downstream classification model. What if we could do this seamlessly as part of a traditional, scikit-learn-based pipeline where LLM-driven summarization can coexist with traditional data preprocessing, training, and inference? And what if we could do all of this using exclusively free tools? Look no further.
In this article, we will learn how to build an architecture that blends Scikit-LLM estimators for text summarization with traditional scikit-learn methods into a single, unified pipeline for summarizing and classifying raw, messy text, bringing together the best of both worlds: LLMs and classical machine learning models.
Integrating LLM-Driven Summarization in a Machine Learning Pipeline
This example can be run entirely in a Google Colab notebook. It uses Groq's LLM API to fully rely on free models. A prerequisite is to access the Groq website, register, and generate your own API key. Once it's generated, carefully copy your API key (it is shown only once) and paste it as a new "Secret" variable in Google Colab, found at the key icon on the left-hand side of Colab. Name the secret variable GROQ_API_KEY.
After that, we start our notebook by installing Scikit-LLM:
!pip install scikit-llm -q
Now, into the Python code. The first step is to configure the environment surrounding Scikit-LLM, routing our requests through Groq's API instead of the default OpenAI API. This will help us leverage Groq's free, friendly, and efficient pre-trained models, bypassing per-token costs.
from google.colab import userdata
from skllm.config import SKLLMConfig

# Retrieving API key and routing to Groq's free-tier OpenAI-compatible endpoint
groq_key = userdata.get('GROQ_API_KEY')
SKLLMConfig.set_gpt_url("https://api.groq.com/openai/v1")
SKLLMConfig.set_openai_key(groq_key)
Next, we define the "training" data. It consists of a small set of initial documents along with their corresponding labels. The documents are intentionally lengthy, somewhat noisy, and verbose, just like in many real-world scenarios. Without a prior summarization to extract relevant signals from the text, directly obtaining numerical, machine learning-friendly representations from these texts would inevitably propagate the noise:
# Raw, lengthy documents and their corresponding class labels
X_long_texts = [
 "The new solar panel technology efficiency has increased by 15% due to the novel perovskite layer, significantly lowering the barrier to entry for residential use and driving green energy adoption by making installations cheaper and faster than ever before.",
 "Financial markets saw a sharp downturn today following the central bank's unexpected interest rate hike, leading to massive sell-offs in the tech sector and triggering volatility indices to reach their highest points in over three years.",
 "The clinical trial for the new arthritis medication showed promising results, reducing joint swelling by 40% in the control group without severe side effects, awaiting FDA approval which could bring relief to millions suffering from autoimmune disorders."
]

y_labels = ["Energy", "Finance", "Healthcare"]
Similar to few-shot classification, we only need a small, representative set of training examples to let the LLM we will load later know how to reason. No actual training of the LLM takes place.
The next step is arguably the most critical: we are defining our three-step pipeline for machine learning-driven classification preceded by LLM-driven summarization, thereby integrating Scikit-LLM capabilities to accommodate specific tasks on pre-trained LLMs into a broader machine learning pipeline. The code below uses a GPTSummarizer object to encapsulate a compatible Groq model for summarization, namely openai/gpt-oss-20b. It then embeds the summarization step into the scikit-learn pipeline, followed by term frequency-inverse document frequency (TF-IDF) to obtain text representations of summarized texts rather than the original, lengthy ones. Finally, it defines and trains a logistic regression classifier using the label set defined before.
from sklearn.pipeline import Pipeline
from sklearn.feature_extraction.text import TfidfVectorizer
from sklearn.linear_model import LogisticRegression
from skllm.models.gpt.text2text.summarization import GPTSummarizer

# THREE-STEP MACHINE LEARNING PIPELINE FOR TEXT CLASSIFICATION, PRECEDED BY SUMMARIZATION
# 1. Summarizer: Condenses long documents using the compatible model on Groq
# 2. Vectorizer: Converts the concise summaries into numerical TF-IDF vectors
# 3. Classifier: Learns to classify the TF-IDF vectors using standard Logistic Regression
text_pipeline = Pipeline([
 ('summarizer', GPTSummarizer(
 model="custom_url::openai/gpt-oss-20b",
 max_words=20
 )),
 ('vectorizer', TfidfVectorizer()),
 ('classifier', LogisticRegression())
])

# Fitting the entire pipeline end-to-end
text_pipeline.fit(X_long_texts, y_labels)
You might be wondering why just three training instances in X_long_texts could be enough to train the last-stage logistic regression classifier. It's not because the classifier has truly learned the broad concepts of 'Energy', 'Finance', and 'Healthcare'. Instead, it succeeds due to two pipeline mechanics working in tandem: the LLM first acts as a precise filter that condenses noisy text into "canonical" keywords. After that, the downstream vectorizer naturally limits its whole vocabulary to those few remaining words, turning the classification task into a pretty easy, largely trivial keyword-matching game.
Next, we take a look at the summaries produced for the three training examples to verify they make sense:
# Inspecting the summaries of "training" examples, accessing the 'summarizer' object
train_summaries = text_pipeline.named_steps['summarizer'].transform(X_long_texts)

print("--- TRAINING DATA SUMMARIES ---")
for label, original, summary in zip(y_labels, X_long_texts, train_summaries):
 print(f"[{label.upper()}]\nOriginal: {original}\nSummary: {summary}\n")
--- TRAINING DATA SUMMARIES ---
[ENERGY]
Original: The new solar panel technology efficiency has increased by 15% due to the novel perovskite layer, significantly lowering the barrier to entry for residential use and driving green energy adoption...
Summary: New perovskite solar panels boost efficiency by 15%, reducing costs and accelerating residential green energy adoption.

[FINANCE]
Original: Financial markets saw a sharp downturn today following the central bank's unexpected interest rate hike, leading to massive sell-offs in the tech sector and triggering volatility indices...
Summary: Markets plunged after unexpected rate hike, causing tech sell‑offs and high volatility.

[HEALTHCARE]
Original: The clinical trial for the new arthritis medication showed promising results, reducing joint swelling by 40% in the control group without severe side effects, awaiting FDA approval...
Summary: New arthritis drug trial reduces swelling by 40% with no severe side effects, pending FDA approval.
Since these summaries seem quite sensible, we can now finalize by creating some test examples and passing them entirely to the pipeline for classification via prior summarization:
X_new = [
 "A breakthrough mRNA vaccine targeting seasonal flu strains showed 85% efficacy across diverse patient demographics in stage 3 clinical trials, paving the way for a more robust global immune defense next winter.",
 "Researchers have developed a grid-scale sodium-ion battery that promises to store surplus wind and solar power at a fraction of lithium's cost, potentially resolving the intermittency issue of renewables.",
 "Stocks rallied in late trading as technology shares recovered from yesterday's losses, driven by strong earnings reports from major semiconductor manufacturers and optimistic GDP growth forecasts."
]

# The pipeline automatically summarizes, vectorizes, and classifies the unseen text
predictions = text_pipeline.predict(X_new)

# Access the intermediate summaries for the unseen data to display them
new_summaries = text_pipeline.named_steps['summarizer'].transform(X_new)

print("\n--- UNSEEN DATA PREDICTIONS ---")
for text, summary, prediction in zip(X_new, new_summaries, predictions):
 print(f"Original Document: '{text}'")
 print(f"Intermediate Summary: '{summary}'")
 print(f"Final Predicted Category: {prediction}\n" + "-" * 70)
And these are the final results we obtain — not bad at all!
--- UNSEEN DATA PREDICTIONS ---
Original Document: 'A breakthrough mRNA vaccine targeting seasonal flu strains showed 85% efficacy across diverse patient demographics in stage 3 clinical trials, paving the way for a more robust global immune defense next winter.'
Intermediate Summary: 'New mRNA flu vaccine achieved 85% efficacy in diverse patients, promising stronger global immunity next winter.'
Final Predicted Category: Healthcare
----------------------------------------------------------------------
Original Document: 'Researchers have developed a grid-scale sodium-ion battery that promises to store surplus wind and solar power at a fraction of lithium's cost, potentially resolving the intermittency issue of renewables.'
Intermediate Summary: 'New grid‑scale sodium‑ion battery can store excess wind/solar power cheaply, easing renewable intermittency.'
Final Predicted Category: Energy
----------------------------------------------------------------------
Original Document: 'Stocks rallied in late trading as technology shares recovered from yesterday's losses, driven by strong earnings reports from major semiconductor manufacturers and optimistic GDP growth forecasts.'
Intermediate Summary: 'Tech stocks rebound late, fueled by strong semiconductor earnings and hopeful GDP growth, boosting overall market rally.'
Final Predicted Category: Finance
----------------------------------------------------------------------
With the aid of Scikit-LLM, we have learned how to embed a free, pre-trained LLM for summarization directly into a native machine learning pipeline based on scikit-learn. In particular, we combined modern prompt-based text distillation with classical, lightweight TF-IDF vectorizers and linear models like logistic regression for classification, making the overall task lightweight and surprisingly effective.
Iván Palomares Carrascosa is a leader, writer, speaker, and adviser in AI, machine learning, deep learning & LLMs. He trains and guides others in harnessing AI in the real world.
原文为英文,正文由自动抓取并保留原文。
原文发布于 KDnuggets(Using LLM Summarization in Your Scikit-Learn Pipelines with Scikit-LLM),标题、摘要与正文由机器翻译,术语按行业惯例统一,未经人工逐句校订。