GEO、WebMCP 与机器人付费墙构建 AI 原生互联网
面向 AI 智能体的 MCP、GEO 与机器人付费墙解析
随着 AI 智能体的兴起,我们所熟知的互联网正在发生根本性变化。自互联网诞生以来,它就是为人类构建的。我们的路径始终如一。我们在 Google 上搜索,直接访问网站,浏览,并找到我们想要的东西,无论是信息还是想购买的产品。
当 AI 智能体出现时,这些原则依然保持不变,智能体不得不绕开它们。它们以机器人身份爬取,在几秒内浏览数十个网站,收集所需信息,并将其带回给用户。这一过程虽然可行,但在许多方面效率低下。2026 年,Cloudflare Radar 数据显示,机器人目前已占网络请求的 57.5% 以上,超过了人类流量。AI 在其中的占比正在快速增长。在 TollBit 的发布商网络中,AI 机器人访问量从 2025 年初每 200 次人类访问对应 1 次,增长到年底每 31 次人类访问对应 1 次。如今大多数互联网流量运行在从未为其设计的原则之上,而我们所熟知的互联网已无法有效支撑如此规模的 AI 流量。
AI 主要通过两种方式从互联网收集信息:模型训练和检索。尽管目的不同,两者都涉及从互联网收集内容。在模型训练期间,信息是提前收集的;而在检索期间,AI 智能体是在用户提出问题后进行爬取以获取信息。如今,检索的规模已大于训练。2025 年底,检索机器人每发出约 10 次页面请求,训练机器人才发出 1 次。
尤其是在过去一年里,已经有大量工作致力于更好地支持 AI 收集信息的方式,我想在此概述主要进展。
生成式引擎优化(GEO)
GEO 也被称为答案引擎优化(Answer Engine Optimization,AEO),指的是对网站进行优化,使 AI 能够轻松抓取其信息,并更有可能推荐该网站。GEO 对电商店铺尤其有价值,因为购物体验正在发生剧烈变化。
越来越多的人转向 AI 寻求产品推荐。AI 可以筛选多个品牌并实时进行比较。Adobe 的数据显示,2026 年 7 月,由 AI 引荐的流量转化率比非 AI 流量高出 60%,因为这类购物者到站时已经被引荐到该品牌。这一切都取决于 AI 能否轻松找到所需信息、是否信任这些信息,以及这些信息能否促使它推荐某家店铺。每个 GEO 项目都包含三个部分:技术结构、网站内容和第三方引用。
技术结构决定了 AI 如何在网站上导航。它就像一张地图,为 AI 提供通往所需信息的高效路径。技术结构包括以下步骤:
Robots.txt。确认该文件没有屏蔽你希望访问店铺的 AI 智能体。
Sitemap(站点地图)。保持其准确,以便智能体找到每一个重要的页面。
llms.txt 和 agents.md。这些文件为 AI 智能体提供网站指南。Shopify 现在会自动生成这两个文件,并将 agents.md 作为其面向 AI 的主要发现文件。默认版本是通用模板,值得定制。
产品 schema。结构化的产品数据能让价格、库存情况和规格信息保持准确,并便于 AI 读取。
渲染。仅通过 JavaScript 加载的内容,许多 AI 爬虫可能看不到。
一个常见的误解是,仅靠技术结构层面的操作就足以做好 GEO。这些操作能引导 AI 找到正确的内容,但如果内容本身没有优化,就不会产生效果。这就引出了成功的 GEO 项目的第二部分。
一切都始于准确了解 AI 试图回答哪些问题。寻找这些问题的最佳来源是客户评价、论坛讨论和关键词搜索数据。在此基础上,工作包括重写产品文案以直接回答这些问题、构建全面的 FAQ、在各个销售渠道保持产品信息一致,以及发布对比、指南等信息类内容。
技术结构和网站内容都在店主自己的掌控之中,第三方引用则不在其中,而第三方引用在产品发现阶段最为重要——此时消费者尚未决定选择哪个品牌。在这一阶段,AI 会依赖他人在评价、Reddit 帖子、YouTube 视频和行业刊物中对品牌的评价。建立这种声量比站内工作耗时更长,但它能让较小的品牌在 AI 推荐中与行业领先者竞争。
在 AI 智能体与网站之间交换信息和可执行工具方面,MCP 是当今已确立的标准。
Model Context Protocol(MCP)
Model Context Protocol(MCP)是一项开放标准,定义了 AI 系统如何连接外部工具与数据。Anthropic 于 2024 年 11 月推出该标准,OpenAI 于 2025 年 3 月采用,如今大多数主流 AI 平台都已支持。一个 MCP 服务器会暴露工具(智能体可执行的动作)、资源(智能体可读取的数据)和提示词(常见任务的模板)。无需每家 AI 公司都为每项服务单独构建定制集成,只要一个 MCP 服务器,就能与任何兼容的智能体配合使用。
2026 年 2 月,Google 的 Chrome 团队宣布了 WebMCP 的早期预览版,这是一项与 Microsoft 合作制定的拟议 Web 标准。WebMCP 将 MCP 的概念引入浏览器。网站可以发布结构化的动作,例如搜索商品、将商品加入购物车或预约,AI 智能体可直接调用这些动作,而无需靠截图和页面代码去猜测操作路径。
GEO 部分所述的过程涉及人们用 AI 浏览和比较产品,但前往在线商店完成购买仍然是用户自己的事。这一客户旅程正在慢慢改变。
AI 智能体正越来越多地获得钱包访问权限,因此它们如今可以在比价后直接购买商品。WebMCP 为智能体提供了一种可靠的方式来使用商店,而另一套独立的协议则负责处理交易本身。2025 年 9 月,OpenAI 与 Stripe 推出了智能体商务协议(ACP),用于支撑 ChatGPT 内的结账功能。Google 随后推出通用商务协议(UCP),与 Shopify、Walmart、Target 等企业共同打造,用于支撑 Gemini 和 Google AI Mode 中的结账功能。在这两者之下,Google 的智能体支付协议(AP2)以及 Visa 和 Mastercard 提供的智能体专用卡令牌,可在不向智能体暴露卡号信息的前提下确认购物者已授权该笔购买。
WebMCP 会为你的网站创建一个专为 AI 智能体打造的第二版本,我喜欢把它比作一栋房子。
想象一下,你的网站是一栋带门、带窗、四周还有围栏的房子。人们可以轻松穿过围栏门和前门,但 AI 智能体做不到。没有 GEO 或 WebMCP,智能体只能翻过围栏、从窗户爬进去。GEO 降低了围栏高度,让这段路程更轻松,但依然远算不上顺畅。WebMCP 则为 AI 提供了属于它自己的大门,让智能体可以像人一样轻松走入,走的是一条为它们专门搭建的路径。
根据 2026 年 NMI 的一项调查,仅有 11% 的美国成年人曾使用 AI 完成过一笔交易,但有 33% 的人在过去一个月里用 AI 做过购物调研。
面向内容变现的机器人付费墙
我想讨论的最后一个转变,是我觉得尤其令人兴奋的一个。在前两节中,我都假设网站所有者希望 AI 访问该网站。对电商店铺而言,AI 不过是一条通往销售和收入的新路径。另一些在线业务则看法不同,其中许多已因 AI 流量的上升而遭受严重损害。
内容网站(新闻媒体、研究出版机构、食谱网站、参考网站和评测博客)并不在自己的网站上销售产品。它们的营收模式依赖广告,因此靠人类的注意力赚钱。随着人们使用 AI 筛选和总结信息,这些注意力消失了,营收随之大幅下滑。当 Google 展示 AI 摘要时,用户点击传统搜索结果的比率为 8%,而不展示摘要时为 15%(Pew Research,2025)。2025 年全年,从 AI 工具到出版商的平均点击率下降了约三分之二(TollBit)。
一直以来,AI 都在免费使用互联网数据。TollBit、Cloudflare 和 AWS 等企业正在构建机器人付费墙系统,以改变这一局面。
机器人付费墙系统的工作方式是识别每一个进入的机器人,并决定是允许、拦截还是收费。未付费的机器人会收到一个报价,通常通过 HTTP 402“Payment Required”响应返回,付费后即可获取内容。
TollBit 将 AI 机器人流量路由到 TollBit 子域名,该子域名提供针对智能体优化的网站版本。出版商按许可类型(摘要或完整展示)设定费率,并可按机器人、页面、关键词、时间窗口或目录添加规则。AI 公司支付少量交易费,出版商则保留全额费率。
原文较长,译文为节选;译文由英文原文机器翻译,术语按行业惯例统一,可在文末展开原文核对。
查看英文原文(How GEO, WebMCP, and Bot Paywalls Are Building the AI-Native Internet)
MCP, GEO and Bot Paywalls Explained for AI Agents
With the rise of AI agents, the internet as we know it is changing in fundamental ways. Since its inception, the internet was built for humans. Our path was always the same. We searched on Google, went directly to websites, browsed, and found what we wanted, whether that was information or a product to purchase.
When AI agents came along, those principles stayed in place, and the agents had to work around them. They crawl as bots, browse dozens of websites in seconds, collect the information they need, and bring it back to the user. The process works, but in many ways it is inefficient. In 2026, Cloudflare Radar data showed that bots now account for over 57.5% of web requests, surpassing human traffic. AI makes up a rapidly growing part of that share. Across TollBit's publisher network, AI bot visits grew from 1 for every 200 human visits in early 2025 to 1 for every 31 by the end of the year. Most internet traffic now runs on principles that were never designed for it, and the internet as we know it can no longer effectively support the volume of AI traffic.
AI gathers information from the internet in two primary ways, model training and retrieval. Although the purposes differ, both involve collecting content from the internet. During model training, the information is collected ahead of time, while during retrieval the AI agent crawls for information after the user asks a question. Retrieval is now the larger of the two. In late 2025, retrieval bots made roughly ten page requests for every one made by a training bot.
Over the last year especially, there has been a lot of work to better support how AI collects information, and I want to outline the main developments here.
Generative Engine Optimization (GEO)
Also referred to as Answer Engine Optimization (AEO), GEO is the practice of optimizing a website so AI can easily retrieve its information and is more likely to recommend it. GEO is particularly valuable for e-commerce stores, where the shopping experience is changing drastically.
More and more, people are turning to AI for product recommendations. AI can sift through several brands and make real-time comparisons. According to Adobe, AI-referred traffic converted at a 60% higher rate than non-AI traffic in July 2026, since these shoppers arrive already referred to the brand. All this depends on how easily AI can find the information it needs, whether it trusts that information, and whether that information leads it to recommend a store. Every GEO project has three parts, the technical structure, the website content, and third-party citations.
The technical structure determines how AI navigates the website. It works like a map, giving AI an efficient path to the information it needs. The technical structure steps include:
Robots.txt. Confirm the file is not blocking the AI agents you want visiting your store.
Sitemap. Keep it accurate so agents can find every page that matters.
llms.txt and agents.md. These files give AI agents a guide to the website. Shopify now generates both automatically and treats agents.md as its primary discovery file for AI. The default versions are generic and worth customizing.
Product schema. Structured product data keeps prices, availability, and specifications accurate and easy for AI to read.
Rendering. Content that only loads through JavaScript may be invisible to many AI crawlers.
It is a common misconception that the technical structure steps alone are enough for GEO. They guide AI to the right content, but they won't produce results if the content itself is not optimized. Which brings me to the second part of a successful GEO project.
Everything begins with knowing exactly which questions AI is trying to answer. The best sources for those questions are customer reviews, forum conversations, and keyword search data. From there, the work involves rewriting product copy to answer those questions directly, building a comprehensive FAQ, keeping product information consistent across every sales channel, and publishing informational content such as comparisons and guides.
Technical structure and website content are both in the store owner's control. Third-party citations are not, and they matter most during product discovery, when a shopper has not yet decided on a brand. At that stage, AI leans on what others say about a brand in reviews, Reddit threads, YouTube videos, and industry publications. Building that presence takes longer than the on-site work, and it allows smaller brands to compete with industry leaders in AI recommendations.
When it comes to exchanging information and actionable tools between AI agents and websites, MCP is the established standard today.
Model Context Protocol (MCP)
Model Context Protocol (MCP) is an open standard that defines how AI systems connect to external tools and data. Anthropic introduced it in November 2024, OpenAI adopted it in March 2025, and most major AI platforms now support it. An MCP server exposes tools (actions an agent can take), resources (data it can read), and prompts (templates for common tasks). Instead of every AI company building a custom integration for every service, one MCP server works with any compatible agent.
In February 2026, Google's Chrome team announced an early preview of WebMCP, a proposed web standard developed in partnership with Microsoft. WebMCP brings the MCP concept to the browser. A website can publish structured actions, such as searching products, adding an item to the cart, or booking an appointment, and AI agents call them directly instead of guessing their way through screenshots and page code.
The process outlined in the GEO section involves people using AI to browse and compare products, but it is still the user's job to go to the online store and make the purchase. This customer journey is slowly changing.
AI agents are increasingly gaining wallet access, so they can now buy products directly after comparing them. WebMCP gives agents a reliable way to use the store, and a separate set of protocols handles the sale itself. OpenAI and Stripe launched the Agentic Commerce Protocol (ACP) in September 2025 to power checkout inside ChatGPT. Google followed with the Universal Commerce Protocol (UCP), built with Shopify, Walmart, Target, and others, to power checkout in Gemini and Google's AI Mode. Underneath both, Google's Agent Payments Protocol (AP2) and agent-specific card tokens from Visa and Mastercard confirm the shopper authorized the purchase without exposing card details to the agent.
WebMCP creates a second version of your website built for AI agents, and I like to think of it as a house.
Imagine your website is a house with doors, windows, and a fence around it. People get through the fence gate and the front door easily, but AI agents can't. Without GEO or WebMCP, agents have to jump the fence and crawl through a window to get in. GEO lowers the fence, which makes the trip easier but still far from smooth. WebMCP gives AI its own gate and its own door, so agents can walk in as easily as people do, through a path built for them.
According to a 2026 NMI survey, while only 11% of U.S. adults have used AI to complete a transaction, 33% used AI for shopping research in the past month.
Bot Paywall for Content Monetization
The last shift I want to cover is one I find especially exciting. In the previous two sections, I assumed the website owner WANTS AI to visit the site. For e-commerce stores, AI is simply a new pathway to sales and revenue. Other online businesses see it differently, and many have been severely harmed by the rise in AI traffic.
Content websites (news outlets, research publishers, recipe sites, reference sites, and review blogs) don't sell a product on their website. Their revenue model relies on advertising, so they make money from human attention. As people use AI to sift through and summarize information, that attention disappears, and revenue drops significantly. When Google shows an AI summary, users click a traditional search result 8% of the time, compared to 15% when no summary appears (Pew Research, 2025). The average click-through rate from AI tools to publishers fell by roughly two-thirds over the course of 2025 (TollBit).
This entire time, AI has been using internet data for free. Businesses like TollBit, Cloudflare, and AWS are building bot paywall systems to change that.
Bot paywall systems work by identifying each incoming bot and deciding whether to allow, block, or charge it. A bot that has not paid receives a price, often through an HTTP 402 "Payment Required" response, and gets the content once it pays.
TollBit routes AI bot traffic to a TollBit subdomain that serves an agent-optimized version of the site. Publishers set rates by license type (summarization or full display) and can add rules by bot, page, keyword, time window, or directory. The AI company pays a small transaction fee, and the publisher keeps the full rate.
Cloudflare launched Pay Per Crawl on July 1, 2025, the same day it began blocking AI crawlers by default. Publishers set a flat per-request price, and Cloudflare handles payment as the merchant of record.
AWS added AI traffic monetization to AWS WAF in June 2026 for sites on CloudFront. Publishers set a price per page, and agents pay in stablecoin through the x402 protocol. AWS has announced Stripe support as coming soon.
You may be thinking, "AI companies already get this information for free, so why would they pay for it?" It is one of the main questions on the topic, and the answer has two sides. In the ideal scenario, the system works as an information marketplace where both sides benefit.
What is in it for publishers
On the publisher's side, the initial appeal is intuitive. Bot paywalls turn traffic that returns almost nothing today into revenue. In mid-2025, Cloudflare measured Anthropic crawling roughly 38,000 pages for every visitor it referred back to a site, and OpenAI roughly 1,100. Publishers also gain control over which bots access which content and for what purpose, along with an audit trail of every request.
What is in it for AI companies
It may be hard to believe that AI companies will pay for information they get for free today, but that information isn't truly free. Going back to the house analogy, AI agents today have to jump fences and climb through windows to get inside. An information marketplace comes with MCPs built for publishers' content, which gives the bot its own door. The inefficiency in how AI finds information already shows up on AI companies' balance sheets as computing costs.
Second, AI companies face no shortage of lawsuits over their crawling practices. Perplexity alone faces around ten lawsuits, including cases from Dow Jones and the New York Post (2024), Encyclopedia Britannica, Reddit, and Amazon (2025), and The New York Times and CNN (2025 and 2026). In 2025, Cloudflare also publicly accused Perplexity of using undeclared crawlers to get around websites' blocking rules. Anthropic agreed to a $1.5 billion settlement with authors in 2025 over pirated books used for training, and Reddit sued Anthropic that same year over scraping. OpenAI is still fighting The New York Times in a case filed in 2023. Legal fees and settlements across the industry now reach into the billions of dollars.
Third, more and more publishers are actively using security measures to block AI bots. Since July 2025, Cloudflare, which serves roughly one in five websites, blocks AI crawlers by default. With a bot paywall, that high-quality data becomes available again for model training and retrieval.
Each transaction would cost a fraction of a dollar, and in the big picture, it will be worth it for AI companies to take the clean road and pay the toll. A toll highway is almost always better than the alternative.
The last thing to consider is pricing, and it remains an open question across the industry. It is hard to know how much AI companies will be willing to pay for content, so dynamic pricing strategies will be crucial. Today's systems offer rule-based pricing. TollBit lets publishers price by bot, page, and time window, and AWS lets them price based on how well a bot's identity is verified. The market is still early, and paid volume remains small. Over time, prices will need to reflect how valuable a piece of content is, how fresh it is, and how much AI demand it attracts.
The internet is going through its largest structural change since search engines arrived. GEO helps AI find and trust a website, WebMCP and the new commerce protocols let agents act and buy on a shopper’s behalf, and bot paywalls give publishers a way to get paid for the content AI depends on. Each of these is still early, and most businesses have yet to adopt any of them. The businesses that move now will have their infrastructure in place by the time AI traffic becomes the norm, and they will have shaped how AI represents them instead of reacting to it.
“Adobe AI Referral Traffic Data, July 2026.” Digital Commerce 360, 19 Aug. 2026, www.digitalcommerce360.com/2026/08/19/adobe-ai-referral-traffic-data-july-2026/.
“Agentic Commerce Protocols Explained.” GoDataFeed, www.godatafeed.com/blog/agentic-commerce-protocols-explained. Accessed 24 Oct. 2026.
“Anthropic to Pay Authors $1.5B to Settle Lawsuit over Pirated Chatbot Training Material.” NPR Illinois, 5 Sept. 2025, www.nprillinois.org/2025-09-05/anthropic-to-pay-authors-1-5b-to-settle-lawsuit-over-pirated-chatbot-training-material.
“AWS WAF Adds AI Traffic Monetization Capability to Help Content Owners Charge AI Bots for Content Access.” AWS News Blog, Amazon Web Services, 15 June 2026, aws.amazon.com/it/blogs/aws/aws-waf-adds-ai-traffic-monetization-capability-to-help-content-owners-charge-ai-bots-for-content-access/.
“Bot & Agent Paywall.” TollBit, tollbit.com/bot-paywall/. Accessed 24 Oct. 2026.
“Bots Overtake Human Traffic.” GMAL, 2 Mar. 2026, www.gmal.co.uk/bots-overtake-human-traffic/.
“Cloudflare Accuses AI Startup of ‘Stealth Crawling Behavior’ Across Millions of Sites.” TechRepublic, Aug. 2025, www.techrepublic.com/article/news-cloudflare-accuses-perplexity-stealth-crawling-violations/.
“Cloudflare Reports Bots Surpass Human Web Traffic.” Let’s Data Science, 4 June 2026, letsdatascience.com/news/cloudflare-reports-bots-surpass-human-web-traffic-8dc5891c.
“Cloudflare Will Now, by Default, Block AI Bots from Crawling Its Clients’ Websites.” MIT Technology Review, 1 July 2025, www.technologyreview.com/2025/07/01/1119498/cloudflare-will-now-by-default-block-ai-bots-from-crawling-its-clients-websites/.
“Crawl-to-Referral Ratio.” PPC Land, ppc.land/crawl-to-referral-ratio/. Accessed 24 Oct. 2026.
“Google Chrome Launches WebMCP in Early Preview for AI Agent Interactions.” eWeek, 16 Feb. 2026, www.eweek.com/news/google-webmcp-chrome-ai-web-standard-preview/.
“Llms.txt and agents.md.” Shopify Developer Community, 2026, community.shopify.dev/t/llms-txt-and-agents-md/34049.
“Model Context Protocol.” Wikipedia, Wikimedia Foundation, en.wikipedia.org/wiki/Model_Context_Protocol. Accessed 24 Oct. 2026.
“NMI Research: Consumers Want AI to Help Them Shop, Not Control Their Spending.” NMI, 26 Aug. 2026, www.nmi.com/about-us/news/nmi-research-consumers-want-ai-to-help-them-shop-not-control-their-spending/.
“Perplexity AI Lawsuits (2026): All 10 Cases & Status.” AI Lawsuit Tracker, ailawsuittracker.com/companies/perplexity/. Accessed 24 Oct. 2026.
“Pew: AI Summaries Cut Google Click-Throughs to 8% from 15%.” AI Weekly, 29 June 2026, aiweekly.co/alerts/pew-ai-summaries-cut-google-click-throughs-to-8-from-15.
“Reddit Sues AI Company Anthropic for Allegedly ‘Scraping’ User Comments to Train Chatbot Claude.” ABC7 News, June 2025, abc7news.com/post/reddit-sues-ai-company-anthropic-allegedly-scraping-user-comments-train-chatbot-claude/16658542/.
“Traffic Trends.” Cloudflare Radar, Cloudflare, radar.cloudflare.com/traffic#bot-vs-human. Accessed 24 Oct. 2026.
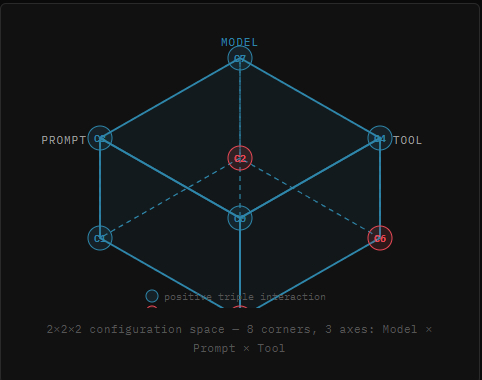
Best-worst comparisons, MaxDiff-style judging, and Plackett-Luce utility scores give agent teams a cleaner way to decide which configs to ship, prune, and route toward next.
July 6, 202613 min read
Digit classifier is apparently the new Hello World!
September 28, 20206 min read
Trapped in a purgatory of POCs, enterprises need to focus and build just 3 pillars to realize value from AI
September 15, 20256 min read
The key topics to master to become a better data scientist
August 8, 20188 min read
A pragmatic journey using website analytics as a real-world example
February 20, 202611 min read
A simple technique for boosting accuracy on ANY model you use
February 10, 20216 min read
Statistical techniques for time series anomaly detection
November 10, 20214 min read
A practical guide to build an interactive user interface for connecting multiple MCP servers
July 21, 20258 min read
A Case Study Examining the Impact of the Data Act, the GDPR and the AI Act on Connected Cars
January 18, 202410 min read
原文为英文,正文由自动抓取并保留原文。
原文发布于 Towards Data Science(How GEO, WebMCP, and Bot Paywalls Are Building the AI-Native Internet),标题、摘要与正文由机器翻译,术语按行业惯例统一,未经人工逐句校订。