如何用一个语义模型为100+客户生成报表
如果你需要向许多受众汇报,你很可能不止一次地构建过同一份报告。代理机构为每个客户构建一份报告。咨询公司为每个项目构建一份报告。内部数据分析团队为每个业务单元、品牌或市场构建一份报告。每一份副本最初都是对真实差异的合理应对,而每一份副本都会让某个定义多一个栖身之所。
标准答案是指标层:每个指标只定义一次,让每个仪表板都读取这一定义。本文的设计中也包含一个指标层。指标层的前提是只有一个组织、一套术语和一份数据。而一百个互不相关的客户共用一个模型,则是另一个问题。他们各自用自己的名称来称呼这些指标,各自上传自己的数据,各自维护自己的日历,而且没有任何一家可以要求为了自己而改动共享模型。
我在一家为客户投放播客、广播、YouTube 及其他媒体的代理机构的数据分析团队里,针对这种情况设计了一套系统。大约十名分析师每人负责八到二十个客户账户,每个账户都有自己的报告,而当时唯一的增长方案是每新增十个客户就再招一名分析师。取而代之的是一套数据模型、一份指标目录、一个报告模板,以及每个客户一份简短的设置记录。最终,同一个模板服务了一百多个客户。本文会一次引入一个复杂点,逐步搭建这套设计。其中的所有内容都在一个小型配套仓库中运行,使用合成数据和三个虚构客户。
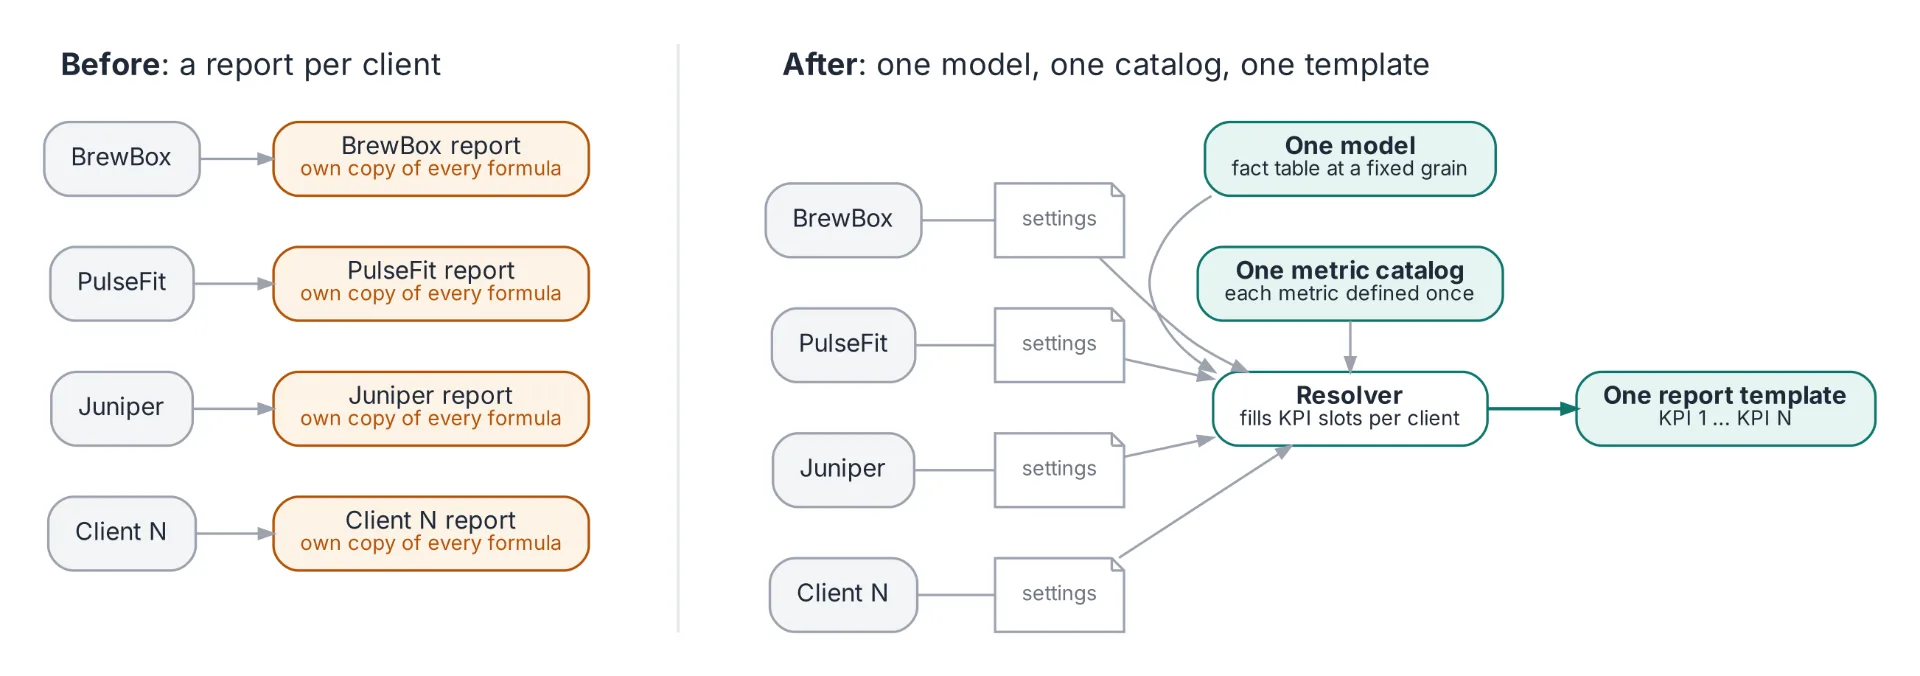
先从简单情形开始:十个客户,全都关注获客成本(CPA),即花费除以转化数。十份报告配十个 CPA 公式也能运转,直到定义发生变化,而其中一份副本被漏掉。
另一种方案是一张表。每个客户的数据都进入其中,列相同,明细层级也相同:
配套仓库中合成数据的三行。空单元格是有意为之。
这是维度模型中心的事实表:每个客户、广告活动、渠道和日期一行。这一固定的明细层级就是粒度。后续一切皆取决于它,在任何新的报表系统中,这都是我会做的第一个决定。
图 2。共享维度模型。一张固定粒度的事实表只保存可加性度量。客户、广告活动、渠道和日期是维度。各客户专属设置位于模型之外,放在配置中。
CPA 现在只定义一次:
sum(spend) / nullif(sum(conversions), 0)
客户是一个筛选条件。在原系统中,报表模板的加载脚本有一个单独的 where client = ... 子句。更改那一个值,就会把每张图表和每个标签切换到另一个客户。
同样的计算,不同的名称
第一个麻烦在第十个客户到来之前就出现了。客户在计算口径上达成一致的概率,远高于在叫法上达成一致的概率。一个客户说的 CPA,在另一个客户那里是 CPO,即每单成本。一个客户把流量叫 sessions,另一个客户叫 visits。一个客户把收入除以花费叫 ROAS,另一个客户把同一个数字叫 ROI。
反过来也一样。「获客(Acquisition)」对一个客户来说意味着完成的订单,对另一个客户来说是发起的结账,对第三个客户来说则是一次网站访问。「ROI」对一个客户来说是收入除以花费,对另一个客户来说是利润除以花费。分析师在接手同事负责的账户时,可能会在不知情的情况下套用错误的定义。
如果名称存在于公式内部,那么每一次重命名都会变成一个新指标,各个副本也就随之各自漂移。所以我把两者拆开了。定义只存一份,放在目录里。名称则放在客户自己的设置中。在入驻阶段,每个 KPI 都会问两个问题:你怎么计算它,以及你怎么称呼它?第一个答案映射到一个已有的定义,或者成为一个新定义——只定义一次,对所有人生效。第二个答案则成为一个标签:
brewbox: name: BrewBox Coffee Subscription week_start: monday conversion: Trial kpi_types: [cpa] sends: [spend, impressions, sessions, conversions] labels: {sessions: Visits}
BrewBox 的报告在与其他所有客户相同的 SQL 之上展示“Cost per Trial”和“Visits”。无论客户的主要成果是试用、安装还是下单,都会落进同一个通用的 conversions 列,具体用词由记录提供。目录中的 {conversion} 占位符由这条记录填充,BrewBox 的 Cost per Trial 正是由此得来。想把收入除以支出显示为“ROI”的客户,会在 roas 上得到一个标签。而把利润除以支出理解为 ROI 的客户,则得到另一个定义 roi。只要目录知道哪个是哪个,两个客户就可以都看到名为 ROI 的列,却得到不同的算法。报告周也在这条记录里,因为放错周的周度数字就是错的数字。sends 这一行是后文一节的讨论对象。
这正是该设计与普通指标层分道扬镳之处。指标层给一个指标一个名称;而这个设计给一个指标一个含义,以及和客户数量一样多的名称。
那如果有些客户关注的是不同的 KPI 呢?
第十一个客户是一家在线商店,它关注广告支出回报率(return on ad spend)。再建第二份报告,就又会开始复制。
于是报告不再为指标命名。模板只要求填入“KPI 1”到“KPI N”,至于每个位置填什么,由各客户自己的设置决定。目录按目标把指标归入模板:CPA 模板是 spend、conversions、CPA、sessions 和 conversion rate;ROAS 模板是 spend、revenue、ROAS、conversions 和 average order value。
客户选择一个或多个模板,而位于模板和数据库之间的一小段代码——解析器(resolver)——会按顺序把它们合并,并去掉重复项。这套系统的第一版为每个客户只选一个模板,对少数两个都要的客户则手工处理。有了合并,“两个都要”就成了普通情况。
未使用的槽位永远不会以空列的形式出现。在 BI 工具中,每个 KPI 列都带有一个“满足条件才显示列”的条件,该条件会读取客户的设置,因此一个只用了十个槽位中三个的客户看到的是三列,而不是十列。
如果客户发送的数据各不相同呢?
这是实践中最难的问题,也是我看到被讨论得最少的一个。
第三方并不拥有其客户的数据。消耗和曝光来自买方自己的投放记录,因此每个客户都有这两项;它们无论如何都列在 sends 之下,所以可用性检查只需一条规则。效果数据来自客户,由客户决定发送什么。一个客户只发送订单,别的什么都不发。另一个客户发送订单、会话和收入。而一个应用类客户有安装量,却完全没有网站会话。
CPA 模板包含转化率,即转化数除以会话数。对于没有会话的客户,它应该显示什么?显示零是不对的,因为零意味着经过测量、确认确实为零。面向客户的报表里不该出现报错信息。为每一种数据组合单独做一个模板,正是旧做法的走向。
两条声明就能解决。每个指标都声明自己由什么构成:
# semantic/metrics.yaml(节选:省略了展示格式与方向)base: spend: {column: spend} sessions: {column: sessions} conversions: {column: conversions} revenue: {column: revenue}ratio: cpa: {label: "Cost per {conversion}", num: spend, den: conversions} cvr: {label: "Conversion rate", num: conversions, den: sessions} roas: {label: "ROAS", num: revenue, den: spend} aov: {label: "Average order value", num: revenue, den: conversions}
每个客户端都会声明自己发送哪些数据;这就是 BrewBox 记录中的 sends 行。解析器会对照这份清单逐一检查所需的每个指标。受支持的指标会占据一个槽位。其余指标则被略去,报告会说明原因:
未显示- Sessions:需要 sessions,而该客户端并不发送。- Conversion rate:需要 sessions,而该客户端并不发送。
当客户端询问为什么缺少转化率时,答案就在页面上,而且它指向的是数据,而不是分析师。它还把一个抱怨变成了一项请求:发送 sessions,转化率就会出现,既不用新建报表,也不用改动代码。
同一份声明也统一了数据接入。一旦模型说明了自己需要什么,就能明确告诉新客户端该以什么形式发送数据。
图 3。单个客户端的报表是如何解析出来的。客户端的 KPI 类型从目录中挑选指标。每个指标的输入都会对照该客户端发送的数据进行检查。受支持的指标按顺序填入 KPI 槽位;其余指标则连同缺失原因一并列出。
事实表中没有 CPA 列,没有 ROAS 列,也没有转化率列。如果必须把其他一切都丢掉,这是我会保留的唯一一条规则:存储组成部分,绝不存储比率。
原文较长,译文为节选;译文由英文原文机器翻译,术语按行业惯例统一,可在文末展开原文核对。
查看英文原文(How to Report for 100+ Clients With One Semantic Model)
Semantic Model for Multi-Client Reporting With One Template
If you report to many audiences, you have probably built the same report more than once. Agencies build one report per client. Consultancies build one report per engagement. Internal analytics teams build one report per business unit, brand or market. Each copy begins as a reasonable response to a real difference, and each copy becomes one more place for a definition to live.
The standard answer is a metrics layer: define each metric once and make every dashboard read that definition. The design in this article contains one. A metrics layer assumes one organization, one vocabulary and one set of data. A hundred unrelated clients sharing one model is a different problem. Each of them calls the metrics by its own names, sends its own data and keeps its own calendar, and none of them may have the shared model changed on its behalf.
I designed a system for that case on the analytics team of an agency that bought podcast, radio, YouTube and other media for its clients. About ten analysts each carried between eight and twenty accounts, every account had its own report, and the only plan for growth was another analyst for every ten new clients. What replaced that was one data model, one metric catalog, one report template, and a short settings record per client. The same template ended up serving more than a hundred clients. This article builds the design up one complication at a time. Everything in it runs in a small companion repository with synthetic data and three fictional clients.
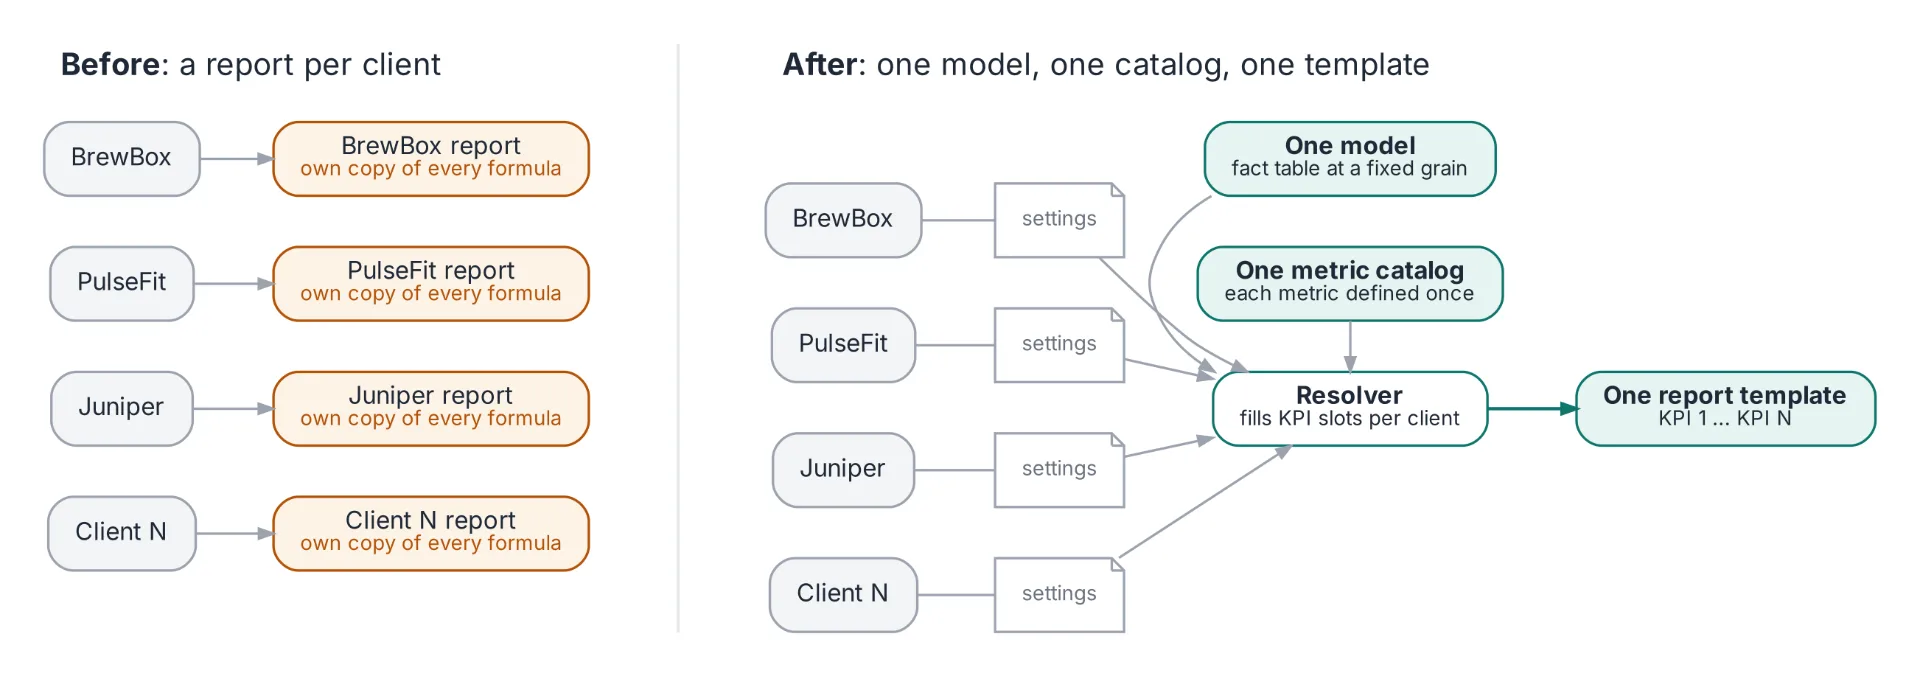
Start with the easy case: ten clients, all watching cost per acquisition (CPA), which is spend divided by conversions. Ten reports with ten CPA formulas work until the definition changes and one copy is missed.
The alternative is one table. Every client's data lands in it, with the same columns, at the same level of detail:
Three rows of the synthetic data in the companion repository. The empty cells are deliberate.
This is a fact table at the center of a dimensional model: one row per client, campaign, channel and day. That fixed level of detail is the grain. Everything that follows depends on it, and it is the first decision I would make in any new reporting system.
Figure 2. The shared dimensional model. One fact table at a fixed grain holds only additive measures. Clients, campaigns, channels and dates are dimensions. The per-client settings live outside the model, in configuration.
CPA is now defined exactly once:
sum(spend) / nullif(sum(conversions), 0)
The client is a filter. In the original system the report template's load script had a single where client = ... clause. Changing that one value switched every chart and every label to another client.
Same math, different names
The first complication arrives before the tenth client does. Clients agree on the math far more often than they agree on the words. One client's CPA is another client's CPO, cost per order. One client calls traffic sessions, and another calls it visits. One client calls revenue divided by spend ROAS, and another calls the same number ROI.
The reverse happens too. "Acquisition" meant a completed order for one client, a checkout started for another, and a site visit for a third. "ROI" meant revenue over spend for one client and profit over spend for another. An analyst covering a colleague's account could apply the wrong definition without knowing it.
If the name lives inside the formula, every renaming becomes a new metric and the copies drift apart. So I separated the two. The definition lives once, in the catalog. The name lives in the client's settings. At onboarding, every KPI gets two questions: how do you calculate it, and what do you call it? The first answer maps to an existing definition, or becomes a new one, once, for everyone. The second answer becomes a label:
brewbox: name: BrewBox Coffee Subscription week_start: monday conversion: Trial kpi_types: [cpa] sends: [spend, impressions, sessions, conversions] labels: {sessions: Visits}
BrewBox's report says "Cost per Trial" and "Visits" over the same SQL every other client gets. Whatever a client's primary outcome is, trial, install or order, it lands in one generic conversions column, and the record supplies the word. The {conversion} placeholder in the catalog is filled from this record, which is how BrewBox gets Cost per Trial. A client that wants revenue over spend shown as "ROI" gets a label on roas. A client that means profit over spend gets a different definition, roi. Two clients can both see a column called ROI and get different math, as long as the catalog knows which is which. The reporting week is in the record too, because a weekly number on the wrong week is a wrong number. The sends line is the subject of a later section.
This is where the design parts ways with a plain metrics layer. A metrics layer gives a metric one name. This gives it one meaning and as many names as there are clients.
What if some clients watch different KPIs?
Client eleven is an online store. It watches return on ad spend. Building a second report would start the copies again.
So the report stops naming metrics. The template asks for "KPI 1" through "KPI N", and each client's settings decide what fills each slot. The catalog groups metrics into templates by goal: the CPA template is spend, conversions, CPA, sessions and conversion rate; the ROAS template is spend, revenue, ROAS, conversions and average order value.
A client picks one or more templates, and a small piece of code between the template and the database, the resolver, merges them in order and drops duplicates. The first version of this system picked one template per client and handled the few clients that wanted both by hand. Merging makes "both" an ordinary case.
Unused slots never appear as empty columns. In the BI tool, each KPI column carried a "show column if" condition that read the client's settings, so a client using three of ten slots saw three columns, not ten.
What if clients send different data?
This was the hardest problem in practice and the one I see discussed least.
A third party does not own its clients' data. Spend and impressions come from the buyer's own booking records, so every client has them; they are listed under sends anyway, so the availability check has one rule. Performance data comes from the client, and the client decides what to send. One client sends orders and nothing else. Another sends orders, sessions and revenue. An app client has installs but no website sessions at all.
The CPA template includes conversion rate, which is conversions divided by sessions. What should it show for the client with no sessions? Zero would be wrong, because zero means measured and found to be zero. An error message has no place on a client-facing report. A separate template for every combination of data is where the old approach was heading.
Two declarations fix it. Every metric declares what it is made of:
# semantic/metrics.yaml (abridged: display format and direction omitted)base: spend: {column: spend} sessions: {column: sessions} conversions: {column: conversions} revenue: {column: revenue}ratio: cpa: {label: "Cost per {conversion}", num: spend, den: conversions} cvr: {label: "Conversion rate", num: conversions, den: sessions} roas: {label: "ROAS", num: revenue, den: spend} aov: {label: "Average order value", num: revenue, den: conversions}
Every client declares what it sends; that is the sends line in BrewBox's record. The resolver checks each wanted metric against that list. Supported metrics take a slot. The rest are left off, and the report says why:
Not shown- Sessions: needs sessions, which this client does not send.- Conversion rate: needs sessions, which this client does not send.
When a client asks why conversion rate is missing, the answer is on the page, and it points at the data rather than at the analyst. It also turns a complaint into a request: send sessions, and conversion rate appears, with no new report and no code change.
The same declaration standardizes intake. Once the model says what it needs, a new client can be told exactly what shape to send.
Figure 3. How one client's report is resolved. The client's KPI types pick metrics from the catalog. Each metric's inputs are checked against what the client sends. Supported metrics fill the KPI slots in order; the rest are listed with the reason they are missing.
The fact table has no CPA column, no ROAS column and no conversion rate column. That is the one rule I would keep if I had to throw everything else away: store the parts, never the ratio.
Average the daily CPAs and you get $60. Divide total spend by total conversions and you get $33.33, which is the campaign's actual CPA. The average weights a 10-conversion day the same as a 50-conversion day. Every ratio is therefore computed as sum(numerator) / sum(denominator) after grouping, at whatever level the report asks for. Day, week, channel or whole quarter, the definition is the same and the number is right. The whole family of "why doesn't the weekly number match the daily numbers" questions goes away. In the original system these ratios were expressions in the dashboard. The dataset held only raw measures.
What if the data arrives at a different grain?
Everything so far assumes one row per client, campaign, channel and day, and the design worked because nearly every source fit that grain. When a source does not, the same approach applies with one more table. The usual case is a radio vendor that sends weekly totals. The weekly source gets its own fact table on the same dimensions, reports roll the daily table up to weeks and combine the two at the coarser grain, and the report says it goes no finer than a week.
Two rules keep this honest. A weekly total is never spread across days, because that invents detail nobody measured. And a weekly source whose weeks do not start on the client's week start fails the build, because no query can realign those totals without guessing. Measures that do not add, unique reach above all, sit outside the pattern entirely and must be computed from source at the level requested.
This fits any team that produces the same kind of report for many audiences that each want their own numbers in it, as long as the audiences share a grain and a core set of measures and differ mainly in vocabulary, KPI selection, data availability and calendar. Keep N small; an audience that needs something truly custom should get a custom page of its own. And treat configuration as a product: once a record changes a client's numbers, it needs validation, an owner and a history.
What it did in production
Building a client's dashboard became a configuration change, and build time fell by roughly 70%, from hours to minutes. Weekly reporting work fell by about a third. The same template served more than a hundred clients.
Two effects mattered as much as the time saved. Definitions stopped drifting, and nearly any analyst could pick up nearly any account, because everything account-specific was written down in the settings record. And because the record was a table, it joined to the performance data. Questions that used to depend on memory, such as which clients in an industry tracked orders and how quickly their campaigns saturated, became a filter on the settings followed by one query.
What I would change today
Keep configuration in version control. The original settings lived in the CRM, where the account information already was, and analysts edited them there. A record that changes a client's numbers deserves a diff, a review, and a check against the data it describes. The repository warns when a record and the data disagree about what a client sends.
Declare inputs from the start. The first version already hid unused slots, but deciding which KPIs a client's data could support was still a judgment made at setup. Declaring each metric's inputs turns that judgment into a rule, and the "Not shown" list says why.
Use a mature semantic layer at scale. Defining metrics once and resolving them per context is now a product category. A large team starting fresh should start there. A small team still gets most of the benefit from one fact table, one metric file and one record per client. Either way, the hard parts are the same: decide the grain, declare what each metric is made of, and be explicit about what each audience actually sends.
The design scaled because it separated what every client shares, which belongs in one model and one catalog, from what makes each client different, which belongs in a small, explicit record. Start with the grain. Store the parts and compute the ratios. Make each audience's differences a few lines of configuration. Then onboarding the next client means writing a record.
The companion repository, config-driven-reporting, has a synthetic data generator, the shared model, the metric catalog, the KPI templates, settings for three fictional clients and one report template:
pip install -r requirements.txtmake
BrewBox tracks CPA on a Monday week and calls its sessions visits. PulseFit tracks CPA, has no session data, and has a radio source that only arrives weekly. Juniper tracks ROAS and CPA together under its own names. Add a fourth client to config/clients.yaml and the same template produces its report.
All images, unless otherwise noted, are by the author.
Val Ye is a Lead Business Intelligence Engineer in the streaming industry. She designed the architecture described here while at a media buying agency.
A practical approach to achieving interoperability in the data mesh through federated enterprise data modeling
June 21, 202410 min read
A visual guide through the GPT architecture with an application
November 21, 202316 min read
A turning point for data analysis?
October 9, 202510 min read
Working with sensitive data or within a highly regulated environment requires safe and secure cloud infrastructure for data processing...
August 16, 20247 min read
A detailed comparison of Milvus, Pinecone, Vespa, Weaviate, Vald, GSI and Qdrant
October 2, 20217 min read
A hands-on guide to creating an ES index from a CSV file, and to managing your data with the Python Elasticsearch Client
April 25, 20219 min read
A step-by-step tutorial to build and run Python Wheel Tasks on custom Docker images in Databricks (feat. Poetry and Typer CLI)
June 29, 202313 min read
Parquet vs ORC vs Avro vs Delta Lake
January 17, 202412 min read
The pros and cons of data mesh as well as steps that organizations should take to improve their data strategies.
July 14, 202111 min read
原文为英文,正文由自动抓取并保留原文。
原文发布于 Towards Data Science(How to Report for 100+ Clients With One Semantic Model),标题、摘要与正文由机器翻译,术语按行业惯例统一,未经人工逐句校订。