SageMaker AI 如何评估商品内容质量
A+ Content 是亚马逊商品详情页上的富媒体模块。品牌通过视觉素材传递独特的产品与品牌价值,帮助顾客做出明智的购买决策。使用高质量 A+ Content 的销售伙伴,其销售额相比未使用的同行提升 8–20%。从拥有庞大内部设计团队的成熟品牌,到资源有限的白手起家品牌,各类品牌都在使用 A+ Content,导致内容质量参差不齐。一个典型的 A+ Content 项目会把文字、图片和视频组合成一个连贯的产品叙事。孤立地评估单个素材,会漏掉这些素材协同配合所产生的质量。当你的内容横跨多个异构模块,且需要的是整体质量信号而非逐个素材的检查时,本文所述的多模型融合方法可以提供帮助。在本文中,我们结合 A+ Content 的场景来探讨这一问题。
A+ Content 为销售伙伴提供了创作自由,让他们能在商品详情页上展现真实的自我,而不受图片比例、文本字数等严格内容规范的限制。
这种灵活性虽然让品牌能够讲述引人入胜的故事,但也造成了内容构成与质量上的巨大差异。
借助质量评估与改进建议,品牌可以把普通内容转化为更连贯、更相关、更有用的高质量内容。改进后的内容能帮助顾客做出更明智的购买决策,并与品牌建立长期关系,从而提升销售伙伴的收入。
为实现这一目标,评估系统必须评估完整的内容体验,提供超越数字评分的可执行建议,并反映各产品品类之间的细微差异。现有方法难以同时满足所有这些要求,因此在本文中,你将看到一种新方法:使用视觉语言模型(VLM)来整体地理解和评估内容,以及一个基于扩散模型的生成组件,它根据由此得到的质量信号生成改进后的视觉素材。
在本文中,你将了解如何:
视觉语言模型(VLM)将图像编码器与大型语言模型(LLM)配对。编码器通常是视觉 Transformer(ViT),它把图像切分为图块(patch)并将其转换为嵌入向量,再由一个小型连接器将这些嵌入向量映射到语言模型的输入空间(Flamingo、LLaVA)。许多 VLM 复用 CLIP 的图像编码器,后者学习的是将图像与其文字说明相匹配。由于 VLM 经过遵循指令的训练,你可以向它提供一张图像以及一套评估标准,无需针对特定任务训练就能得到一份书面评估。当你需要与人工评审更趋一致时,可以在标注样本上对模型进行微调。这使得 VLM 成为按内容准则大规模检查产品图像的实用起点。
传统的计算机视觉模型已经能够为单个素材打分,例如标记出模糊图像或项目符号列表中的语法错误。使用 VLM 单独对每个素材进行评分,除此之外几乎带不来更多价值。然而,产品详情页将图像、文本和布局模块组合成一个整体叙事,其质量取决于这些部分如何协同工作。我们的方法将整个页面渲染为单张快照,并让 VLM 以顾客所看到的方式来评估它。
设想一个搅拌机页面,包含一张主图、一个突出刀片转速和容量的项目符号功能列表,以及一张搅拌机置于现代厨房中的生活方式照片。逐项检查时,每个素材都合格:图像清晰,项目符号语法正确,照片光线良好。但放在一起看,问题就会出现。项目符号可能宣传的是 64 盎司的搅拌杯,而生活方式照片展示的却是单份机型;或者生活方式照片可能位于主图上方,导致顾客先看到厨房再看到产品。由于素材的含义取决于它出现的位置以及周围的内容,这些问题只有在将页面作为一个整体进行评估时才会显现。快照为 VLM 提供了这种完整视图。将其用于生产会增加三项要求:分数必须符合专家质量标准,评估必须在大规模下准确且高效,并且每个结果都必须说明需要修复什么。
如图 1 所示,我们通过一种基于 VLM 的多模型融合架构来应对这些考量,该架构围绕适应性、性能和可解释性设计。以下各节将描述每个组件。
图 1:基于 VLM 的多模型融合方法框图,包括 VLM、OCR 和分类器模型
译文由英文原文机器翻译,术语按行业惯例统一,可在文末展开原文核对。
查看英文原文(How Amazon Marketplace evaluates content quality with Amazon SageMaker AI)
A+ Content is the rich media widget on the Amazon product detail page. Through visual assets, brands communicate unique product and brand value to help customers make informed purchase decisions. Selling partners using high-quality A+ Content boost their sales by 8–20 percent compared to those without it. A wide variety of brands, from established brands with large in-house design teams to bootstrapped brands with limited resources, use A+ Content, creating inconsistency in content quality. A typical A+ Content project combines text, images, and video into a cohesive product story. Evaluating each asset in isolation misses the quality that emerges from how those assets work together. When your content spans multiple heterogeneous modules and you need a holistic quality signal rather than per-asset checks, the multi-model fusion approach described in this post can help. In this post, we examine this problem in the context of A+ Content.
A+ Content provides creative freedom for selling partners to express their authentic selves on their product detail pages, without strict content specifications such as image ratio and text word count.
Although this flexibility allows compelling brand storytelling, it also creates substantial variation in content composition and quality.
With quality evaluation and improvement recommendations, brands can transform average content into high-quality content that is more coherent, relevant, and useful. This improved content helps customers make more informed purchasing decisions and build lasting relationships with brands, leading to improved revenue for selling partners.
To achieve this goal, an evaluation system must assess the complete content experience, provide actionable recommendations beyond numeric scores, and reflect the nuances across product categories. Existing approaches struggle to meet all these requirements simultaneously, so in this post, you will see a new approach using Vision-Language Models (VLMs) to understand and evaluate content holistically, and a diffusion-based generation component that produces improved visual assets from the resulting quality signals.
In this post, you will learn how to:
- Render complete ecommerce content as a single snapshot and evaluate it holistically with a VLM.
- Combine VLM semantic scores with OCR readability signals in a lightweight CatBoost classifier trained on expert annotations.
- Use SHAP to explain quality decisions and generate actionable improvement recommendations for selling partners.
- Implement the end-to-end pipeline on Amazon SageMaker AI, from data ingestion and annotation through model hosting, explainability, and production monitoring.
Opportunities and challenges in VLM-based evaluation
A vision language model (VLM) pairs an image encoder with a large language model (LLM). The encoder, often a vision transformer (ViT), splits an image into patches and turns them into embeddings, and a small connector maps those embeddings into the language model’s input space (Flamingo, LLaVA). Many VLMs reuse the image encoder from CLIP, which learned to match images with their captions. Because VLMs are trained to follow instructions, you can give one an image along with a rubric of evaluation criteria and get back a written assessment without task-specific training. When you need closer agreement with human reviewers, you can fine-tune the model on labeled examples. This makes VLMs a practical starting point for checking product images against your content guidelines at scale.
Conventional computer vision models can already score individual assets, for example flagging a blurry image or a grammar error in a bullet list. Using a VLM to grade each asset separately adds little beyond that. A product detail page, however, combines images, text, and layout modules into a single story, and its quality depends on how those pieces work together. Our approach renders the full page as a single snapshot and asks the VLM to evaluate it as customers see it.
Consider a blender page with a hero image, a bulleted feature list highlighting blade speed and capacity, and a lifestyle photo of the blender in a modern kitchen. Checked one by one, each asset passes: the image is sharp, the bullets are grammatical, and the photo is well lit. Viewed together, problems appear. The bullets might advertise a 64-oz pitcher while the lifestyle photo shows a single-serve model, or the lifestyle photo might sit above the hero image so customers see the kitchen before the product. Because an asset’s meaning depends on where it appears and what surrounds it, these issues only show up when the page is evaluated as a whole. The snapshot gives the VLM that complete view. Using it in production adds three requirements: scores must match expert quality standards, evaluation must be accurate and efficient at scale, and each result must explain what to fix.
As shown in Figure 1, we address these considerations through a VLM-based multi-model fusion architecture designed around adaptability, performance, and explainability. The following sections describe each component.
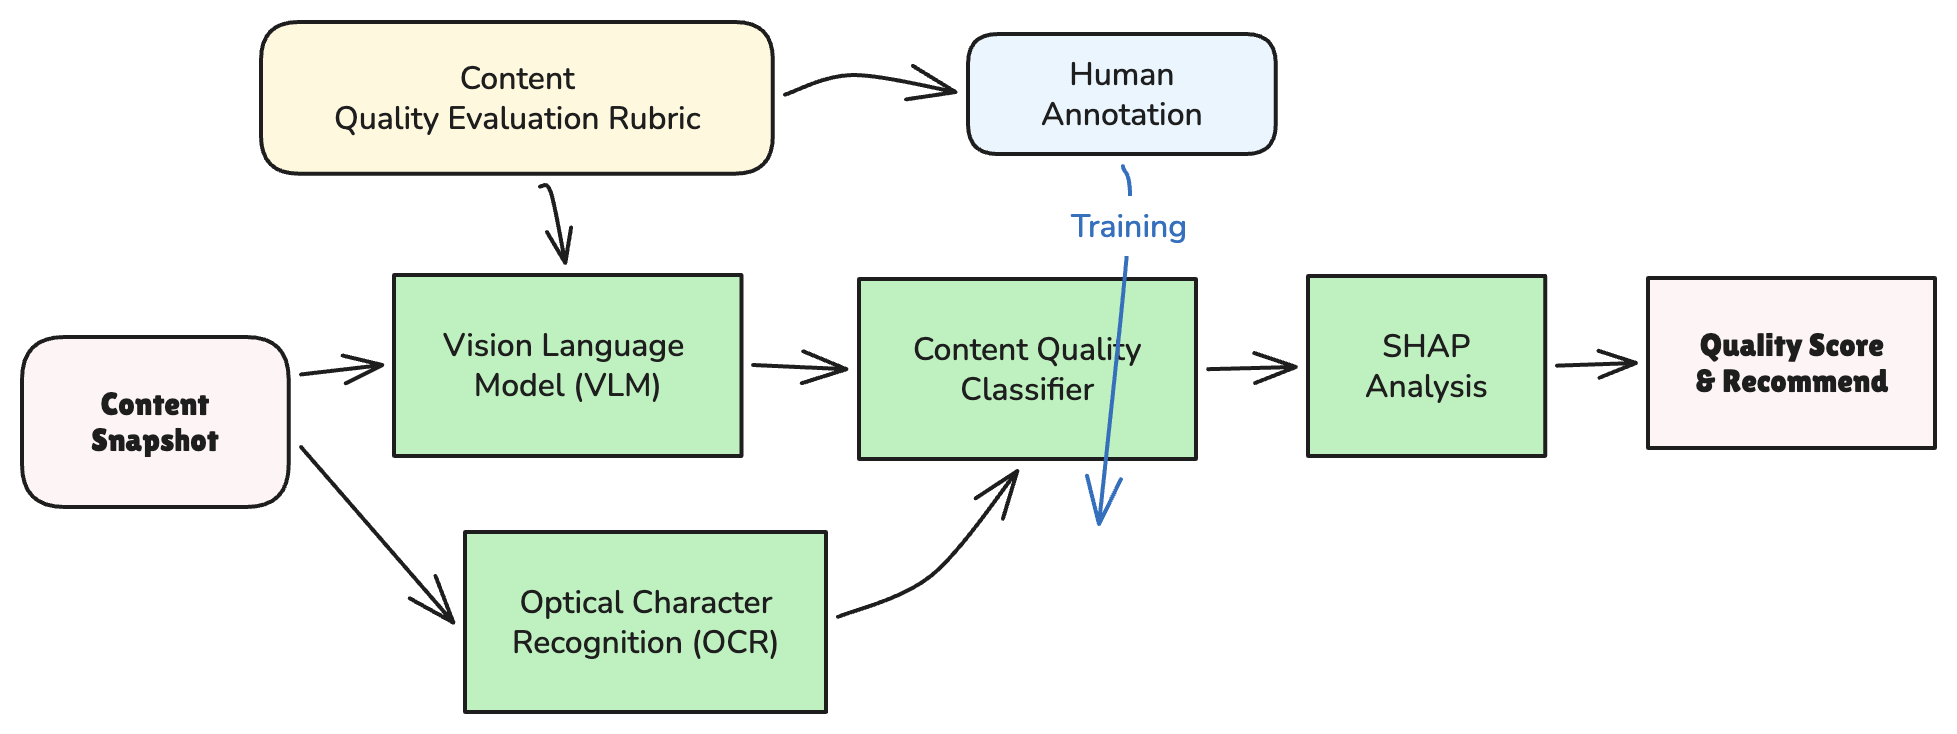
Figure 1: Block diagram of the VLM-based multi-model fusion approach, including VLM, OCR, and classifier models
Adaptive VLM content evaluation with expert annotations
A pretrained VLM prompted with a rubric scores content from its general knowledge, and those scores don’t always match ecommerce quality standards. Fine-tuning the VLM to close that gap would require GPU training infrastructure and, with only a few thousand labeled examples, carries a real risk of overfitting. Instead, we keep the VLM and rubric prompt fixed, use the VLM’s structured outputs as features, and train a CatBoost classifier on them to predict expert quality labels. CatBoost, a gradient-boosted decision tree library, performs well on small tabular datasets like this one. Because only the classifier is retrained, updating the system as annotations accumulate or criteria change takes a short CPU-only job rather than a foundation model fine-tuning run.
The VLM receives the page snapshot and a rubric prompt covering four quality dimensions: Visual Storytelling, Feature Presentation, A+ Layout, and Conversion Optimization. Each dimension has explicit criteria and point-deduction rules. For each dimension, the VLM returns a score from 0 to 10, a confidence value, and a natural-language rationale. For example, it lowers the score and explains why when a page lacks diverse modules or lifestyle imagery, or repeats information. The scores and confidence values become the classifier’s features, and the rationales help selling partners understand the result.
To build the training labels, one ecommerce marketing expert and four professional annotators independently rated 5,478 product detail pages from 10 product categories as high or low quality, using the same criteria. We assessed their ratings and took the majority vote to create a consensus label. The classes are nearly balanced (49.6 percent high quality), so a classifier can’t score well by predicting the majority class. To measure label reliability, we used Cohen’s kappa, which measures how often two raters agree after accounting for the agreement they would reach by chance. A score of 0 means agreement is no better than chance, 1 means perfect agreement, and values above 0.8 are generally considered strong. Each annotator scored between 0.845 and 0.915 when compared against the consensus label.
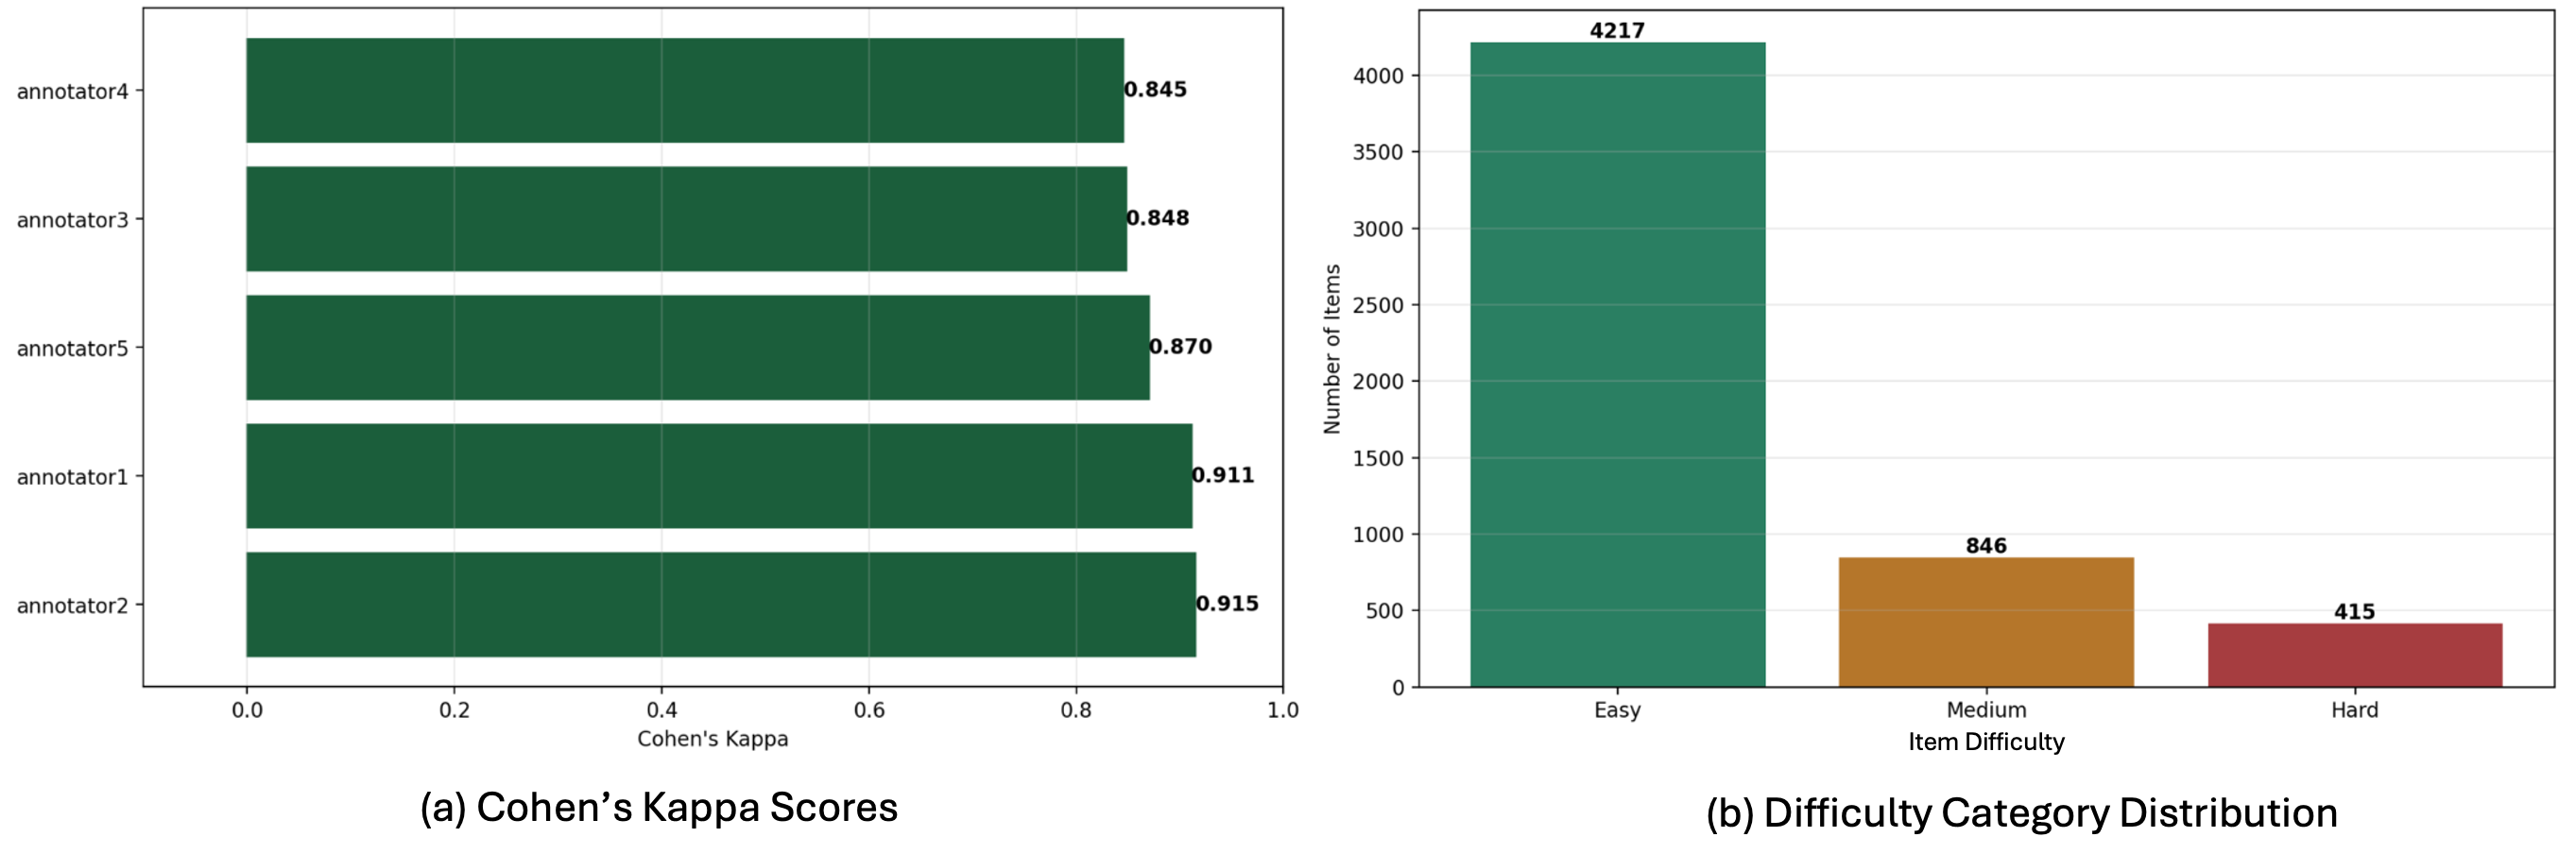
Figure 2: Annotator performance and content difficulty distribution. The near-even class split rules out majority-class bias (left), and the difficulty distribution explains the residual disagreement (right)
We compared the classifier with a baseline on a 20 percent holdout set (about 1,100 pages). The baseline averages the four VLM scores and applies a fixed threshold, so every dimension counts equally. The baseline reached 0.80 accuracy and an F1 score of 0.84 on the high-quality class. The CatBoost classifier, trained on the same scores, reached 0.89 accuracy and an F1 score of 0.90. Because the classifier learns how much each dimension matters and how the dimensions interact, its predictions match expert decisions more closely.
High-performance VLM content evaluation with OCR
VLMs capture the overall meaning and visual composition of a page well, but they are less reliable at fine-grained readability issues, such as how crowded the text is or how much space separates lines. Because of their language-model foundation, they can also favor long, detailed descriptions even when customers prefer concise text they can scan quickly. On a text-heavy page, a VLM might rate dense product information as helpful while customers struggle to read long sentences packed into a small area. To capture these issues, we use an optical character recognition (OCR) model hosted on SageMaker AI Inference to extract each block of text and its position, then calculate four quantitative signals: Text Density, Character Density, Spacing, and Overall Readability. Combining these OCR scores with the VLM’s semantic and visual assessment adds complementary information that improves quality classification.
From that output, we calculate four readability scores:
- Text Density: The share of the page area covered by text.
- Character Density: The number of characters per unit of page area.
- Spacing: How consistent and sufficient the whitespace is between words, lines, and paragraphs.
- Overall Readability: A combined signal from the three preceding scores.
Because these scores depend on layout rather than wording, two pages with identical text can score differently.
The fusion model combines the four VLM rubric scores and the four OCR scores into eight features and trains a CatBoost classifier on the same expert labels. Table 1 compares it with models trained on each feature set alone, using the same 20 percent holdout set.
On the same 20 percent holdout set, the CatBoost model using only OCR features achieved 0.82 accuracy and a 0.83 F1 score, while the model using only VLM features achieved 0.89 and 0.90. The fused OCR-VLM-CatBoost model outperformed both standalone models, reaching 0.94 accuracy and a 0.95 F1 score. The 0.05 improvement in both metrics over the VLM-only model demonstrates that OCR isn’t a replacement signal. It complements the VLM’s holistic judgment with fine-grained text-readability information.
| Configuration | Accuracy | F1 Score |
| Baseline (averaged VLM scores + threshold) | 0.80 | 0.84 |
| OCR-only CatBoost | 0.82 | 0.83 |
| VLM-only CatBoost | 0.89 | 0.90 |
| Fused OCR-VLM CatBoost | 0.94 | 0.95 |
Explainable VLM content evaluation with SHAP
A quality label alone doesn’t tell selling partners what to fix first. To find which dimensions drove each decision, we use SHapley Additive exPlanations (SHAP), which assigns each feature a value showing how far it pushed a prediction toward high or low quality. Because the VLM and OCR scores feed the same classifier, SHAP measures both on a common scale. Raw scores can’t do this: a Visual Storytelling score of 6 and a high Character Density don’t tell you which one mattered more to the decision.
Across the holdout set, the most influential features were OCR Character Density (mean absolute SHAP value 1.1), OCR Overall Readability (1.0), and VLM Visual Storytelling (1.0). They were followed by A+ Layout (0.8), Feature Presentation (0.6), and Conversion Optimization (0.4). Both OCR and VLM features rank near the top, so the classifier depends on both sources.
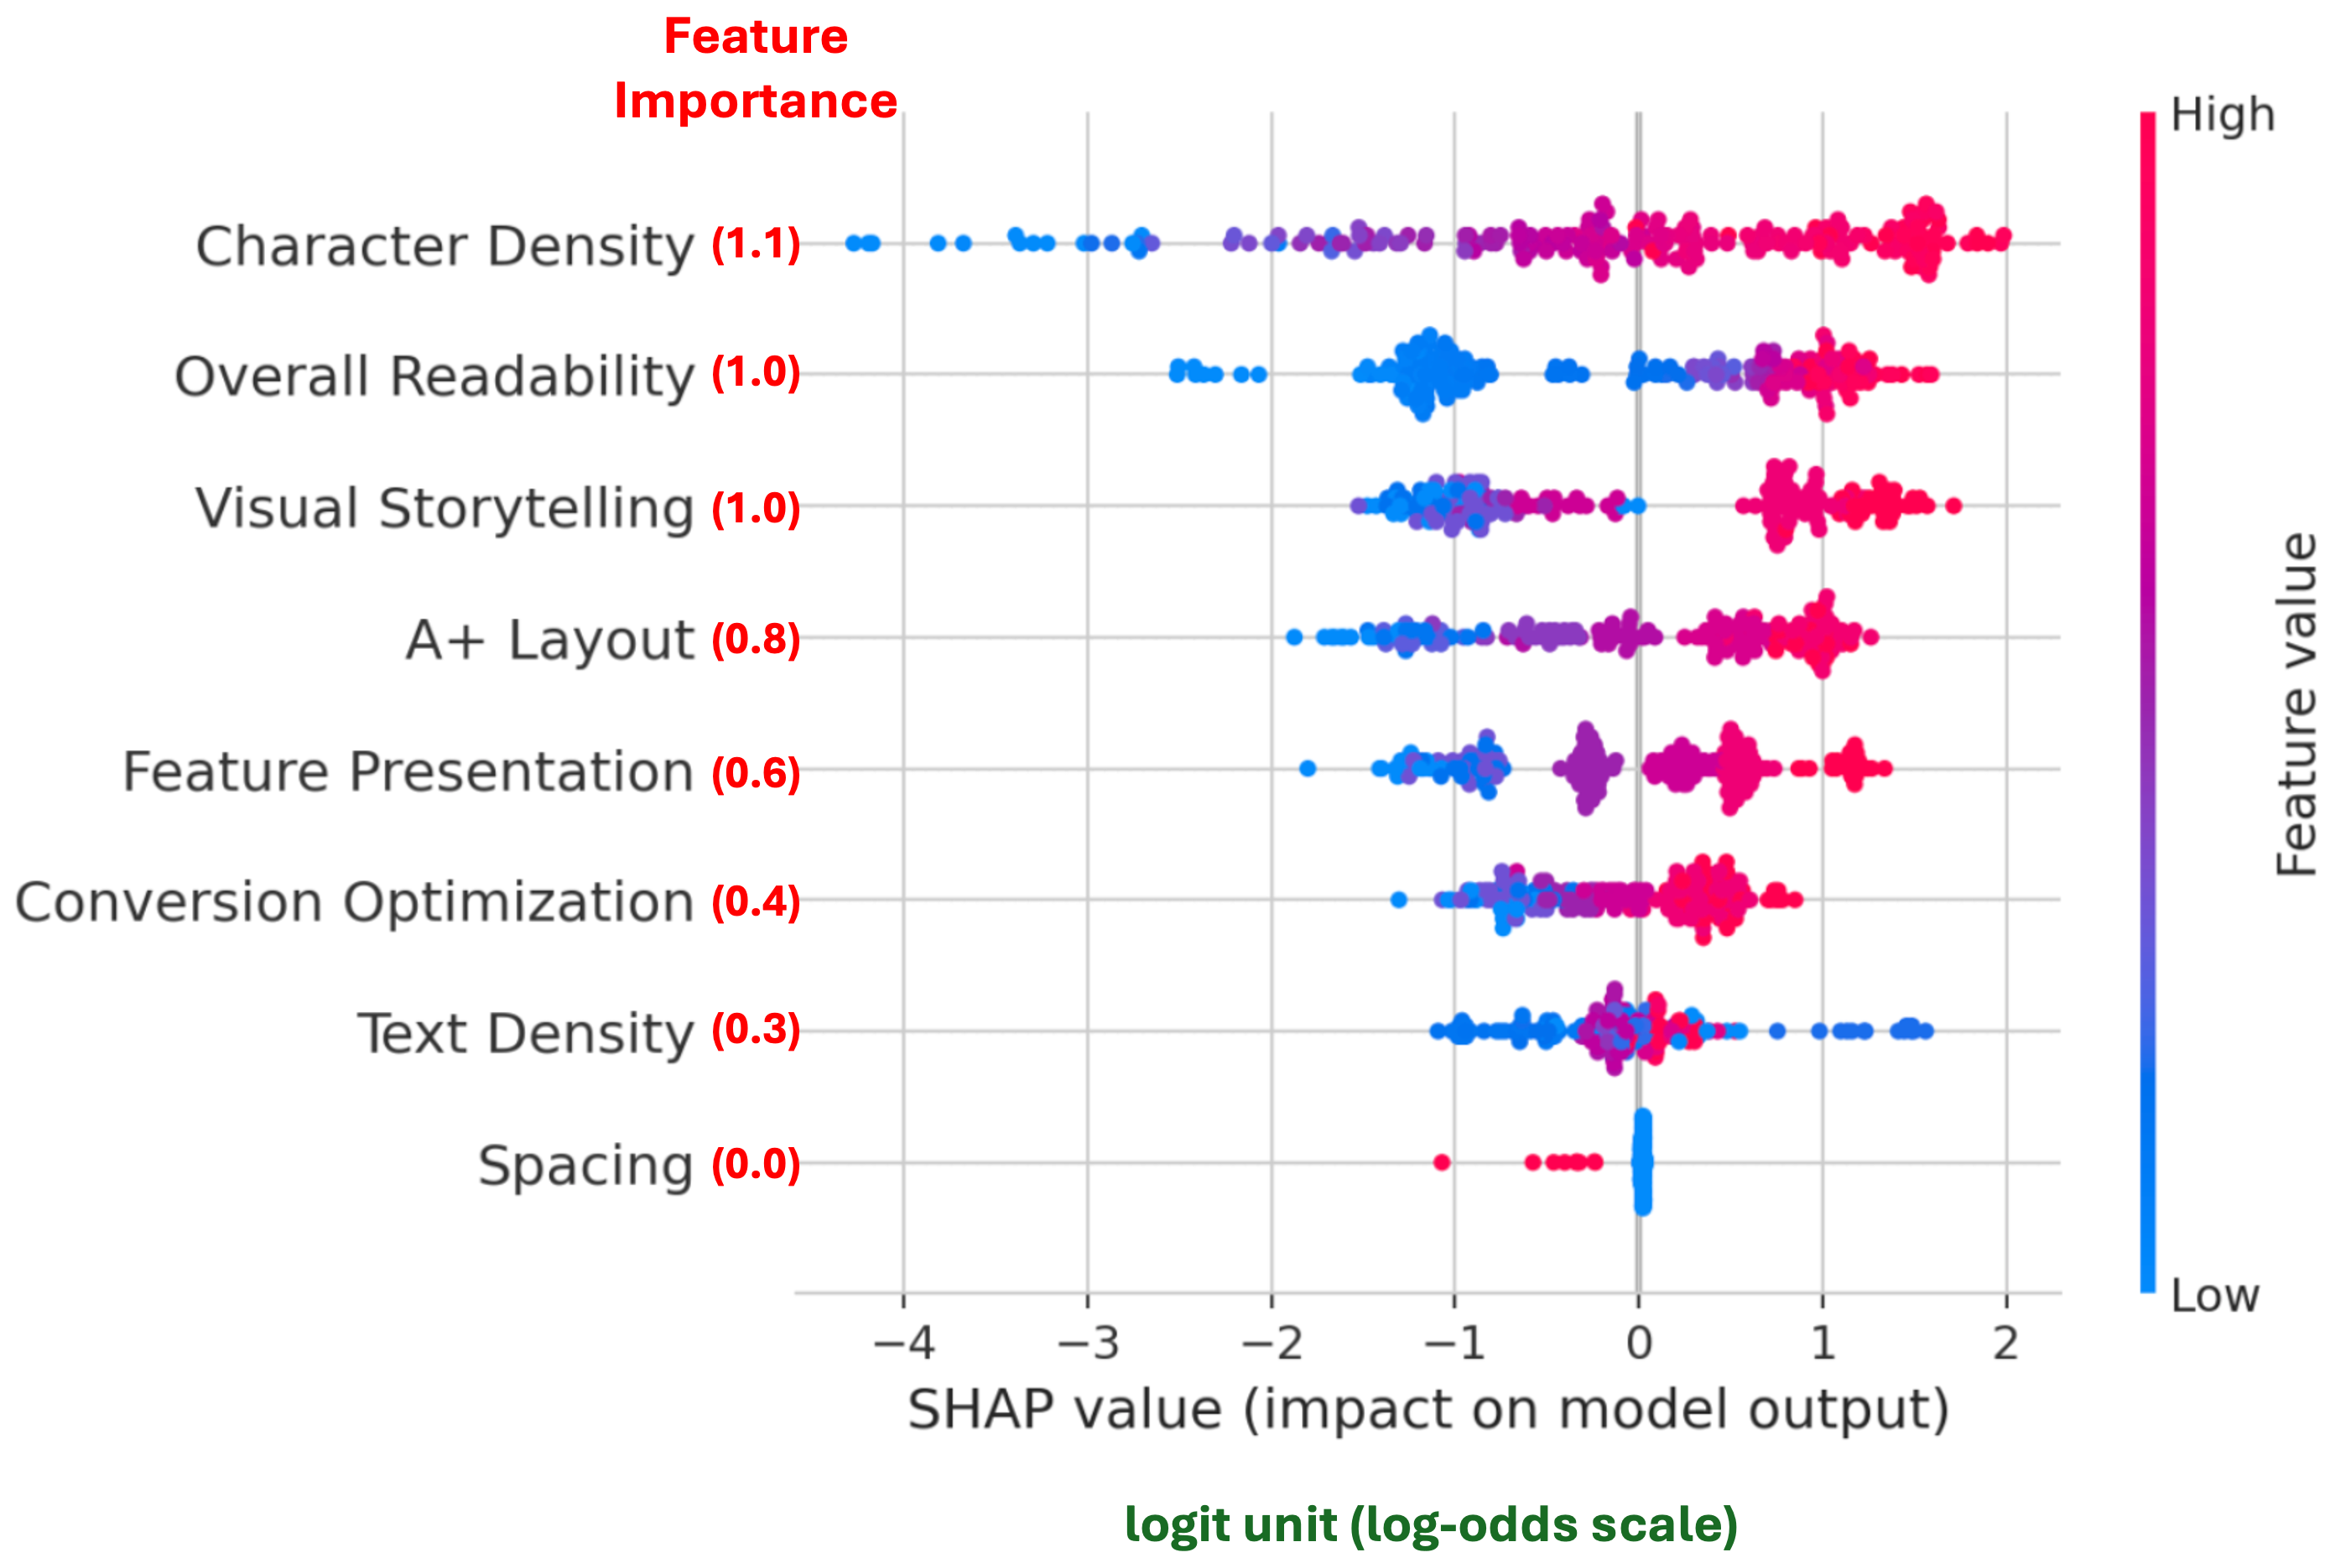
Figure 3: Global SHAP value distributions for all VLM and OCR features
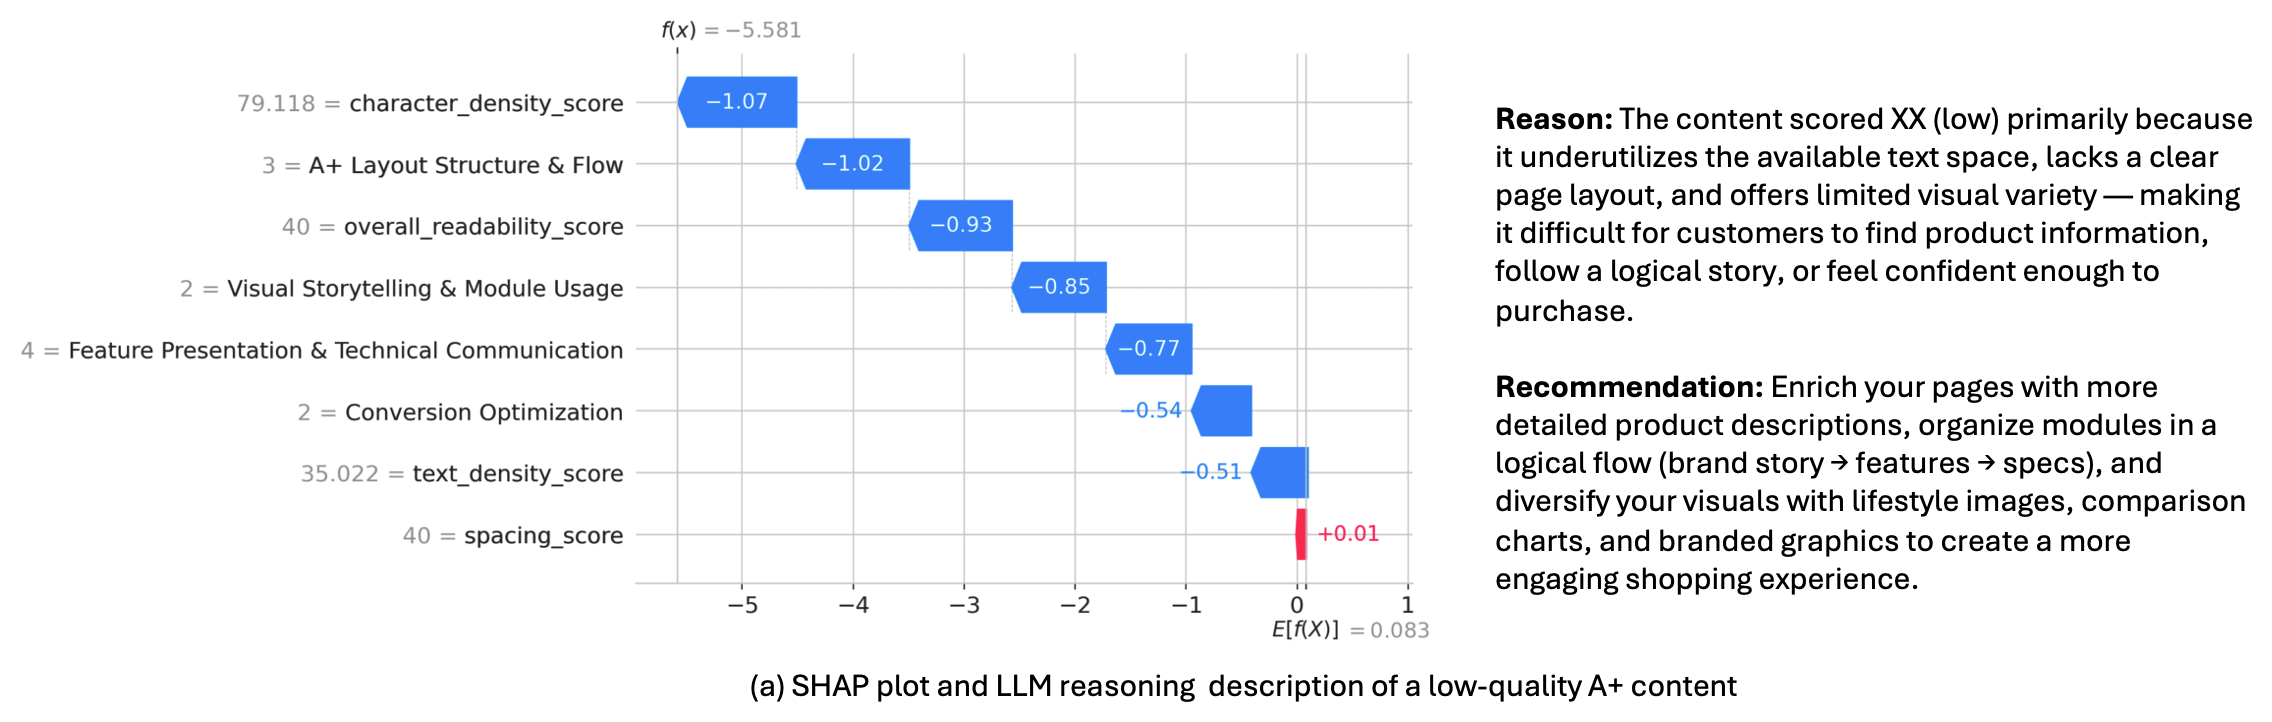
For an individual page, SHAP shows which features lowered the decision. For each page classified as low quality, we rank the eight features by SHAP value, then pass the most negative features, the product category, and ecommerce best practices, along with the VLM’s rationales, to an LLM, which turns them into prioritized, specific actions.
Figure 4 shows two local SHAP plots with the LLM reasoning grounded in the SHAP results, for a low-quality and a high-quality A+ Content sample. For example, if A+ Layout has a SHAP value of -1.2 and Visual Storytelling has -0.3, the system prioritizes restructuring the layout and rebalancing text and images, followed by improvements to the imagery.
 |
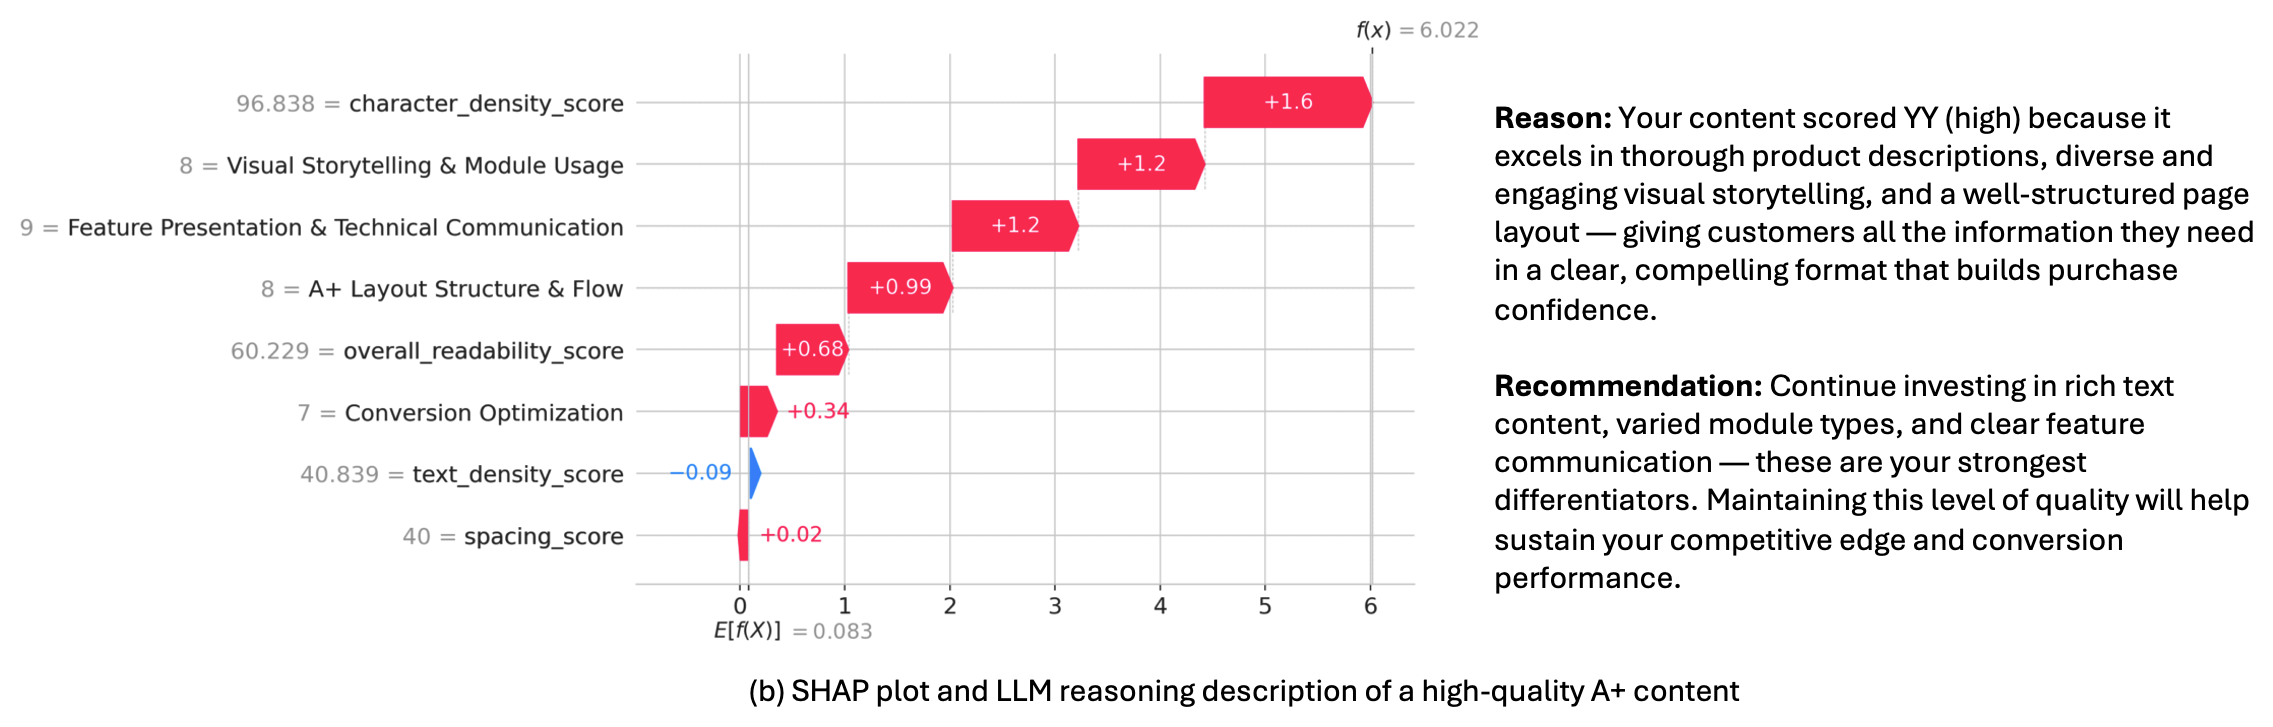 |
Figure 4: Two local SHAP value distributions for all VLM and OCR features: (a) a low-quality case, where most features contribute negatively and drive an improvement-requested recommendation; (b) a high-quality case, where most features contribute positively
We validated the effectiveness of these explanation-based recommendations by measuring quality scores after selling partners revised their content. The average post-revision quality score increased by 1.4 points on a 10-point scale on a statistically significant sample. SHAP contributions can therefore be translated from decision explanations into actionable improvement priorities and methods. Explainability is therefore not merely an auxiliary capability for understanding the model. It functions as a feedback mechanism that materially improves content quality.
Results
The complete system scores each page snapshot with the VLM and OCR, combines the four VLM scores and four OCR scores into a single feature vector, and passes it to a CatBoost classifier trained on expert labels. SHAP then identifies which features drove each decision. To measure what each component adds, we compared four configurations on the same 20 percent holdout set. The holdout set comes from 5,478 product detail pages across 10 product categories, including Furniture, Shoes, Grocery, Beauty, and Apparel.
The baseline averages the four VLM scores and applies a fixed threshold, so every dimension counts equally. It reached 0.80 accuracy and an F1 score of 0.84. Training a CatBoost classifier on the same scores lets the model learn which dimensions matter most and how they interact, which raised accuracy to 0.89 and F1 to 0.90. A classifier trained on the OCR scores alone reached 0.82 accuracy and an F1 score of 0.83. Combining the VLM and OCR scores gave the best results, with 0.94 accuracy and an F1 score of 0.95. That’s 14 percentage points higher accuracy and 11 points higher F1 than the baseline.
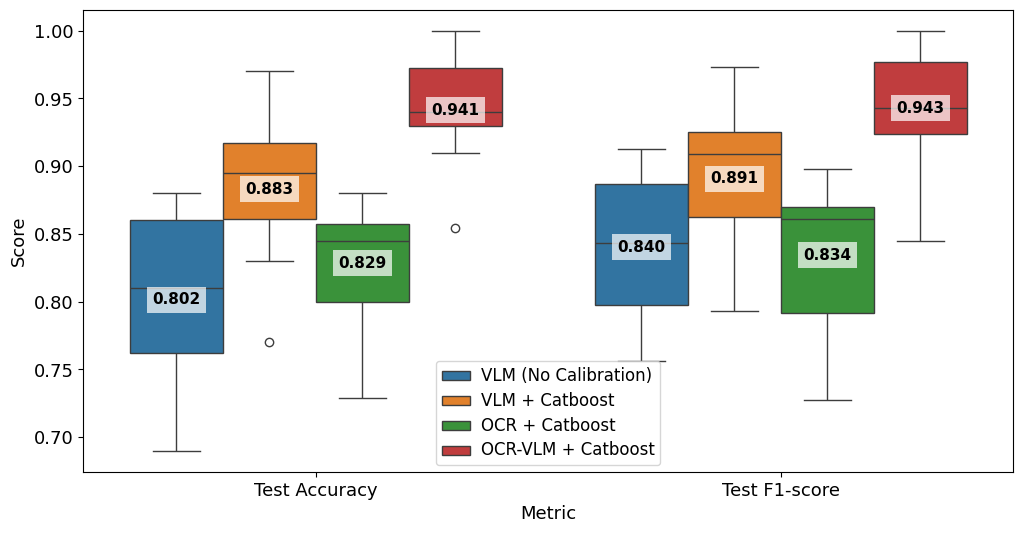
Figure 5: Accuracy and F1 comparison across VLM and OCR evaluation configurations
Examining each performance gain separately makes the value of the integrated approach clearer. CatBoost calibration first reduces the limitations of a fixed threshold by learning dimension-specific weights and nonlinear decision boundaries. Adding OCR features then supplies text-readability signals that the VLM can miss. Overall, the final fusion model improves accuracy by 0.14 and F1 by 0.11 over the baseline.
We also changed the VLM backbone in an additional experiment on a single-category dataset containing 499 content projects. With a lighter VLM variant, the baseline achieved 0.74 accuracy and a 0.72 F1 score, while the OCR-VLM-CatBoost model achieved 0.90 for both metrics. With a more capable VLM variant, the baseline achieved 0.79 accuracy and a 0.84 F1 score, while the fusion model achieved 0.94 and 0.95. The fusion approach improved accuracy by 0.16 and 0.15 for the two VLMs, respectively, demonstrating that complementary OCR features deliver consistent gains without depending on a particular foundation model.
To reduce development costs while retaining access to high-performance foundation models, the system freezes the VLM and trains only the low-overhead classifier. In production, a worldwide A/B experiment that adjusted the visibility of low-quality A+ Content based on the model’s quality decisions produced a statistically meaningful improvement in Ordered Product Sales (OPS). Beyond aligning closely with expert judgment, the integrated system provides a quality signal that can support customer-experience and business decisions at scale.
Implementation on Amazon SageMaker AI
This section describes how the architecture is implemented end-to-end on Amazon SageMaker AI. Each stage of the pipeline from content rendering and expert annotation through VLM scoring, OCR extraction, feature aggregation, classifier training, SHAP-based explainability, and production monitoring maps to a managed SageMaker AI capability. This design keeps the operational overhead low. The following steps walk through how each component is deployed, connected, and maintained in production.
Figure 6: Architecture of the content-quality system on Amazon SageMaker AI
1. Content snapshot rendering and data ingestion: The complete A+ Content experience is rendered, capturing how customers actually see the page.
SageMaker Processing Jobs run containerized rendering jobs at scale, decoupling data preparation from training and inference compute.
2. VLM scoring and model hosting: Annotators independently label content using the quality rubric. Their aggregated consensus labels become the training targets. The frozen VLM receives each snapshot plus a rubric prompt and outputs four scores from 0 to 10 (Visual Storytelling, Feature Presentation, A+ Layout, Conversion Optimization), each with a confidence value and rationale. SageMaker AI Inference hosts the VLM with the deployment option that fits the workload:
- Real-Time Endpoints for synchronous, low-latency scoring of individual listings.
- Asynchronous Endpoints for large payloads such as high-resolution snapshots, where a slight delay is acceptable.
- Batch Transform for offline bulk scoring at catalog scale.
These options support automatic scaling, managed infrastructure, and GPU instance selection.
SageMaker Training Jobs can optionally be used to further tune or distill the VLM (for example, Low-Rank Adaptation (LoRA) adapters, knowledge distillation into a smaller model) if teams want a specialized, lower-latency variant. Avoid this to keep recalibration cost-effective and VLM-agnostic.
3. OCR readability extraction: In parallel, OCR extracts text and bounding-box positions from each snapshot and computes four readability signals: Text Density, Character Density, Spacing, and Overall Readability.
SageMaker JumpStart provides pre-trained, single-action deployable models from its model hub, avoiding the need to source, package, and benchmark models from scratch. Teams select a model, optionally fine-tune it without managing infrastructure using SageMaker Serverless Model Customization on ecommerce content, and deploy directly. SageMaker AI Inference then hosts the chosen OCR model as an endpoint.
4. Feature aggregation and storage:
SageMaker Feature Store provides both online (low-latency inference) and offline (batch training) access to the same features, avoiding training-serving skew. Teams can share features across the organization, so downstream consumers can reuse the same curated features.
5. Classifier training: A CatBoost classifier is trained on the eight-dimensional feature vector against expert annotations to learn non-uniform dimension weights and nonlinear decision boundaries. SageMaker Training Jobs can be used here again. You can register trained models directly to SageMaker Model Registry for versioning, approval workflows, and production deployment.
6. SHAP explainability and recommendations: SageMaker Processing Jobs support Bring Your Own (BYO) processing code, which you can use to derive SHAP values and model explainability metrics.
7. Production monitoring and re-training: In production, ML models naturally degrade over time. Customer aesthetics shift, new A+ module types launch, product categories evolve, and seller behavior changes. The scoring patterns the classifier learned from historical annotations gradually fall out of alignment with what quality means today, leading to silent accuracy erosion if left unchecked. Continuous monitoring closes this gap by detecting when the live data distribution or model predictions have drifted far enough from the training baseline to warrant recalibration.
SageMaker AI ModelOps provides a collection of examples and resources to help you operationalize generative AI and machine learning workloads on SageMaker AI.
SageMaker AIOps provides the tool to track data quality, model quality, and feature-attribution drift. SageMaker Pipelines also automates the re-training workflow end-to-end when drift thresholds are breached.
8. Diffusion-based content generation: Closing the loop, the quality scores and SHAP-derived recommendations condition a diffusion model that generates improved A+ image assets. Rather than leaving sellers to interpret recommendations and create new content from scratch, the system produces ready-to-use visual assets (upgraded lifestyle imagery, rebalanced layouts, or enhanced product shots) that directly address the dimensions SHAP flagged as most negatively contributing. These generated assets and natural-language improvement suggestions are surfaced to sellers, so they can upgrade their listings on amazon.com.
Conclusion
In this post, we showed how to evaluate product detail pages as customers see them by rendering each page as a single snapshot and scoring it with a VLM. We also walked through implementing the system on Amazon SageMaker AI. We built the system around three goals. For adaptability, we keep the VLM fixed and train a CatBoost classifier on its rubric scores, so the system matches expert judgment and can be updated with a short CPU-only job. For performance, we add OCR readability scores that catch dense or poorly spaced text the VLM misses. For explainability, SHAP identifies which features drove each decision, and an LLM turns those results into prioritized recommendations for selling partners.
On 5,478 product detail pages from 10 product categories, the fused model reached 0.94 accuracy and a 0.95 F1 score, 14 and 11 percentage points above the averaged-score baseline. Pages revised using the recommendations improved their quality score by an average of 1.4 points on a scale of 10.
Content quality standards differ across product categories, languages, and marketplaces, and our expert annotations can’t fully represent every context. Next, we plan to evaluate more efficient VLM backbones and inference methods to run the system on a global catalog.
About the authors
James (Sungjin) Kim
James is a Senior Applied Scientist at Amazon, with over 15 years of experience driving cross-disciplinary innovation across e-commerce, cloud infrastructure, consumer electronics, and pioneering scientific research. He is a recognized expert in AI Agent, Generative AI, Large Language Models (LLMs), Vision-Language Models (VLMs), and Reinforcement Learning (RL).
Harsh Asnani
Harsh is a Sr. Worldwide Generative AI Specialist Solutions Architect at AWS specializing in ML theory, MLOps, and Generative AI frameworks. His background is in Applied Data Science with a focus on operationalizing AI workloads in the cloud at scale.
David Oh
David leads the Go-To-Market (GTM) for Amazon SageMaker Managed Inference, HyperPod Inference, Model Standardization, ModelOps for enterprise customers. He is also a subject matter expert in SageMaker Model Deployment, Inference Optimization for cost saving, performance and latency improvement for customer’s open weights models in SageMaker Managed Inference and HyperPod. He also oversees Voice AI and Video AI 3P model SageMaker and Marketplace hosting.
Yixuan Song
Yixuan is a Senior Product Manager at Amazon, working on AI-powered products that help sellers make better business decision and grow their businesses. She partners with applied science and engineering teams to build scalable solutions powered by large language models and machine learning, with a focus on turning complex data and insights into actionable recommendations for sellers.
Simai Zhang
Simai is a Data Scientist at Amazon, focusing on machine learning solutions that help Sellers succeed with their new product launches. She has expertise in traditional machine learning and natural language processing models, with experience across a variety of tools that empower Selling Partners to make data-driven decisions.
正文保留英文原文,标题与摘要由机器翻译。
原文发布于 AWS Machine Learning(How Amazon Marketplace evaluates content quality with Amazon SageMaker AI),标题、摘要与正文由机器翻译,术语按行业惯例统一,未经人工逐句校订。


