光驱动 AI 检测深度伪造准确率近 98%
来自研究机构
这种光驱动 AI 能以近 98% 的准确率识别深度伪造
日期:2026年10月1日 来源:中国科学院长春光学精密机械与物理研究所 Light Publishing Center 摘要:UCLA 的研究人员构建了一套利用光同时分析十余段视频的 AI 系统,识别深度伪造的准确率接近 98%。其速度、低能耗需求以及抗攻击能力,可能使其成为筛查日益泛滥的 AI 生成视频的有力工具。分享:
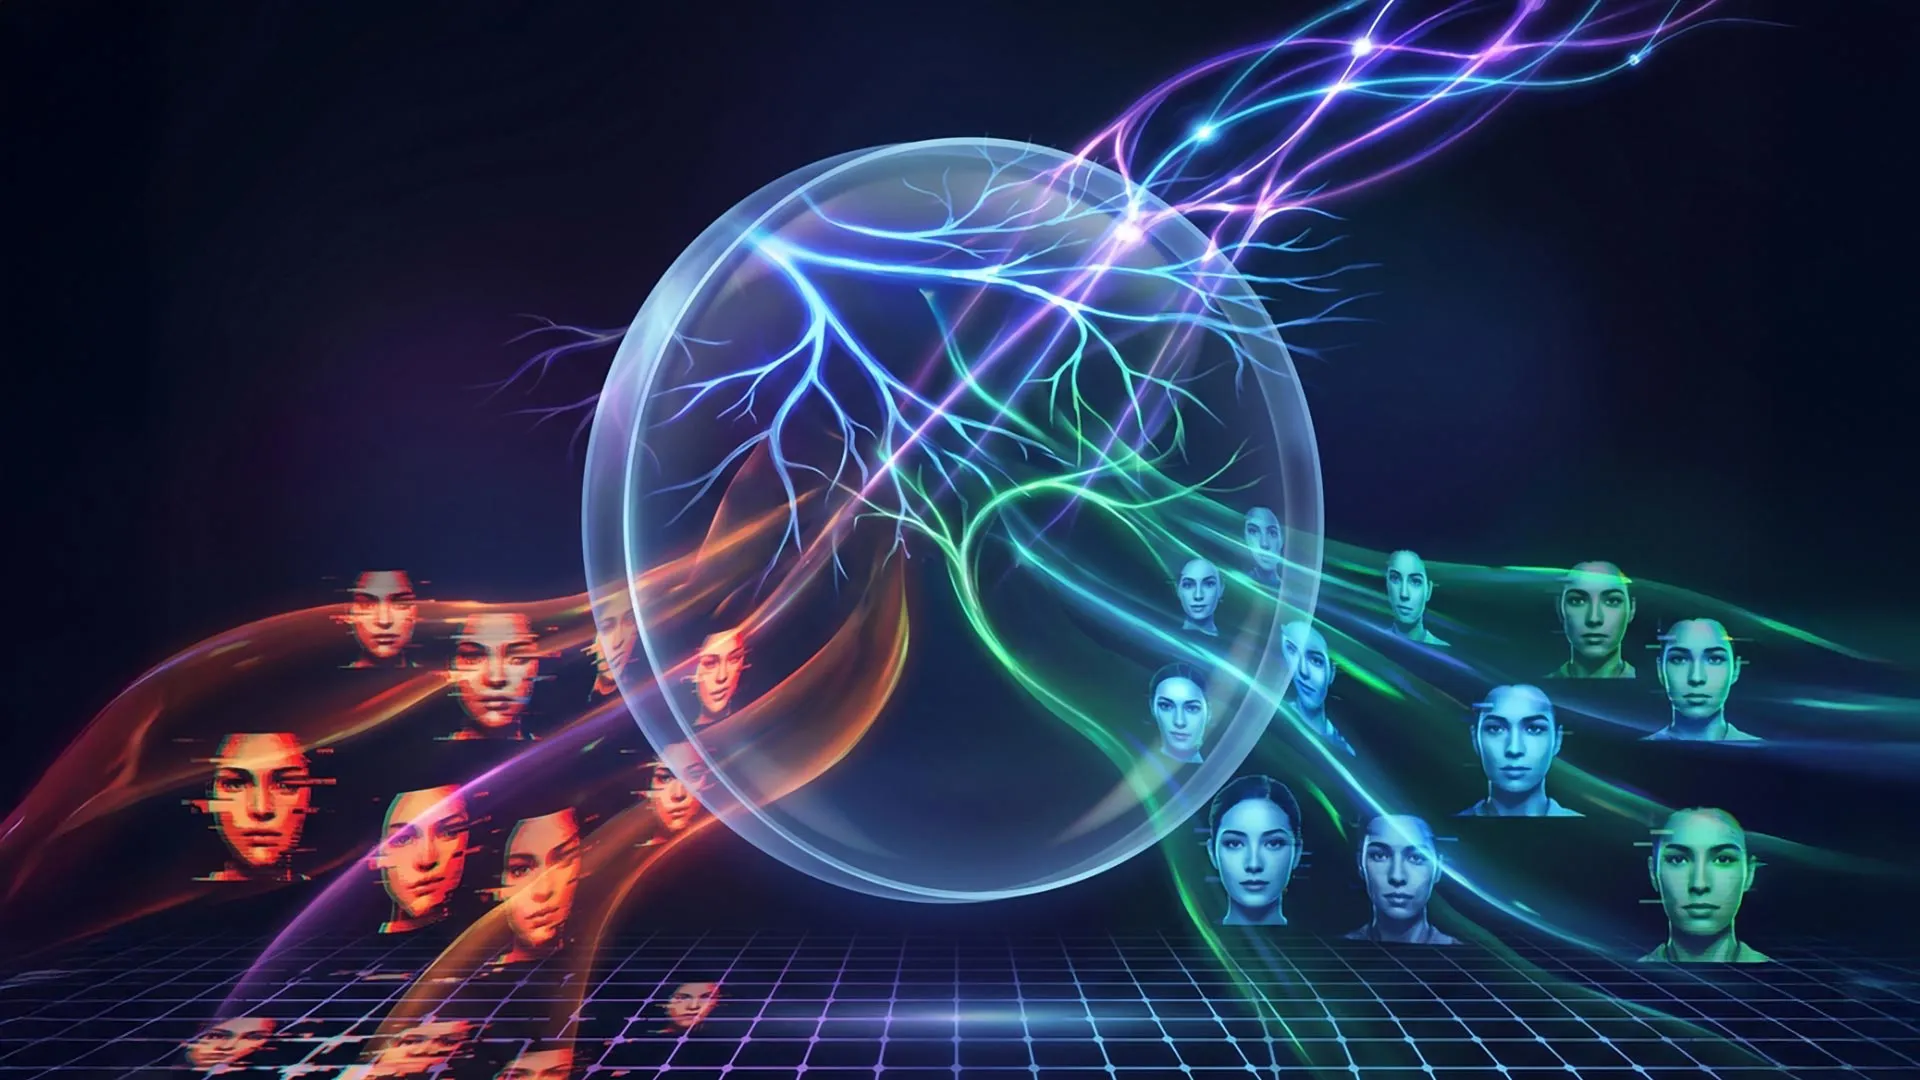
一种利用光衍射检测深度伪造视频的新型光学 AI 技术的艺术示意图。图片来源:Ozcan Lab @UCLA
加利福尼亚大学洛杉矶分校(UCLA)的研究人员创造了一种新型光学神经处理器,利用光来帮助快速、准确地识别深度伪造视频。与通常使用数字硬件逐段检查视频的传统系统不同,UCLA 的这项技术可以同时分析 15 路或更多视频流。
关键区别在于,检测过程的一部分是通过光的物理传播来完成的。这使得许多视频可以在单次光学通路中同时被评估,而不需要每个视频分别经过传统的数字处理流水线。
该技术详述于发表在 eLight 上的研究《Scalable, Energy-Efficient Optical-Neural Architecture for Multiplexed Deepfake Video Detection》(可扩展、高能效的光学神经架构,用于多路复用的深度伪造视频检测)。研究人员将这套光学 AI 系统设计为高吞吐、抗攻击的第一层防线,用于筛查大量被篡改和 AI 生成的视频。
深度伪造检测日益严峻的挑战
生成式 AI 的快速进步使合成视频越来越逼真,这也加大了对既能保证准确、又能大规模运行的检测系统的需求。
许多先进的深度伪造检测器依赖海量的数字计算。单次分析可能需要数千亿次浮点运算,而且视频通常是按顺序逐个处理的。随着需要检查的内容增多,处理时间和能耗也会随之成比例上升。
数字检测系统还面临另一个问题。攻击者可以刻意对伪造视频做细微改动,目的是迷惑检测器,让被篡改的画面看起来像真的。
Aydogan Ozcan 教授及其 UCLA 团队开发了一套数字—光学混合系统,意在同时解决这两个难题。
一个轻量级数字编码器先提取每段视频的紧凑信息,包括空间、频谱和时间特征。这些信息随后被转换为相位图案,并显示在可编程空间光调制器上。
由此形成的光波前随后穿过一个基于自由空间的被动光学解码器。在另一端,配对的光学探测器直接为每段视频生成真实性评分。
实际上,该系统用一个可并行处理多路视频流的物理过程,取代了计算量巨大的数字解码网络。
同时处理 15 段视频,准确率接近 98%
在使用可见光的实验中,该处理器在每次光学通过时可同时检测 15 个 Celeb-DF 视频。
它实现了 97.79% 的平均检测准确率,以及 99.86% 的灵敏度和 95.72% 的特异度。灵敏度衡量的是系统成功识别被篡改视频的能力,因此对于一款旨在防止虚假内容漏检的筛查工具而言,如此高的灵敏度尤为重要。
99.86% 的灵敏度对应约 0.14% 的平均假阴性率。换言之,只有极小一部分被篡改的视频被错误地判定为真实。
研究人员还进一步提升了系统的能力,将单次光学通过可处理的视频数量提高到 18 个。即便在这一水平下,平均检测准确率仍保持在 96.13%。
更多光学层可提升性能
研究团队发现,通过增加其无源光学解码器的物理深度,处理器的能力也能进一步提升,而不会显著增加能耗或推理延迟。
在测试难度更高的深度伪造篡改时,研究人员加入两个经过优化的无源衍射层,检测准确率提升了约 6.8%。
这些纯相位衍射层可以制造成无源、静态的光学结构/表面。它们通过光的衍射完成额外计算,这意味着系统在执行推理时无需额外的电力。
这种方法有望实现更复杂的处理,而无需承担更大的数字神经网络通常伴随的同等能耗成本。
用 Google VEO-3 视频测试该系统
研究人员并未将实验局限于传统的换脸深度伪造。他们还用 Google 的 VEO-3 模型生成的视频对处理器进行了测试。
较新的生成式 AI 系统可以生成缺乏早期深度伪造技术许多明显伪影的视频,这让那些主要基于旧式操纵手法训练的检测器更难识别。
仅需极少的微调,该光学处理器在实验中于此前未见过的 VEO-3 视频上达到了 94.80% 的准确率和 97.61% 的灵敏度。
这些结果表明,随着生成式 AI 技术持续演进,该方法有可能随之适应。
一种旨在更难被愚弄的深度伪造检测器
该光学系统还表现出对黑盒对抗攻击的抵抗力,并具有针对白盒攻击的固有防护能力。
这种安全性部分源于该探测器执行计算的物理方式。由于部分推理过程是通过衍射完成的,光学模型的重要参数实际上被嵌入到了硬件之中。
攻击者很难测量、复现或逆向工程这些参数。这使得重建该探测器、并设计出能够规避它的精心定制的对抗性改动变得困难得多。
当视频受到图像噪声、模糊、JPEG 压缩以及实验性失准的影响时,该处理器仍能持续可靠地工作。研究人员表示,这些结果说明光计算可以为某些人工智能系统提供更安全、更可靠的基础。
抵御深度伪造的第一道防线
UCLA 的这款处理器并非要完全取代精密的数字探测器,而是被设计为更大检测系统中一个高度灵敏的第一阶段。
海量视频可以先经过并行光处理器。被判定为可疑的内容随后可被送往计算需求更高的数字模型,进行更细致的最终评估。
这样的系统可以结合两种方法的优势。光处理可以提供并行运行、较低的解码器能耗需求、高灵敏度、抗对抗攻击能力,以及适应更新型 AI 视频生成器的能力;而传统数字系统则可在必要时提供更深入的分析。
研究人员表示,这种组合最终可能有助于大规模内容审核、媒体鉴伪、监控以及其他对安全性至关重要的 AI 应用。
本研究的作者为 Parnian Ghapandar Kashani 与 Shiqi Chen 博士,二人贡献相同,以及 Aydogan Ozcan 教授。研究人员分别隶属于 UCLA 电子与计算机工程系、UCLA 生物工程系以及加州纳米系统研究所。
材料由中国科学院(CAS)长春光学精密机械与物理研究所 Light Publishing Center 提供。注:内容可能因风格和篇幅而经过编辑。
Parnian Ghapandar Kashani, Shiqi Chen, Aydogan Ozcan. Scalable, energy-efficient optical-neural architecture for multiplexed deepfake video detection. eLight, 2026; 6 (1) DOI: 10.1186/s43593-026-00143-y
Light Publishing Center, Changchun Institute of Optics, Fine Mechanics And Physics, CAS. "This light-powered AI can spot deepfakes with nearly 98% accuracy." ScienceDaily. ScienceDaily, 1 October 2026. .
Light Publishing Center, Changchun Institute of Optics, Fine Mechanics And Physics, CAS. (2026, October 1). This light-powered AI can spot deepfakes with nearly 98% accuracy. ScienceDaily. Retrieved November 5, 2026 from www.sciencedaily.com/releases/2026/09/260929053534.htm
Light Publishing Center, Changchun Institute of Optics, Fine Mechanics And Physics, CAS. "This light-powered AI can spot deepfakes with nearly 98% accuracy." ScienceDaily. www.sciencedaily.com/releases/2026/09/260929053534.htm (accessed November 5, 2026).
译文由英文原文机器翻译,术语按行业惯例统一,可在文末展开原文核对。
查看英文原文(This light-powered AI can spot deepfakes with nearly 98% accuracy)
This light-powered AI can spot deepfakes with nearly 98% accuracy | ScienceDaily
from research organizations
This light-powered AI can spot deepfakes with nearly 98% accuracy
Date:October 1, 2026Source:Light Publishing Center, Changchun Institute of Optics, Fine Mechanics And Physics, CASSummary:UCLA researchers built an AI system that uses light to analyze more than a dozen videos simultaneously, detecting deepfakes with nearly 98% accuracy. Its speed, low energy demands, and resistance to attacks could make it a powerful tool for screening the growing flood of AI-generated video.Share:
 Artistic depiction of a new optical AI technology that detects deepfake videos with light diffraction. Credit: Ozcan Lab @UCLA
Researchers at the University of California, Los Angeles (UCLA) have created a new optical-neural processor that uses light to help identify deepfake videos quickly and accurately. Unlike conventional systems that typically examine videos one after another using digital hardware, the UCLA technology can analyze 15 or more video streams at the same time.
The key difference is that part of the detection process takes place through the physical propagation of light. This allows many videos to be evaluated simultaneously during a single optical pass rather than requiring each one to move separately through a conventional digital processing pipeline.
The technology is detailed in the study "Scalable, Energy-Efficient Optical-Neural Architecture for Multiplexed Deepfake Video Detection," published in eLight. The researchers designed the optical AI system to serve as a high-throughput, attack-resilient first layer of defense for screening large amounts of manipulated and AI-generated video.
The Growing Challenge of Deepfake Detection
Rapid improvements in generative AI have made synthetic videos increasingly realistic, increasing the need for detection systems that are both accurate and capable of operating at large scale.
Many advanced deepfake detectors depend on enormous amounts of digital computation. A single analysis can require hundreds of billions of floating-point operations, and videos are often processed sequentially. As more content must be checked, both the processing time and energy requirements can rise proportionally.
Digital detection systems face another problem. Attackers can deliberately alter fake videos in subtle ways designed to confuse a detector and make manipulated footage appear authentic.
Professor Aydogan Ozcan and his UCLA team developed a hybrid digital-optical system intended to address both challenges.
A lightweight digital encoder first collects compact information about each video, including spatial, spectral, and temporal features. That information is transformed into a phase pattern and displayed on a programmable spatial light modulator.
The resulting optical wavefront then travels through a free-space-based, passive optical decoder. At the other end, paired optical detectors directly produce an authenticity score for each video.
In effect, the system replaces a computationally demanding digital decoding network with a physical process that can handle many streams in parallel.
Nearly 98% Accuracy Across 15 Videos at Once
In experiments using visible light, the processor examined 15 Celeb-DF videos simultaneously during each optical pass.
It achieved an average detection accuracy of 97.79%, along with a sensitivity of 99.86% and a specificity of 95.72%. Sensitivity measures how successfully the system identifies manipulated videos, making the particularly high sensitivity important for a screening tool designed to keep fake content from slipping through.
The 99.86% sensitivity translated to an average false-negative rate of ~0.14%. In other words, only a very small fraction of manipulated videos were incorrectly classified as authentic.
The researchers also pushed the system further by increasing its capacity to 18 videos in a single optical pass. Even at that level, average detection accuracy remained at 96.13%.
More Optical Layers Boost Performance
The team found that the processor could also become more capable by increasing the physical depth of its passive optical decoder without substantially increasing energy use or inference latency.
When researchers added two optimized passive diffractive layers while testing more difficult deepfake manipulations, detection accuracy improved by ~6.8%.
These phase-only diffractive layers can be manufactured as passive, static optical structures/surfaces. They perform additional calculations through the diffraction of light, meaning they do not require additional electrical power while the system is performing an inference.
That approach could allow more sophisticated processing without the same energy costs that typically accompany larger digital neural networks.
Testing the System Against Google VEO-3 Videos
The researchers did not limit their experiments to conventional face swapping deepfakes. They also challenged the processor with videos produced using Google's VEO-3 model.
Newer generative AI systems can create footage that lacks many of the obvious artifacts associated with earlier deepfake technology, making them a more difficult target for detectors trained primarily on older forms of manipulation.
With only minimal fine-tuning, the optical processor achieved 94.80% accuracy and 97.61% sensitivity on previously unseen VEO-3 videos during experiments.
The results suggest that the approach could potentially adapt as generative AI technology continues to evolve.
A Deepfake Detector Designed to Be Harder to Fool
The optical system also showed resistance to black-box adversarial attacks and provides inherent protection against white-box attacks.
Part of that security comes from the way the detector physically performs its calculations. Because some of the inference process takes place through diffraction, important parameters of the optical model are effectively embedded within the hardware.
Those parameters can be difficult for an attacker to measure, reproduce, or reverse engineer. That makes reconstructing the detector and designing carefully tailored adversarial changes that can evade it considerably more difficult.
The processor also continued working reliably when videos were affected by image noise, blur, JPEG compression, and experimental misalignments. According to the researchers, those results illustrate how optical computation could provide a more secure and dependable foundation for some artificial intelligence systems.
A First Line of Defense Against Deepfakes
Rather than replacing sophisticated digital detectors entirely, the UCLA processor is designed to work as a highly sensitive first stage of a larger detection system.
Massive volumes of video could initially pass through the parallel optical processor. Content identified as suspicious could then be sent to more computationally demanding digital models for a more detailed final assessment.
Such a system could combine the strengths of both approaches. Optical processing could provide parallel operation, low decoder energy requirements, high sensitivity, resistance to adversarial attacks, and the ability to adapt to newer AI video generators, while conventional digital systems could provide deeper analysis when necessary.
The researchers say this combination could eventually be useful for large-scale content moderation, media authentication, surveillance, and other security-critical AI applications.
The authors of this work are Parnian Ghapandar Kashani and Dr. Shiqi Chen, who contributed equally, and Professor Aydogan Ozcan. The researchers are affiliated with the UCLA Electrical and Computer Engineering Department, the UCLA Bioengineering Department, and the California NanoSystems Institute.
Materials provided by Light Publishing Center, Changchun Institute of Optics, Fine Mechanics And Physics, CAS. Note: Content may be edited for style and length.
Parnian Ghapandar Kashani, Shiqi Chen, Aydogan Ozcan. Scalable, energy-efficient optical-neural architecture for multiplexed deepfake video detection. eLight, 2026; 6 (1) DOI: 10.1186/s43593-026-00143-y
Light Publishing Center, Changchun Institute of Optics, Fine Mechanics And Physics, CAS. "This light-powered AI can spot deepfakes with nearly 98% accuracy." ScienceDaily. ScienceDaily, 1 October 2026. .
Light Publishing Center, Changchun Institute of Optics, Fine Mechanics And Physics, CAS. (2026, October 1). This light-powered AI can spot deepfakes with nearly 98% accuracy. ScienceDaily. Retrieved November 5, 2026 from www.sciencedaily.com/releases/2026/09/260929053534.htm
Light Publishing Center, Changchun Institute of Optics, Fine Mechanics And Physics, CAS. "This light-powered AI can spot deepfakes with nearly 98% accuracy." ScienceDaily. www.sciencedaily.com/releases/2026/09/260929053534.htm (accessed November 5, 2026).
原文为英文,正文由自动抓取并保留原文。
原文发布于 ScienceDaily AI(This light-powered AI can spot deepfakes with nearly 98% accuracy),标题、摘要与正文由机器翻译,术语按行业惯例统一,未经人工逐句校订。