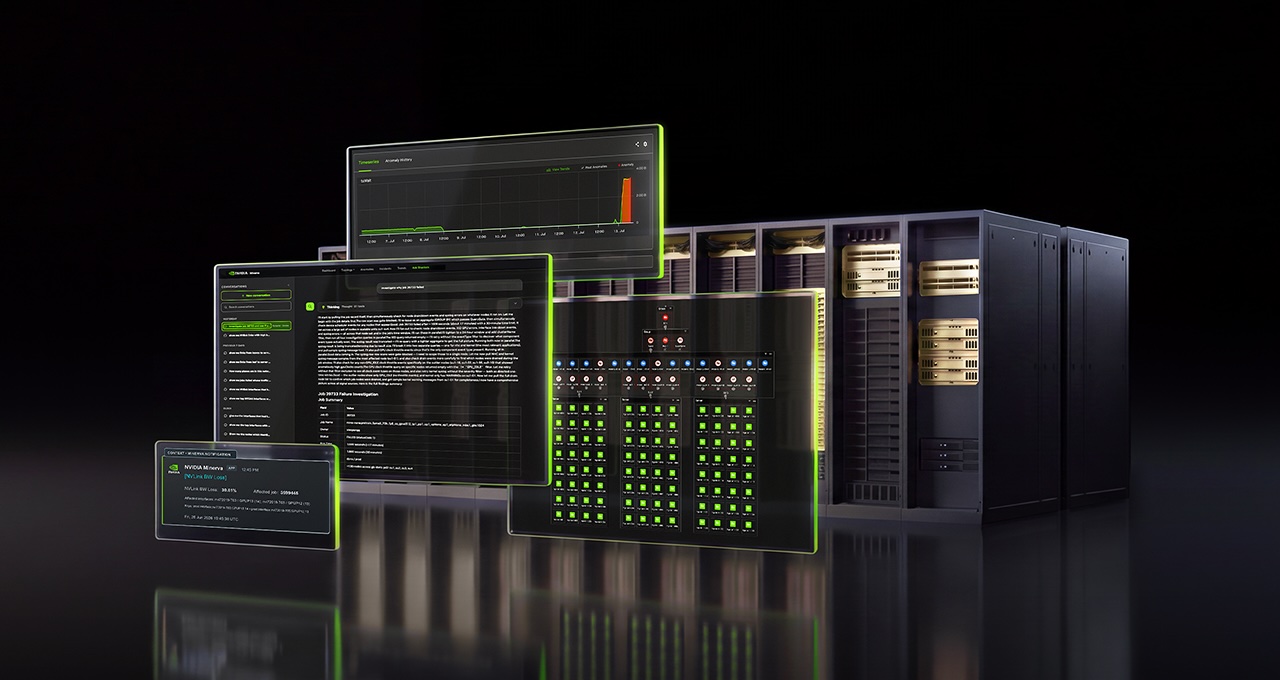
用 NVIDIA DSX OS 配置、认证并运维 Kubernetes GPU 集群

一块性能不佳的 GPU 就可能拖慢整个分布式训练任务。该节点或许能通过基础健康检查,并显示正常的利用率,导致运维人员只有在工作负载运行之后才会发现问题。这类问题可能出现在集群生命周期的任何阶段。一个在交接时通过了就绪检查的 GPU 集群,会随着节点更换、驱动打补丁……而发生变化。
译文由英文原文机器翻译,术语按行业惯例统一,可在文末展开原文核对。
查看英文原文(Configure, Certify, and Operate Kubernetes GPU Clusters with NVIDIA DSX OS)
 One underperforming GPU can slow an entire distributed training job. The node may pass basic health checks and show normal utilization, leaving operators to...
One underperforming GPU can slow an entire distributed training job. The node may pass basic health checks and show normal utilization, leaving operators to discover the problem only after the workload is running. These issues can appear at any point in a cluster’s lifecycle. A GPU cluster that passes readiness checks at handover changes as nodes are replaced, drivers are patched…
正文保留英文原文,标题与摘要由机器翻译。
本文由采集器自动同步
阅读原文 ↗
原文发布于 NVIDIA Developer(Configure, Certify, and Operate Kubernetes GPU Clusters with NVIDIA DSX OS),标题、摘要与正文由机器翻译,术语按行业惯例统一,未经人工逐句校订。