BMW 集团如何在数千名开发者中治理数百个智能体
在 BMW 集团的研发部门,超过 12,500 名开发者负责约 5 亿行车辆软件代码。这些软件由 BMW Connected Vehicle 后端提供支撑——这是一个基于云的系统,包含 1,300 多个微服务,为在役的 2,400 万辆车辆提供数字服务。在受监管的行业中,(软件)质量、稳定性和治理合规的标准异常之高。
尽管如今各类研究、框架和指南已为构建智能体提供了便利,但要以高效、可扩展的方式将高质量智能体工业化并投入运营,仍是一项重大挑战。
在大型组织中规模化推广智能体式 AI,无法靠各自为战的团队实现。它需要集体协作、由本地驱动的试验,以及在整个企业内积极共享知识。这就形成了一种根本性的治理两难:开发团队需要快速创新的自由,而企业必须强制推行安全、安保、可组合性和成本效益方面的标准。若缺乏这种平衡,组织就可能面临 AI 孤岛林立、重复工作代价高昂的碎片化局面。考虑到 BMW 集团有数百个遍布全球的团队在构建智能体,这构成了实实在在的挑战。
在本文中,我们详细介绍了为 BMW 研发团队提供支持的实践与模式,帮助他们在不牺牲速度、质量或合规性的前提下,大规模地构建、治理和运营智能体。
我们的前提很简单:从一开始就构建能够相互协作的智能体。这需要一种架构,使多样性可组合、可治理、可自动化,而不必依赖单一框架或工具链。
这一架构的核心是 agent harness(智能体运行框架),即包裹在大语言模型(LLM)之外的一层运行时。它为自主运行提供执行循环、工具调度、内存管理以及可观测性钩子。
正如 AWS Well-Architected Framework 统一了云基础设施的设计规范,智能体式系统也需要对等的模式——可复用的蓝图,从一开始就把治理、可组合性和运维最佳实践编码其中。
我们围绕五项相互衔接的实践来组织这套解决方案,它们源自 2023 年以来在企业级规模上构建和运维智能体式系统的一线经验。每项实践都被固化为基础设施即代码(IaC),使落地方式可复现、可审计,并能在各团队间强制执行,同时不妨碍 DevOps 的迭代速度。
治理必须从一开始就是结构性的,并在整个生命周期中持续维护。我们主张,有效的智能体治理应具备三项特性:
框架无关且外部化:身份认证、授权、限流和内容过滤等治理规则在集成层强制执行。这包括 Model Context Protocol(MCP)网关、中央智能体注册表与编排边界,而不是放在各个智能体自身的代码库内。这意味着治理能够经受框架迁移、模型替换和团队重组。
领域敏感且分级:并非每个智能体动作都承担相同的风险:起草文档、更新客户记录与写入生产数据库,所需的监督级别差别很大。我们通过按步骤设定自主级别来实现分级信任:
按步骤而非按智能体分配信任级别。单个工作流可以包含全部三个级别的步骤,因此团队可以保守起步,随着信心建立而逐步提高自主性,并且要基于可衡量的评估数据,而非假设。
确定性强制执行:治理以确定性代码的形式运行在智能体的推理循环之外。在实践中,这主要发生在 CI/CD 流水线中。权限检查、策略即代码规则和合规验证在那里对每次部署进行把关,在智能体进入生产环境之前。由于这些检查与智能体分开运行,无论是智能体还是其提示词都无法覆盖它们。出站控制(收件人允许列表、出站机密扫描)有助于防止持有机密数据的智能体通过原本合法的调用将其泄露出去。
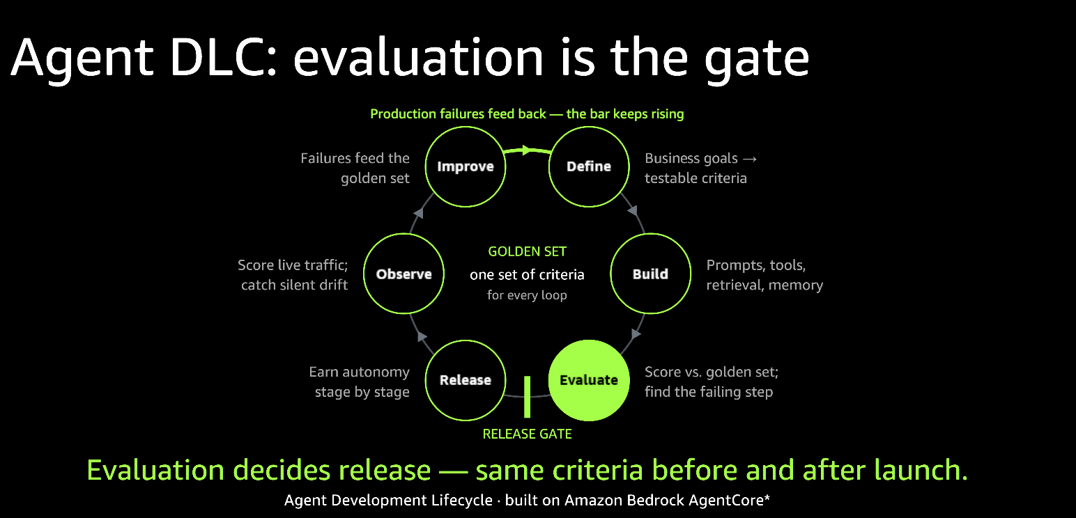
智能体系统中的可观测性超越了传统的应用监控。真正的问题不再是某个服务是否返回了 HTTP 200 状态码,而是智能体是否产生了忠实、符合策略的输出,以及如何通过可观测的执行轨迹来证明这一点。要回答这个问题,需要一个覆盖常见查询和边缘情况的真值数据集。该数据集从第一天起就用于评估,因此质量是依据具有代表性且得到适当治理的评估数据集来衡量,而不是合成提示词。
这套基础设施无法事后加装,必须成为初始设计的一部分。持续集成与持续交付(CI/CD)流水线会强制执行这一点,因此缺少埋点的智能体在评估运行之前就无法通过验证。
我们建议对三个维度进行埋点:
对于分布式云系统,业界通过采用微服务或服务网格等架构模式,解决了端到端工作流的复杂性问题。智能体系统的演进需要遵循类似的轨迹,从单体式、通用型智能体转向多个协作的专用智能体。
团队应先定义问题,再考虑智能体的功能。在编写任何编排逻辑之前,他们应产出五项具体的工件:
这种纪律可以避免我们观察到的最常见故障模式:承担过多职责的智能体会累积臃肿的提示词,导致准确率下降、延迟增加。
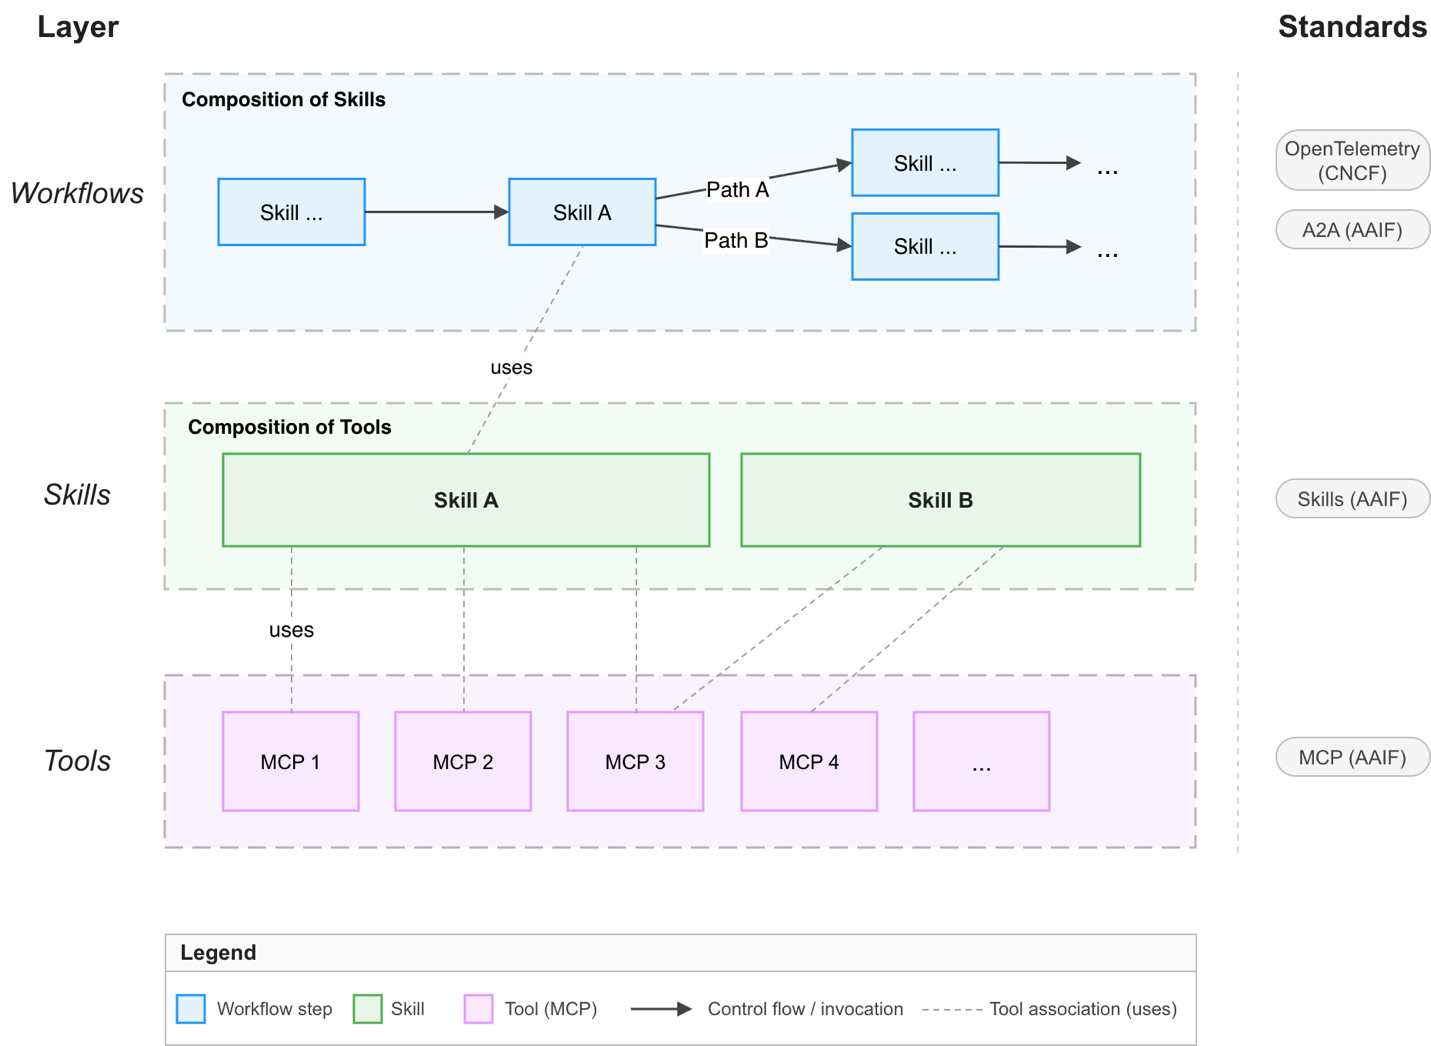
一旦单个智能体的范围界定清晰,就必须将其设计为可组合的构建块。因此,我们定义了一个三层组合层级:
每个层级都在 CI/CD 流水线中独立验证。组件测试覆盖工具和技能,交互测试覆盖它们组合成流程的方式。
这些层级通过开放标准连接:用于工具集成的 MCP 和 Agent Skills、用于智能体间通信的协议,以及用于对由此产生的交互进行可观测性监控的 OpenTelemetry。
图 1 展示了三个层级如何相互构建,从底层的单个 MCP 工具到顶层的完整流程。
图 1:用于构建可组合智能体的三层系统
在生产环境中,即便是范围界定清晰的智能体也可能失效,因为真实世界的使用方式会偏离设计时的预期:查询模式发生变化,工具选择逻辑难以应对,性能出现不可预测的下降。
正确的应对方式是把复杂的智能体拆解为多个专用智能体,每个智能体都有更清晰的指令、更简单的工具集和更聚焦的推理。其收益是实实在在的:
可以从两个维度降低复杂度:
关键在于,由于每个专用智能体只能访问其角色所需的数据和工具,这种架构有助于在设计层面落实最小权限原则,而这正是受监管行业的合规要求。
然而,要实现这些收益,前提是智能体之间能够相互发现并互操作。为防止出现 AI 孤岛,我们维护了一个集中式的智能体、工具与技能注册表。该注册表的作用是:
从管理单个智能体转向治理智能体集群,要求将智能体架构代码化。借助 Terraform 或 AWS CloudFormation 等基础设施即代码(Infrastructure-as-code)框架,团队可以像对待任何生产系统一样严格地配置和管理智能体基础设施:
这三项均作为流水线关卡强制执行,在注册前完成校验,而不是事后审计。
采用模式刻意设计为自下而上、并辅以集中式治理。各个团队构建技能和 MCP 工具来解决眼前的实际问题。所有团队都可以通过注册表共享自己的资产来做出贡献。中央团队构建自动化的治理检查,作为 CI 流水线的一部分,以维护标准。为支持开发团队并推动“左移”(shift-left),中央团队还以治理即代码(governance-as-code)模块的形式提供构建块。
这种平衡既避免了由中央强制规定的架构,也避免了无人管理的试验。因此,当新的运营问题出现时,团队可以扩展现有模式,而不必重新设计其架构。
只有当架构模式与治理标准被嵌入团队在运行前及运行时构建和运营智能体所用的工作流中,它们才会真正有效。
治理在写下第一行编排逻辑之前就已开始。团队会获得参考架构模式以及取自注册表的示例。这些经过预先验证的蓝图涵盖常见的智能体配置、工具集成模式和组合结构,既能加速开发,又能将经过验证的默认设置固化下来。在任何内容进入生产环境之前,标准化的 CI/CD 控制会强制执行这些实践。图 2 展示了参考流水线的四个阶段,按从左到右的顺序执行。
图 2:四阶段智能体部署流水线的参考模式。
原文较长,译文为节选;译文由英文原文机器翻译,术语按行业惯例统一,可在文末展开原文核对。
查看英文原文(How the BMW Group governs hundreds of agents across thousands of developers)
At the BMW Group’s R&D, more than 12,500 developers work on approximately 500 million lines of vehicle software code. This software is augmented by the BMW Connected Vehicle backend, a cloud-based system of more than 1,300 microservices providing digital services for 24 million vehicles in the field. In regulated industry, the bar for (software) quality, stability, and governance compliance is exceptionally high.
While research, frameworks, and guidelines now facilitate building agents, industrializing and operating high-quality agents in an efficient, scalable manner remains a significant challenge.
Scaling agentic AI across a large organization cannot be achieved by isolated teams. It requires collective effort, locally driven experimentation, and active knowledge sharing across the enterprise. This creates a fundamental governance dichotomy: Development teams need the freedom to innovate rapidly, while the enterprise must enforce standards for safety, security, composability, and cost-efficiency. Without that balance, organizations risk a fragmented landscape of AI islands and costly duplicate work. This presents a real challenge given hundreds of globally distributed teams building agents across the BMW Group.
In this post, we detail the practices and patterns that support BMW’s R&D teams in building, governing and operating agents at scale without sacrificing speed, quality or compliance.
Solution
Our premise is straightforward: build agents that can cooperate from the start. This requires an architecture that makes diversity composable, governable, and automatable, without requiring a single framework or toolchain.
Central to this architecture is the agent harness, a runtime layer wrapped around a large language model (LLM). It provides the execution loop, tool dispatch, memory management, and observability hooks for autonomous operation.
Just as the AWS Well-Architected Framework standardized cloud infrastructure design, agentic systems need equivalent patterns, reusable blueprints encoding governance, composability, and operational best practices from the start.
We organize our solution around five interlocking practices, drawn from hands-on experience building and operating agentic systems at enterprise scale since 2023. Each practice is codified as infrastructure as code (IaC), making adoption repeatable, auditable, and enforceable across teams without blocking DevOps velocity.
Govern proactively, not retroactively
Governance must be structural from the start and maintained across the full lifecycle. We advocate for three properties of effective agentic governance:
Framework-agnostic and externalized: Governance rules such as authentication, authorization, rate limiting and content filtering are enforced at the integration layer. This includes a Model Context Protocol (MCP) gateway, a central agent registry and orchestration boundary, rather than within individual agent codebases. This means governance survives framework migrations, model swaps, and team reorganizations.
Domain-sensitive and graduated: Not every agent action carries the same risk: drafting documentation, updating customer records, and production database writes demand very different levels of oversight. We implement graduated trust through per-step autonomy levels:
- Level 0 (Human-in-the-loop): Every action requires explicit human approval. This is the starting point for new agents and high-risk operations.
- Level 1 (Human-on-the-loop): The agent executes autonomously but surfaces decisions for asynchronous human review. Suitable for medium-risk tasks with defined inputs, outputs, and rollback options.
- Level 2 (Autonomous within guardrails): The agent operates independently within strictly defined policy boundaries, enforced deterministically rather than through prompt instructions (see below). Reserved for low-risk, well-understood operations with verified track records.
Assign trust levels per step, not per agent. A single workflow can include steps at all three levels, so teams can start conservatively and incrementally increase autonomy as confidence builds, grounded in measurable evaluation data, not assumptions.
Deterministically enforced: Governance runs as deterministic code outside the agent’s reasoning loop. In practice, this happens mainly in the CI/CD pipeline. Permission checks, policy-as-code rules, and compliance validations gate every deployment there, before an agent reaches production. Because these checks run separately from the agent, neither the agent nor its prompts are in a position to override them. Egress controls (recipient allowlisting, outbound secret scanning) help prevent an agent holding confidential data from disclosing it through an otherwise legitimate call.
Instrument, verify, and evaluate continuously
Observability in agentic systems goes beyond traditional application monitoring. The real question is no longer whether a service returned an HTTP 200 status, but whether an agent produced a faithful, policy-compliant output, and how this can be demonstrated through observable execution traces. Answering that requires a ground-truth dataset covering common queries and edge cases. This dataset is used for evaluation from day one, so quality is measured against representative and appropriately governed evaluation datasets for evaluation, not synthetic prompts.
This infrastructure cannot be retrofitted and must be part of the initial design. The continuous integration and continuous delivery (CI/CD) pipeline enforces this, so agents lacking instrumentation fail validation before evaluation runs.
We recommend instrumenting three dimensions:
- Intent tracing: Capture the observable agent trajectory (reasoning steps, tool invocations, and context retrievals) for each execution. OpenTelemetry spans create a queryable lineage from user request to final output.
- Verification and evaluation as CI: Any change to the agent (prompt edits, tool additions, model swaps) triggers the pipeline. Verification runs first with automated regression tests covering agent components and then their interactions. As most harness components are deterministic, these tests are fast and fully automatable. Evaluation runs second, scoring non-deterministic output against the ground-truth dataset, gated on quality thresholds. This sequencing is deliberate: Verification acts as a gate, so evaluations only run on a passing build.
- Model tiering and routing telemetry: When agents route between models, capture the routing decision and its justification, not just the outcome. Tier assignments are derived from evaluation results per task type and poor outcomes flow back as new evaluation cases.
Start focused, design for composition
For distributed cloud systems, the industry solved the complexity of end-to-end workflows by adopting architectural patterns such as microservices or service meshes. The evolution of agentic systems needs to follow a similar trajectory, moving from monolithic, generalist agents toward multiple collaborating specialized agents.
Teams should define the problem before considering agents’ functionality. Before writing any orchestration logic, they should produce five concrete artifacts:
- Clear scope definition: what the agent should and shouldn’t do.
- Interaction model: how users and other agents will invoke it.
- Unambiguous tool definitions: each tool and parameter precisely defined.
- Ground-truth dataset: the evaluation reference described above, established before any implementation begins.
- Evaluation criteria: quality thresholds and benchmarks the agent will be measured against.
This discipline prevents the most common failure modes we observe: agents that take on too many responsibilities accumulate bloated prompts, reducing accuracy and increasing latency.
Once a single agent is well-scoped, it must be designed as a composable building block. Therefore, we define a three-tier composition hierarchy:
- MCP tools are atomic integration contracts. Each tool wraps a single capability (for example, an API call or a database query) without encoding workflow assumptions. This is the stable, reusable layer.
- Skills are bundled, domain-specific compositions of MCP tools. A code review skill, for example, might chain a static analysis tool, a style-check tool, and an LLM-based reasoning step. Skills encode domain logic but remain portable across workflows.
- Flows are end-to-end orchestrations of skills, representing complete business processes (for example, an entire PR review pipeline or a requirements-to-deployment cycle).
Each tier is validated independently in the CI/CD pipeline. Component tests cover tools and skills, interaction tests cover their composition into flows.
These tiers are connected through open standards: MCP and Agent Skills for tool integration, the protocol for agent-to-agent communication, and OpenTelemetry for observability across the resulting interactions.
Figure 1 shows how the three tiers build on each other, from individual MCP tools at the base to complete flows at the top.
Figure 1: Three-tier system to build composable agents
Specialize as you learn
In production, even well-scoped agents can break down as real-world usage diverges from what was anticipated at design time: query patterns shift, tool-selection logic struggles, and performance degrades unpredictably.
The right response is to decompose complex agents into multiple specialized ones, each with clearer instructions, simpler tool sets, and more focused reasoning. The benefits are concrete:
- Evolve independently: updating a requirements engineering agent does not require touching the coding agent.
- Scale individually: when scope and interfaces are well-defined, individual agents can be scaled independently without redeploying or resizing the broader system.
- Minimized scope: a failure or hallucination of one agent does not cascade across the entire workflow.
- Cost savings: A narrowly scoped agent can often run on a smaller model, which cuts inference and hosting costs.
Complexity can be reduced along two axes:
- Within an agent: decompose capabilities into skills since tools and few-shot examples consume context on every invocation while degrading accuracy and increasing cost. Determine granularity empirically: merge skills the agent rarely selects and split skills that produce different behavior depending on the input.
- Across agents: delegate work outside an agent’s domain to a specialized peer over the A2A protocol rather than extending the current agent. An agent should grow in capability, not in context.
Critically, since each specialized agent only accesses the data and tools required for its role, this architecture helps to enforce least-privilege by design, a compliance requirement in regulated industries.
Realizing these benefits, however, requires that agents can find and interoperate with each other. To prevent the emergence of AI islands, we maintain a centralized registry of agents, tools, and skills. This registry serves as:
- Discovery mechanism: cataloging available agents, tools, and skills based on metadata stored during build.
- Governance checkpoint: confirming approval of the asset types for production use and maintaining an audit trail.
- Security checkpoint: automated security checks are applied before approval, such as prompt injection and similar issues.
- Deduplication safeguard: identifying equivalent capabilities already maintained by other teams to avoid duplicate work. This check runs automatically at registration, flagging duplicates before approval.
Scale through codification
The shift from managing individual agents to governing an agent fleet requires agent architectures to be codified. Using Infrastructure-as-code frameworks such as Terraform or AWS CloudFormation, teams provision and manage agent infrastructure with the same rigor applied to any production system:
- Fine-grained least-privilege roles: scoped per agent or tool.
- CI/CD pipelines: consistent, validated deployments across accounts and regions, with automated deployment stops on failed tests or metric deterioration.
- Policy-as-code: rules (for example, AWS Config, Open Policy Agent) scanning deployed agents for compliance with organizational standards.
All three are enforced as pipeline gates, validated before registration, not audited after the fact.
The adoption model is deliberately bottom-up with central curation. Individual teams build skills and MCP tools to solve their immediate problems. All teams can contribute by sharing their assets through the registry. A central team builds automatic governance checks as part of the CI pipeline to uphold standards. To support development teams and foster shift-left, the central team additionally provides building blocks as governance-as-code modules.
This balance avoids both centrally mandated architectures and unmanaged experimentation. As a result, when new operational concerns arise, teams can extend existing patterns rather than redesign their architectures.
Operationalizing best practices across the agent lifecycle
Architectural patterns and governance standards are only effective if they are embedded into the workflows teams use to build and operate agents before and at runtime.
Before deployment
Governance begins before a single line of orchestration logic is written. Teams are provided with reference architecture patterns and examples drawn from the registry. These pre-validated blueprints cover common agent configurations, tool integration patterns, and composition structures, which accelerate development while encoding proven defaults. Before anything reaches production, standardized CI/CD controls enforce these practices. Figure 2 shows the four phases of a reference pipeline, which run in order from left to right.
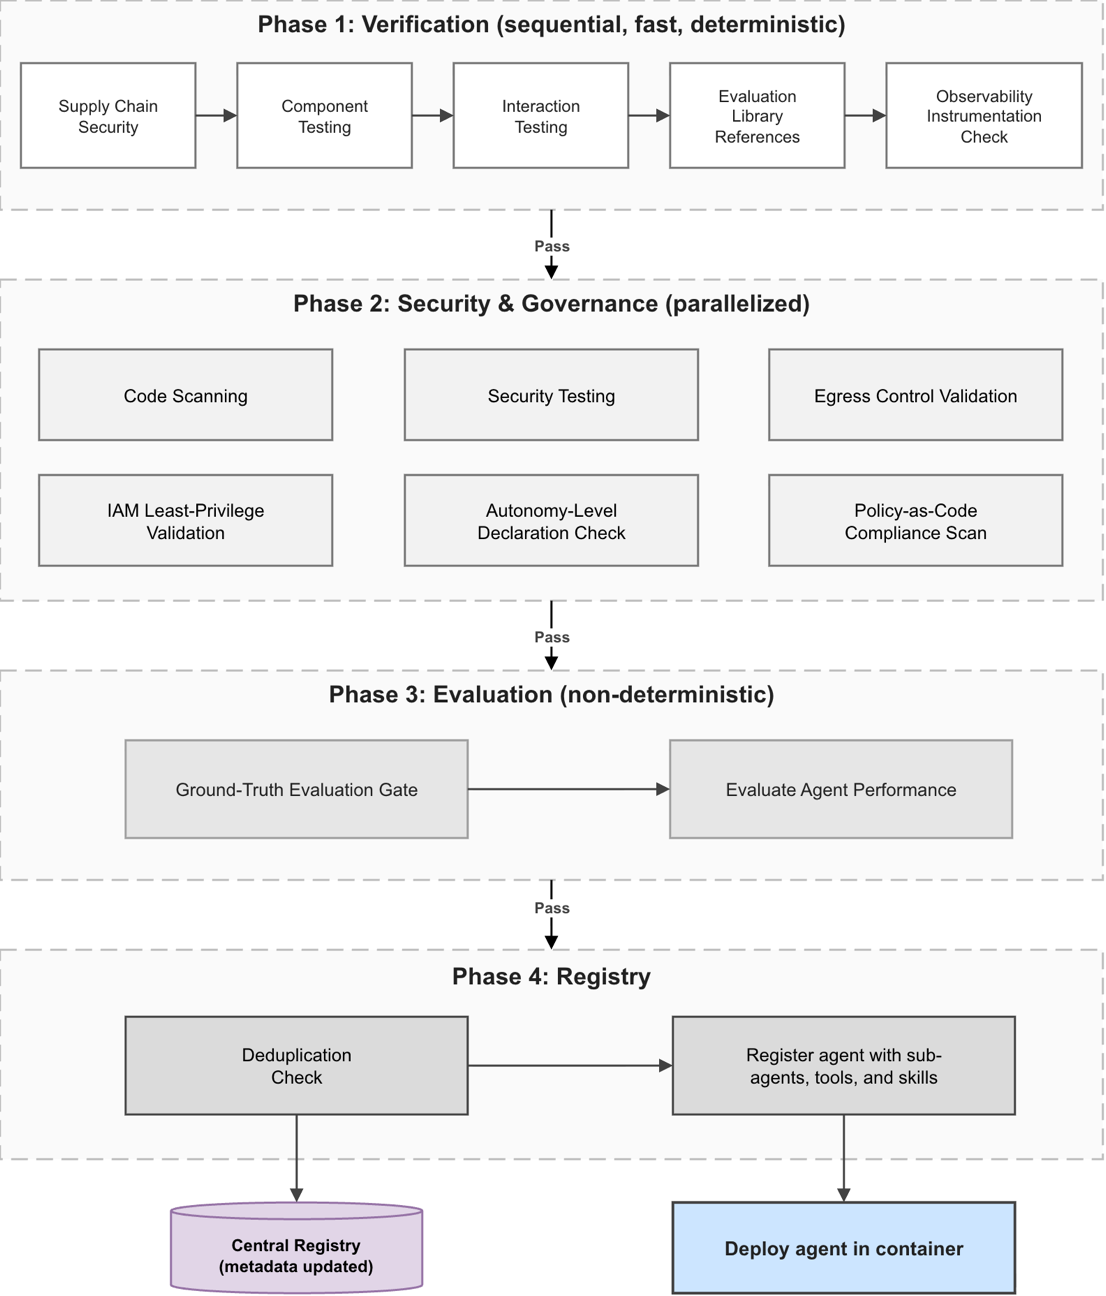
Figure 2: Reference pattern for a four-phase agent deployment pipeline.
Phase 1 from Figure 2 runs fast, deterministic checks: supply chain security (approved registries only), component and interaction testing, evaluation library references, and observability instrumentation.
Phase 2 runs security and governance checks in parallel. Static analysis scans the code for issues, and security tests probe the agent in an isolated staging environment. The pipeline also validates egress controls and least-privilege permissions. Two more checks confirm that the agent’s declared autonomy level matches its actual permissions and that its configuration passes the policy-as-code rules. A governance agent accelerates audits by checking the agent against established standards and flagging findings for human review, such as:
- Scope creep: operating beyond originally defined purpose or permissions.
- Prompt bloat: unnecessary complexity in instructions.
- Tool misuse: calling tools outside their intended use case.
- Performance degradation: declining accuracy, latency, or cost-efficiency.
Figure 3: Example governance agent workflow
This assessment surfaces concrete, actionable measures that teams can apply immediately, rather than abstract recommendations. Figure 3 shows the governance agent’s dashboard for an agent maturity assessment. The governance agent provides evidence and actionable recommendations, while accountable humans own governance decisions. Recommendations require human confirmation before being applied, maintaining a four-eyes principle for accountability. Findings update the agent’s governance status in the registry, while full details are logged separately in a central knowledge base for audit and traceability.
Phase 3 evaluates the agent as a running system: the ground-truth evaluation gate (scores outputs against benchmarks established at design time) and agent performance (latency, token consumption). Figure 4 details the metrics, scoring criteria and the relationships between them.
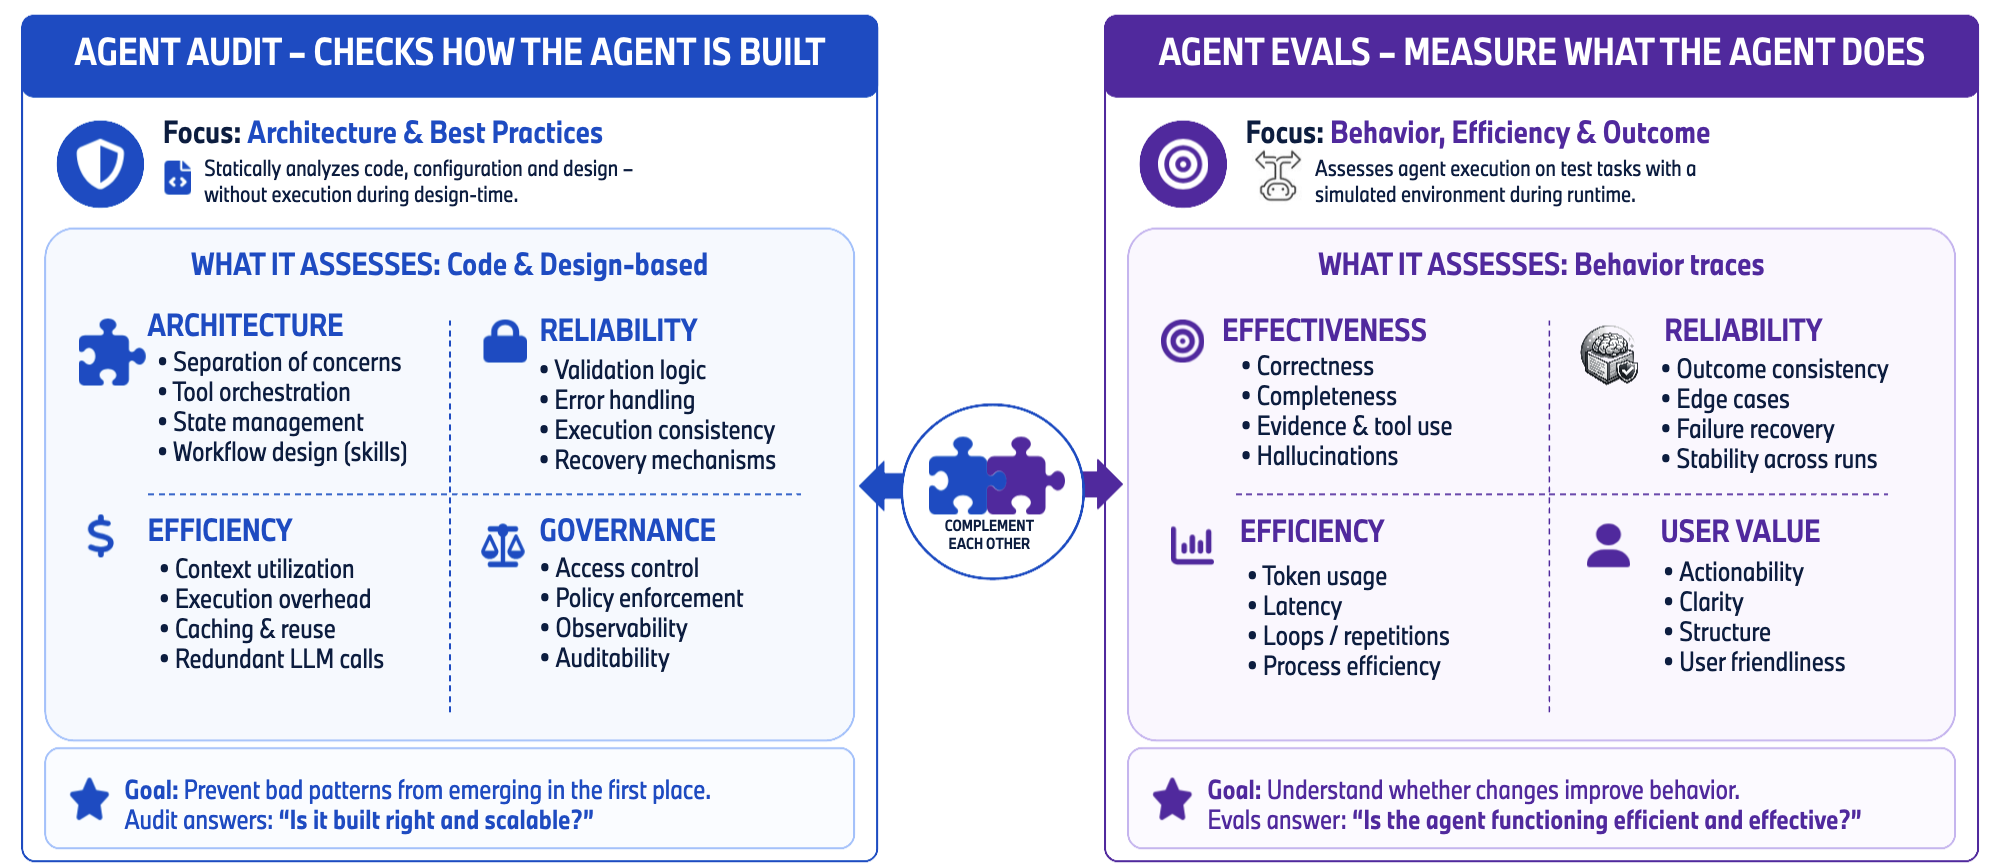
Figure 4: Overview of evaluation metrics
Phase 4 checks for duplicates before registering the agent, its sub-agents, tools, and skills. The following table shows the metadata fields stored per agent in the registry.
| Agent metadata |
Core data:
|
Service level agreement data:
|
Data governance flags:
|
Table 1: Example agent metadata stored in the registry
If any step fails or metrics deteriorate, the deployment stops with logs for root cause analysis. If all checks pass, the agent is packaged and deployed as a containerized workload, producing consistent, reproducible deployments. This prevents ungoverned agents from reaching production, automates compliance checks, and keeps the registry accurate.
At runtime
At runtime, observability has to catch two kinds of drift. Data drift shows up as new or shifting user query patterns, or changes in upstream APIs. Model drift shows as rising error rates or falling tool-selection accuracy. When a customer flags a response, that also triggers an investigation. Alerts for drift, distribution shifts, declining evaluation scores, or direct customer flags prompt a staged response. These events are logged and forwarded to human review. Additionally, teams can run the governance agent continuously to flag drift and operational issues for the responsible team to investigate.
Summary
Building and operating agents at scale is an engineering discipline, not an experimentation exercise.
Effective governance must be structural from the start, externalized, domain-sensitive, and deterministically enforced. We introduced a three-tier composition hierarchy (MCP tools, skills, and flows) as the architectural foundation for reusable, composable, and interoperable agents, decomposed into specialized agents to contain complexity and scope. We showed how verification and evaluation in every CI/CD run make quality assurance part of everyday development, and how defining agent infrastructure as code lets teams apply the same governance rules to every agent in the fleet. Finally, we operationalized these patterns across the agent lifecycle, from pre-validated reference architectures and structured pipelines to a runtime governance agent that continuously evaluates deployed agents.
Our experience has shown these practices pay off in a few ways. Reusable templates and shared infrastructure reduced development costs. Teams also got agents to production faster, thanks to standard interaction models and automated deployment. Quality improved too, because the pipeline enforces proven patterns at every stage of the lifecycle.
Scaling agentic governance is an industry-wide imperative. The shift toward AI and generative-AI-supported workflow automation is already reshaping how engineering organizations operate. The winners will be those who move beyond experimentation and establish the discipline to govern autonomous agent networks at scale. With these practices in place, BMW engineers can focus on solving the problems that matter: Building the ultimate driving machine.
To apply these ideas to your own agents, start with the AWS Well-Architected Framework. This post used it as the model for reusable agent blueprints. To see how BMW codifies governance across its AWS environment, read How BMW Group uses automation to achieve end-to-end compliance at scale on AWS.
Outlook and next steps
The patterns and practices described in this post are a foundation, not a finish line. We are actively extending them across several fronts:
- Improve architectural guidance: publishing best practice guides on architectural trade-offs, composition patterns, and anti-patterns for teams building agents.
- Expand infrastructure-as-code templates: providing agent blueprints as usable IaC modules with built-in security and governance standards by default.
- Deepen governance compliance testing: adding CI/CD test cases verifying governance compliance.
- Automate standards enforcement: expanding automated checks and managed compliance-scanning rules across pre-deployment and runtime stages.
- Extend agentic FinOps: Govern the right-sizing of models and tool calls.
- Agentic user guidance: integrating described patterns into Archimedes, BMW’s architectural guidance agent, to provide contextual architectural recommendations.
Acknowledgements
The authors would like to thank (in alphabetical order) Alexander Stark, Alexander Zimmer, Dr. Céline Laurent-Winter, Dominik Segl, Florian Seidel, Hugo Lerias, Dr. Lars Lewerenz, Mark Neumann, Ralf Bottesch, Ramona Weber, Satish Vasireddy, Samuel Voss, Xagarey-Louis Meyer.
About the authors
Dr. Jens Kohl
Jens is a technology leader and builder at the BMW Group. He is currently co-leading a BMW R&D-wide AI initiative optimizing software DevOps workflows for more than 12,000 engineers. He has led software development, machine learning, and cross-functional teams for more than 10 years, building production AI solutions for millions of vehicles and optimizing cloud backends serving 24M BMW vehicles worldwide. Jens holds a Ph.D. and M.Sc. in Computer Science from the Technical University of Munich and regularly shares his work through technical blogs, talks, and conferences.
Dr. Lukas Stappen
Lukas is a technology leader and builder in generative AI at the BMW Group. Currently, he drives Agentic Software Development, shaping the agent tooling and platform that automates work across the software development lifecycle for BMW’s software engineers. He founded the LLM Lab at BMW Group Research and delivered the first LLM-based in-vehicle voice assistant deployed in more than 100,000 vehicles. Lukas holds a Ph.D. from the University of Augsburg.
Dr. Martin Haubold
Martin is an Enterprise Architect at BMW Group, where he focuses on AI governance and agent architecture across AWS and Azure. He specializes in governance-as-code, AI security and building cloud-native on AWS. Previously, he spent seven years owning the cloud infrastructure behind BMW’s autonomous transport robot platform, running production Kubernetes clusters with Terraform, Helm and Kafka. Martin holds a Ph.D. from Technical University of Munich.
Dr. Veit Wenninger
Veit is an Enterprise Architect and manager for Agentic Governance at the BMW Group, where he sets the direction for the company’s future IT landscape. In previous roles, he defined and scaled the BMW Autonomous Driving Platform, the BMW IoT Platform, and the global Shopfloor Connectivity Platform. Veit has led software development teams for more than 10 years. Veit holds a Ph.D. from Technical University of Munich.
Brendan Jones
Brendan is a Senior Solutions Architect at AWS, working with the BMW Group. He helps automotive customers design highly scalable and resilient cloud architectures that deliver real business impact. His work covers connected vehicle platforms, developer productivity, and cost optimization. More recently, it has extended to agentic AI across the software development lifecycle. Brendan works closely with BMW engineering teams from early architecture decisions through to production.
Vadim Omeltchenko
Vadim is a Sr. AI/ML Solutions Architect who is passionate about helping AWS customers innovate in the cloud. His prior IT experience was predominantly on the ground.
Aishwarya Lakshmi Krishnan
Aishwarya is a Principal Customer Solutions Manager at AWS Automotive, where she sits at the intersection of business and technology. She partners closely with customers to turn complex business challenges into elegant technical solutions—and then sees them through to impact. Deeply enthusiastic about emerging technology and AI, she’s equally energized by building with LEGO and exploring all things space, always driven by curiosity and a love for how things work.
正文保留英文原文,标题与摘要由机器翻译。
原文发布于 AWS Machine Learning(How the BMW Group governs hundreds of agents across thousands of developers),标题、摘要与正文由机器翻译,术语按行业惯例统一,未经人工逐句校订。