Google TPU 新增 AI 训练性能基准测试
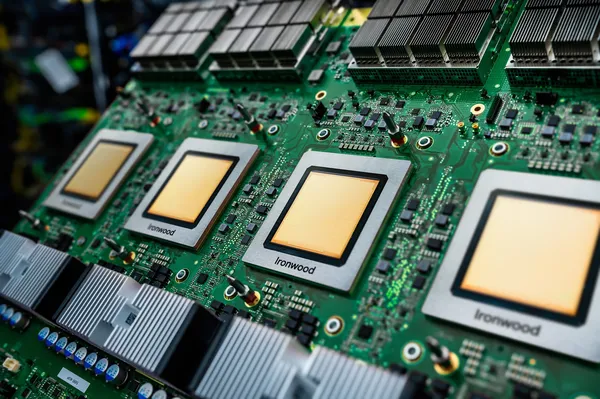
Google TPU 与 GPU 性能:MLPerf v6.1 结果
查看“产品与平台”全部内容
查看“创新与 AI”全部内容
查看“产品与平台”全部内容
Google TPU 的全新 AI 训练性能基准测试
在最新一轮 MLPerf Training v6.1 基准测试第 1 轮中,Google Cloud 公布了基于第七代 Ironwood TPU 和 NVIDIA Grace Blackwell GPU 的 10 项结果,覆盖前沿预训练以及首个面向智能体式强化学习(RL)的 MLPerf 基准测试。这些结果构建于 Google Cloud 的 AI Hypercomputer 架构之上,体现了芯片、网络与开源软件之间的协同设计:
Ironwood 上的预训练:8,192 个 Ironwood TPU 在 1.70 分钟内达到目标模型的基准测试目标质量,扩展至 4,096 颗芯片时效率达 96%。
Ironwood 上的智能体式 RL:640 个 Ironwood TPU 在 18.02 分钟内达到目标模型编码基准测试的目标准确率(0.765,目标为 0.69),同时运行代码生成与学习,使训练芯片的等待时间占比低于 3%。
NVIDIA Grace Blackwell GPU:在 Google Cloud A4X Max 实例上,256 块 NVIDIA GB300 GPU 用时 31.96 分钟达到目标模型的基准测试质量,此外还有五项基于 A4X 和 A4X Max 的智能体式强化学习(RL)基准测试提交。
关于 MLPerf Training v6.1 结果的更多详情,请点击此处。
MLPerf Training v6.1 封闭组(Closed division)成绩编号:6.1-0017(Ironwood 640 芯片 Qwen3.5-397B RL)、6.1-0018(Ironwood 2048 芯片 DeepSeek-V3)、6.1-0019(Ironwood 4096 芯片 DeepSeek-V3)、6.1-0020(Ironwood 8192 芯片 DeepSeek-V3)、6.1-0021(A4X 56 GPU GB200 RL)、6.1-0022(A4X Max 56 GPU GB300 RL)、6.1-0023(A4X 64 GPU GB200 RL)、6.1-0024(A4X Max 64 GPU GB300 RL)、6.1-0025(A4X 256 GPU GB200 RL)以及 6.1-0026(A4X Max 256 GPU GB300 DeepSeek-V3)。所有报告的时间均为 MLPerf 训练时间,即从官方参考检查点训练至达到目标收敛标准所需的时间。MLPerf 名称和标识是 MLCommons Association 在美国及其他国家和地区的注册商标和未注册商标。更多信息请访问 mlcommons.org。
译文由英文原文机器翻译,术语按行业惯例统一,可在文末展开原文核对。
查看英文原文(New AI training performance benchmarks for Google TPUs)
Google TPU and GPU performance: MLPerf v6.1 results
See all in Products & platforms
See all in Innovation & AI
See all in Products & platforms
New AI training performance benchmarks for Google TPUs
In the latest MLPerf Training v6.1 benchmark round 1 , Google Cloud published 10 results across seventh-generation Ironwood TPUs and NVIDIA Grace Blackwell GPUs, spanning frontier pre-training and the first MLPerf benchmark for agentic reinforcement learning (RL). Built on Google Cloud’s AI Hypercomputer architecture, these results reflect co-design across silicon, networking, and open software:
Pre-training on Ironwood: 8,192 Ironwood TPUs reached the target model's benchmark target quality in 1.70 minutes, scaling up to 4,096 chips with 96% efficiency.
Agentic RL on Ironwood: 640 Ironwood TPUs reached the target model’s coding benchmark target accuracy in 18.02 minutes (0.765 vs. the 0.69 goal), running code generation and learning simultaneously so training chips waited under 3% of the time.
NVIDIA Grace Blackwell GPUs: On Google Cloud A4X Max Instances, 256 NVIDIA GB300 GPUs reached the target model's benchmark quality in 31.96 minutes, complemented by five A4X and A4X Max submissions on the agentic RL benchmark.
For more details on the MLPerf Training v6.1 results, click here.
MLPerf Training v6.1 Closed-division result IDs: 6.1-0017 (Ironwood 640-chip Qwen3.5-397B RL), 6.1-0018 (Ironwood 2,048-chip DeepSeek-V3), 6.1-0019 (Ironwood 4,096-chip DeepSeek-V3), 6.1-0020 (Ironwood 8,192-chip DeepSeek-V3), 6.1-0021 (A4X 56-GPU GB200 RL), 6.1-0022 (A4X Max 56-GPU GB300 RL), 6.1-0023 (A4X 64-GPU GB200 RL), 6.1-0024 (A4X Max 64-GPU GB300 RL), 6.1-0025 (A4X 256-GPU GB200 RL), and 6.1-0026 (A4X Max 256-GPU GB300 DeepSeek-V3). All reported times measure MLPerf time to train from the official reference checkpoint to the target convergence criterion. The MLPerf name and logo are registered and unregistered trademarks of MLCommons Association in the United States and other countries. See mlcommons.org for more information
原文为英文,正文由自动抓取并保留原文。
原文发布于 Google Blog(New AI training performance benchmarks for Google TPUs),标题、摘要与正文由机器翻译,术语按行业惯例统一,未经人工逐句校订。

