携手 IBM Cloud 和 NVIDIA 扩展企业推理能力
推出 Polymorphic Inference,从 Together Compiler 开始 →
推出 Together Post-Training:更好的模型、更快的运行、更低的成本 →
推出 Together Link:在您已在使用的框架中运行开放模型 →
开源 AI 技术栈:模型、推理、路由、框架与工具 →
GLM-5.3 与 GLM 5.3 Flash 在 DeepSWE 上的对比 →
⚡ 按需 B200 现已在 Together GPU Clusters 上可用 →
以 API 形式提供的高性能推理
面向批处理工作负载的推理
基于 Token 的容量,附带 SLA
专属模型推理
在定制硬件上推理
专属容器推理
面向定制模型的推理
在自有 harness 中运行开放模型
随时间持续提升的推理
探索顶尖开源模型
大规模可靠 GPU 集群
前沿规模的自定义基础设施
为 AI 构建开发环境
安全存储模型权重与数据
定义你自己的 RL 与 SFT 循环
启动托管式 SFT 与 DPO 任务
微调顶级开源模型
面向生产级 AI 的系统研究
我们所有的研究出版物
Together AI 的技术文档
我们的最新新闻与博客文章
我们的开源演示应用
实用实施指南
用开放模型更好地构建
在你的测试框架中运行开放模型
浏览我们的活动日历
开源 ROI 计算器
以 API 形式提供的高性能推理
面向批处理工作负载的推理
带有 SLA 的基于 Token 的容量
专属模型推理
在定制硬件上进行推理
专属容器推理
面向自定义模型的推理
在你的运行框架中运行开放模型
随时间推移不断变好的推理
探索顶级开源模型
大规模可靠 GPU 集群
前沿规模的自定义基础设施
为 AI 构建开发环境
安全存储模型权重和数据
定义你自己的强化学习(RL)和监督微调(SFT)循环
启动托管式 SFT 与 DPO 任务
微调顶级开源模型
面向生产级 AI 的系统研究
我们的全部研究出版物
Together AI 技术文档
我们的最新动态与博客文章
我们的开源演示应用
实用实施指南
用开放模型构建更出色的产品
在你的 harness 中运行开放模型
浏览我们的活动日程
开源 ROI 计算器
借助 IBM Cloud 和 NVIDIA 扩展我们的企业级推理容量
我们很高兴地宣布,Together AI 正与 IBM 和 NVIDIA 合作,扩展企业级 AI 推理能力,首先是在 IBM Cloud 上部署一个由 NVIDIA B300 GPU 组成的大型集群,并以 NVIDIA Spectrum-X 以太网网络为支撑。这是 IBM Cloud 上首个此类专用的大规模推理集群,而我们是在其上运行的首个客户。
实际发生了什么
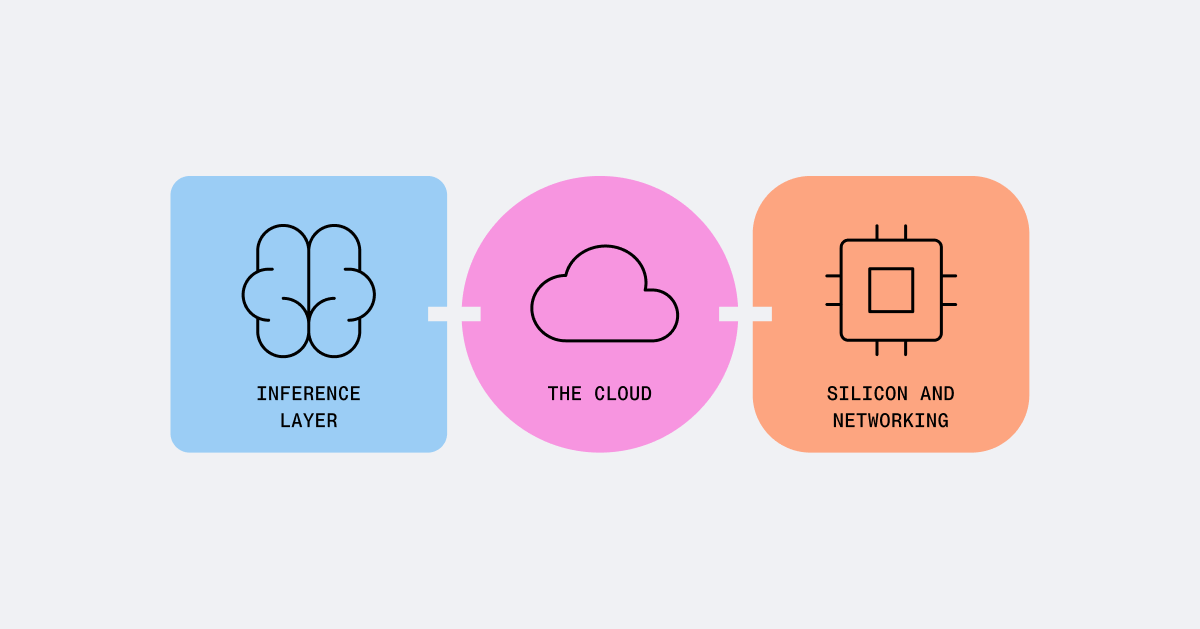
基础设施:一个专为推理打造的专用 NVIDIA B300 GPU 集群,运行在 IBM Cloud 上。
模式:我们运营推理层,IBM 提供云,NVIDIA 提供芯片与网络。
发展轨迹:随着 Token 需求呈抛物线式增长,我们正在为未来做规划。
我们创办 Together AI,是因为我们相信 AI 的未来不应由少数几家闭源实验室所拥有。这一押注的回报比我们预期的还要快:每月为超过一百万开发者提供数百万亿 Token,而且需求还在持续攀升。
企业与 AI 原生公司选择开放模型,原因很简单:他们的主权数据仍归自己所有,同时能以闭源模型成本的一小部分获得前沿级性能。使用规模越大,这笔账就越划算。
通过这一合作:
NVIDIA 提供芯片——为高吞吐推理而设计的 B300 GPU 和 Spectrum-X 以太网网络。
IBM 带来数十年为全球最大型企业运营关键任务基础设施的经验。
Together AI 提供推理平台——在生产环境中运行开放模型最快、最高效的方式,并经受了全球一些最严苛的 AI 工作负载的锤炼。
把这些整合起来,结果很简单:大规模的企业级推理——更多生产级 Token,并具备企业所期望的可靠性、安全性和防护机制。
开源 AI 必须能在任何地方大规模运行,其速度和可靠性不逊于任何闭源方案。过去几年我们一直在确保做到这一点,而这次合作正是朝着这个目标迈出的一大步。
从静态推理到多态推理:生产级开源推理系统的新时代
携手 IBM Cloud 和 NVIDIA 扩展我们的企业推理能力
Together AI 宣布与 Moonshot AI 达成战略合作,原生提供 Kimi 模型服务
宣布完成 8 亿美元 C 轮融资,加速向开源 AI 转型
建立对企业 AI 的信任:Together AI 获得 ISO 27001:2022 认证
从 732 字节到无影无踪:在生产环境中关停 Copy Fail
什么是 AI 原生云?
Together AI 亮相 NVIDIA GTC 2026:探索我们在研究与产品领域的最新创新
介绍 Together AI 的全新形象
Together AI 欢迎 Alon Gavrielov 出任基础设施战略副总裁
Together Python SDK v2.0 正式发布
Together AI 与 Meta 达成合作,将 PyTorch 强化学习引入 AI 原生云
Together AI 创业加速器正式发布,专为 AI 原生应用打造
Together AI 欢迎 Mahadev Konar 出任基础设施工程高级副总裁
赋能安全 AI:Together AI 获得 SOC 2 Type 2 合规认证
Together AI 收购 Refuel.ai,为构建生产级 AI 应用的开发者和企业解锁数据
从 AWS 到 Together Dedicated Endpoints:Arcee AI 迈向更高推理灵活性的历程
扩展 AI 伴侣:Dippy AI 如何借助 Together Dedicated Endpoints 达到每分钟超 400 万 Token
Together AI 获 SemiAnalysis 授予 ClusterMAX™ 金牌评级
Together AI 成为 NVIDIA 云合作伙伴,以增强加速 AI 产品与服务
Together AI 宣布完成 3.05 亿美元 B 轮融资,以扩展面向开源和企业 AI 的 AI 加速云
Together AI 收购 CodeSandbox,推出首个面向生成式 AI 的代码解释器
AWS Marketplace 现已提供 Together AI,以加速企业 AI 开发
Together AI 将与 Hypertec Cloud 合作,共同构建搭载 3.6 万块 Blackwell GPU 的增强版 NVIDIA GB200 集群
Zomato 如何构建 AI 客服机器人,使客户满意度翻倍并扩展到每分钟处理 1,000 条以上消息
推出 Together 企业平台:可在任何环境中安全运行生成式 AI,推理速度提升 2 倍并实现持续模型优化
Together AI 欢迎 Kai Mak 出任 CRO,以加速全球 AI 原生公司与企业的生成式 AI 采用
Together AI 与 NVIDIA 合作,在 NVIDIA DGX Cloud 上为企业提供 Llama 3.1 模型支持
Flash Attention 获得首届斯坦福开源软件奖
Together AI 与 Snowflake 合作,将 Arctic LLM 带给企业客户
宣布完成由 Salesforce Ventures 领投的 $106M 融资轮
介绍 Together AI 首席科学家 Tri Dao,他发布 FlashAttention-2 以加速模型训练与推理
Together AI 与 Snorkel AI 助力企业构建专有 LLM
Together 完成 $20M 种子轮融资,用于构建开源 AI 与云平台
Together 与 Crusoe 如何降低生成式 AI 的碳排放影响
Together Compiler:面向 AI 推理的持续编译
从静态推理到多态推理:生产级开源推理系统的新时代
Together GPU 集群的自动修复:从 GPU 故障到健康节点
Together Post-Training:前沿级模型塑造,以适合你的方式
Meta Muse Spark Open 已在 Together AI 上线
携手 IBM Cloud 和 NVIDIA 扩展我们的企业级推理容量
Together Link:在你已使用的运行框架中,提供前沿质量的开放模型
如何用 $17 训练你自己的 Jev
金丝雀发布:在生产环境中无停机升级模型
一家全球金融科技公司如何借助 Dedicated Model Inference 扩展编码智能体流量
从闭源模型迁移到开源模型,Together
Together AI 扩展微调服务,新增更多模型、实时指标和更精细的控制。
译文由英文原文机器翻译,术语按行业惯例统一,可在文末展开原文核对。
查看英文原文(Expanding our enterprise inference capacity with IBM Cloud and NVIDIA)
Introducing Polymorphic Inference, starting with Together Compiler →
Introducing Together Post-Training: Better models, faster runs, lower costs →
Introducing Together Link: Run open models inside the harness you already use →
The Open Source AI Stack: models, inference, routers, harnesses & tools →
GLM-5.3 vs. GLM 5.3 Flash on DeepSWE →
⚡ On-demand B200s now available on Together GPU Clusters →
High-performance inference as APIs
Inference for batch workloads
Token-based capacity with SLAs
Dedicated Model Inference
Inference on custom hardware
Dedicated Container Inference
Inference for custom models
Run open models in your harness
Inference that gets better over time
Explore Top Open-Source Models
Reliable GPU clusters at scale
Custom infrastructure at frontier scale
Build development environments for AI
Store model weights & data securely
Define your own RL and SFT loop
Launch managed SFT and DPO jobs
Fine-tune top open-source models
Systems research for production AI
All our research publications
Technical docs for Together AI
Our latest news & blog posts
Our open-source demo apps
Practical implementation guides
Build better with open models
Run open models in your harness
Explore our events calendar
Open-source ROI calculator
High-performance inference as APIs
Inference for batch workloads
Token-based capacity with SLAs
Dedicated Model Inference
Inference on custom hardware
Dedicated Container Inference
Inference for custom models
Run open models in your harness
Inference that gets better over time
Explore Top Open-Source Models
Reliable GPU clusters at scale
Custom infrastructure at frontier scale
Build development environments for AI
Store model weights & data securely
Define your own RL and SFT loop
Launch managed SFT and DPO jobs
Fine-tune top open-source models
Systems research for production AI
All our research publications
Technical docs for Together AI
Our latest news & blog posts
Our open-source demo apps
Practical implementation guides
Build better with open models
Run open models in your harness
Explore our events calendar
Open-source ROI calculator
Expanding our enterprise inference capacity with IBM Cloud and NVIDIA
We’re excited to share that Together AI is working with IBM and NVIDIA to scale enterprise-grade AI inference, starting with a large cluster of NVIDIA B300 GPUs on IBM Cloud backed by NVIDIA Spectrum-X Ethernet networking. It's the first dedicated, large-scale inference cluster of its kind on IBM Cloud, and we're the first customer running on it.
What's actually happening
The infrastructure: A dedicated NVIDIA B300 GPU cluster, purpose-built for inference, running on IBM Cloud.
The model: We operate the inference layer, IBM provides the cloud, NVIDIA delivers the silicon and networking.
The trajectory: We're planning for the future as token demand goes parabolic
We started Together AI because we believe the future of AI shouldn't be owned by a handful of closed labs. That bet is paying off faster than even we expected: Hundreds of trillions of tokens served per month to over a million developers, and demand keeps climbing.
Enterprises and AI-native companies choose open models for two simple reasons: their sovereign data stays theirs and they get frontier-level performance at a fraction of closed-model cost. The bigger the usage, the better that math looks.
With this collaboration:
NVIDIA brings the silicon — B300 GPUs and Spectrum-X Ethernet networking engineered for high-throughput inference.
IBM brings decades of running mission-critical infrastructure for the world's largest enterprises.
Together AI brings the inference platform — the fastest, most efficient way to run open models in production, hardened by some of the most demanding AI workloads on the planet.
Put those together and the result is simple: enterprise-grade inference at massive scale – more production grade tokens, with the reliability, security and guardrails enterprises have come to expect.
Open-source AI has to run everywhere, at scale, as fast and reliably as anything closed. We have spent the last few years making sure it can and this collaboration is a big step toward exactly that.
From Static to Polymorphic Inference: A new era for production open-source inference systems
Expanding our enterprise inference capacity with IBM Cloud and NVIDIA
Together AI announces strategic partnership with Moonshot AI to natively serve Kimi models
Announcing our $800M Series C to accelerate the shift to open-source AI
Building trust in enterprise AI: Together AI earns ISO 27001:2022 certification
From 732 bytes to nowhere: shutting down Copy Fail in production
What is an AI Native Cloud?
Together AI at NVIDIA GTC 2026: Explore our latest innovations across research and products
Introducing Together AI’s new look
Together AI welcomes Alon Gavrielov as VP of Infrastructure Strategy
Announcing Together Python SDK v2.0
Together AI and Meta partner to bring PyTorch Reinforcement Learning to the AI Native Cloud
Announcing the Together AI Startup Accelerator, purpose-built for AI Native Apps
Together AI welcomes Mahadev Konar as SVP for Infrastructure Engineering
Powering Secure AI: Together AI Achieves SOC 2 Type 2 Compliance
Together AI acquires Refuel.ai to unlock data for developers and businesses building production-grade AI applications
From AWS to Together Dedicated Endpoints: Arcee AI's journey to greater inference flexibility
Scaling AI Companions: How Dippy AI Reached Over 4 Million Tokens/Minute with Together Dedicated Endpoints
Together AI Awarded ClusterMAX™ Gold Rating by SemiAnalysis
Together AI becomes NVIDIA Cloud Partner to bolster accelerated AI offerings
Together AI Announces $305M Series B to Scale AI Acceleration Cloud for Open Source and Enterprise AI
Together AI acquires CodeSandbox to launch first-of-its-kind code interpreter for generative AI
AWS Marketplace now offering Together AI to accelerate enterprise AI development
Together AI to Co-Build Turbocharged NVIDIA GB200 Cluster with 36K Blackwell GPUs in Partnership with Hypertec Cloud
How Zomato built an AI customer support bot that doubled customer satisfaction and scaled to over 1,000 messages per minute
Introducing The Together Enterprise Platform: Run GenAI securely in any environment, with 2x faster inference and continuous model optimization
Together AI welcomes Kai Mak as CRO to accelerate gen AI adoption for AI natives and enterprises globally
Together AI and NVIDIA collaborate to power Llama 3.1 models for enterprises on NVIDIA DGX Cloud
Flash Attention received the inaugural Stanford open source software award
Together AI partners with Snowflake to bring Arctic LLM to Enterprise customers
Announcing $106M round led by Salesforce Ventures
Introducing Together AI Chief Scientist Tri Dao, as he releases FlashAttention-2 to speed up model training and inference
Together AI and Snorkel AI empower enterprises to build proprietary LLMs
Together’s $20M seed funding to build open-source AI and cloud platform
How Together and Crusoe are reducing the carbon impact of generative AI
Together Compiler: Continual Compilation for AI inference
From Static to Polymorphic Inference: A new era for production open-source inference systems
Auto repair for Together GPU Clusters: from GPU fault to healthy node
Together Post-Training: frontier-grade model shaping, the way that fits you
Meta Muse Spark Open is live on Together AI
Expanding our enterprise inference capacity with IBM Cloud and NVIDIA
Together Link: frontier-quality open models in the harness you already use
How to train your own Jev for $17
Canary rollouts: upgrade models in production without downtime
How a global fintech scaled coding agent traffic with Dedicated Model Inference
Migrating from closed to open source models, Together
Together AI expands fine-tuning service with more models, live metrics, and finer controls
原文为英文,正文由自动抓取并保留原文。
原文发布于 Together AI Blog(Expanding our enterprise inference capacity with IBM Cloud and NVIDIA),标题、摘要与正文由机器翻译,术语按行业惯例统一,未经人工逐句校订。