从零构建 AI 文本检测器
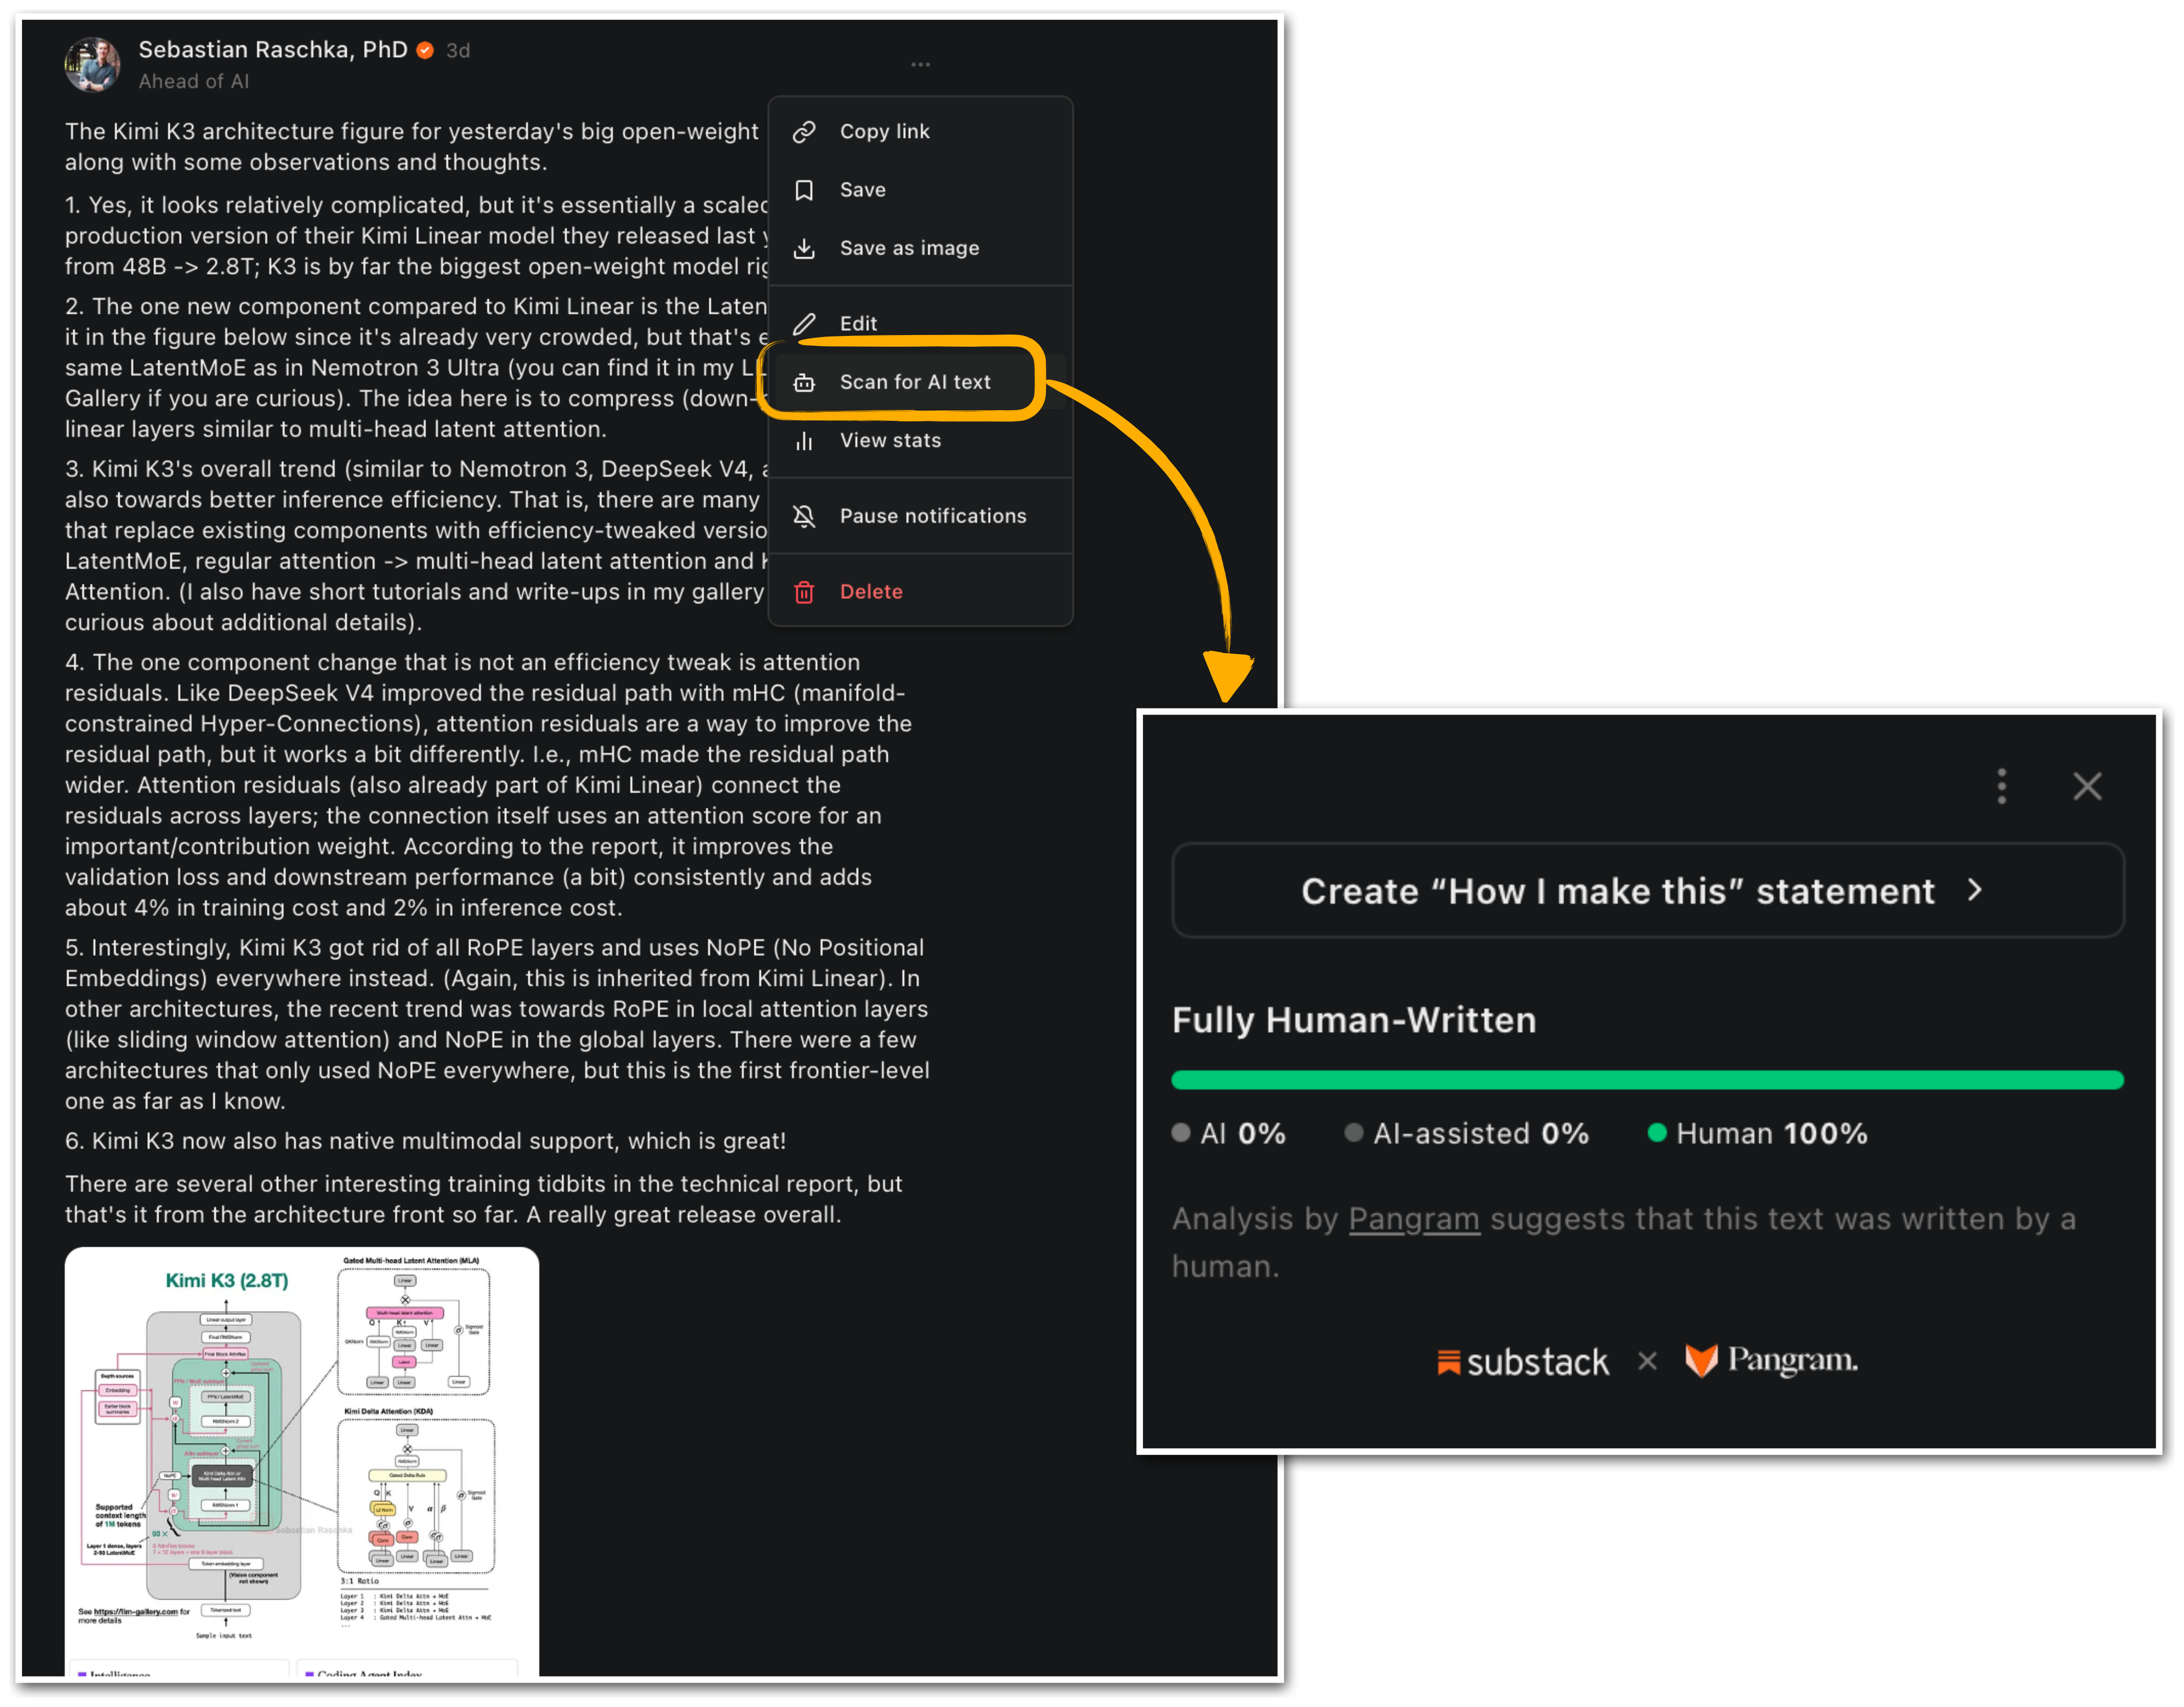
Substack 最近在 UI 中推出了其 AI 检测器功能,这非常有意思。
另外,很多人问我有哪些有趣的本地 DIY LLM 项目,可以作为演示来展示小语言模型(SLM)能做什么。
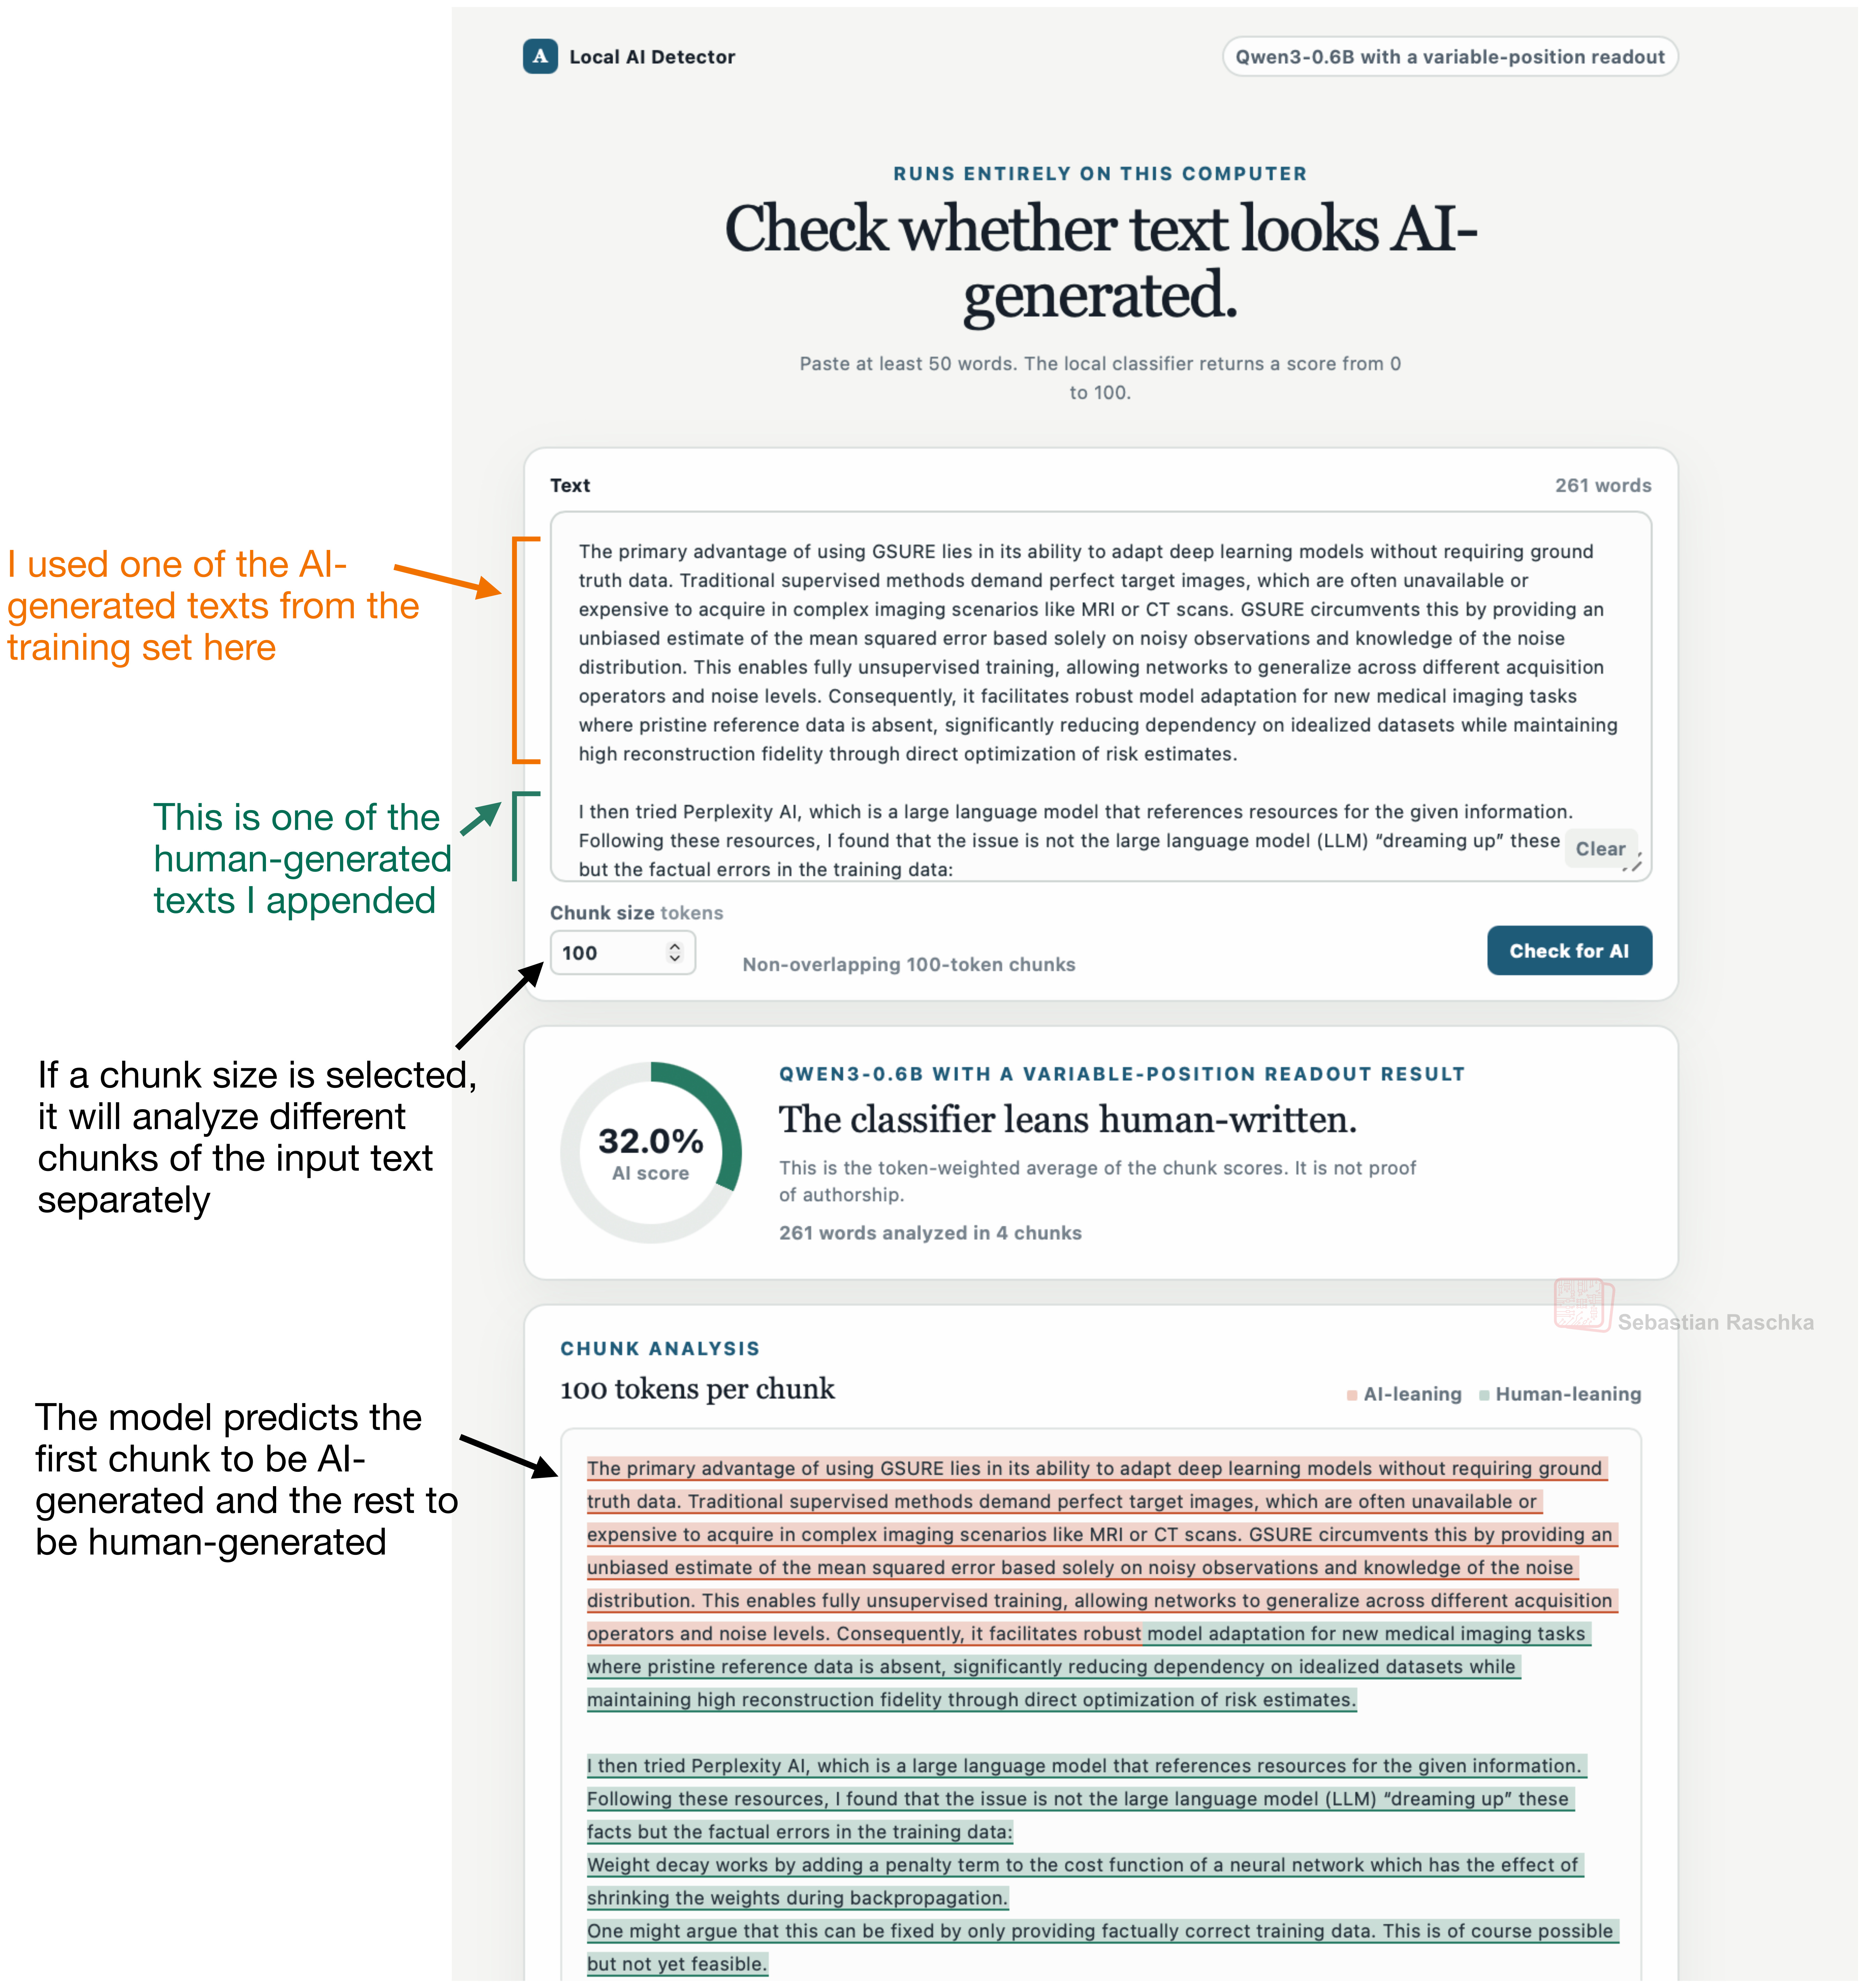
把这两件事结合起来,我觉得展示如何实现一个 AI 检测器会很有意思。我还会把它用作验证器,来训练一个小语言模型生成能规避检测的文本。这是一个小型教学项目,用于研究 AI 检测器的局限性,并探索一种基于验证器的 LLM 应用,它超越了常规的、在数学和代码上训练的推理模型。
那么,如上所述,本教程的目标是通过亲手构建一个(简单的)AI 检测器,来解释 AI 检测器是如何工作的。
在实践中,这样的检测器可以用来过滤垃圾内容,也可以用来改善你自己的写作,同时不让它变成 AI 生成的文本。例如,如果你写了一篇长文,想改进拼写和语法,用语法检查工具来润色并提升可读性是很有诱惑力的(而且确实有用)。市面上有各种此类服务,包括 ChatGPT 这样的通用 LLM。然而,这也带来一种风险:这些工具会把你的文字——尽管它仍然是你自己写的——变得过度润色,听起来像 AI,进而被标记为垃圾内容。
例如,借助 AI 检测器,你可以说:“修正我的语法,同时确保我的文本仍然被评为 0% 由 AI 生成。”
总之,虽然我们在这里构建的是一个功能完整的检测器,但目标是解释 1)AI 检测器(可以)如何工作,2)把它作为一个案例研究,引出一个更广泛的话题:如何构建可与 LLM 配合使用的评分器或验证器。
免责声明:AI 检测器本质上是一场猫鼠游戏。AI 检测器可能会学会识别某种指向 AI 生成内容的模式。随后,下一个 LLM 可能会偶然或刻意不表现出该模式,从而避开检测。于是 AI 检测器又必须更新以检测该 LLM,如此循环往复。此外,它也很可能遇到误报(人类撰写的文本被标记为 AI 生成),这一点稍后再谈。
这个项目有几个目标。总体目标当然是说明 AI 检测器如何工作,并展示一个应用型的端到端 LLM 项目,涵盖评估、训练以及面向真实场景使用的本地部署。
其成果是一个可供人类和智能体使用的 AI 检测器 API,以及一个用户友好的 UI。
在这里,我们将开发一种类似于 Pangram 模型的方法;据我所知,Substack 的 AI 检测功能背后正是这类模型。
我在 2023 年早些时候写过一篇关于 AI 文本检测的短文:What Are the Different Approaches for Detecting Content Generated by LLMs Such As ChatGPT? And How Do They Work and Differ?
本质上,检测 AI 撰写文本有多种方式,从监督式分类器和基于扰动的概率测试,到困惑度度量和水印。
在本教程中,我们将构建一个返回 0-100 分数的模型。它本质上是一个带有估计概率分数的分类器。该概率分数表示根据该分类器判断,一段文本由 AI 生成的可能性有多大。(或者更准确地说,该分数是分类器基于其训练分布对 AI 生成类别给出的估计概率。不过,我们不应将其解读为文本由 AI 撰写的一般概率。)
为此,我们将微调一个 DistilBERT 分类器(类似于我在早期 Substack 文章《Finetuning Large Language Models》中描述的内容),但等我们进入那个阶段时再提供更多细节。
译文由英文原文机器翻译,术语按行业惯例统一,可在文末展开原文核对。
查看英文原文(Building an AI Text Detector From Scratch)
Substack recently launched its AI detector feature in the UI, which is super interesting.
Separately, lots of people asked me about interesting local do-it-yourself LLM projects as demos to show what small language models (SLMs) are capable of.
Putting one and one together, I thought it would be interesting to show how an AI detector can be implemented. I will also use it as a verifier to train a small language model to produce text that avoids detection. This is a small educational project for studying the limitations of AI detectors and exploring a verifier-based LLM application beyond regular reasoning models trained on math and code.
So, as mentioned above, the intended goal of this tutorial is to explain how AI detectors work by building (a simple) one.
In practice, such a detector can be used to filter out spammy content, but also to potentially improve your personal writing without turning it into AI-generated text. For example, if you wrote a lengthy article and want to improve spelling and grammar, it is tempting (and actually useful) to use a grammar checker to polish it and improve readability. There are different services for that, including general-purpose LLMs like ChatGPT. However, this also runs the risk that these tools turn your writing, even though it’s still your own writing, into something that is then overpolished and now sounds like AI and gets flagged as spammy content.
For example, with an AI checker, one could say, “Fix my grammar while ensuring that my text still scores 0% AI-generated.”
Anyway, while we are building a fully functional checker here, the goal is to explain 1) how AI checkers (can) work and 2) use this as a case study for a more general topic on how to build a scorer or verifier that can be used with LLMs.
Disclaimer: AI checkers are essentially a cat-and-mouse game. AI checkers may learn to detect a certain pattern that is indicative of AI-generated content. Then, the next LLM may incidentally or deliberately not exhibit that pattern and avoid detection. The AI checker then has to be updated to detect said LLM, and so forth. Plus, it’s also likely to encounter false positives (human written text flagged as AI-generated), but more on that later.
Project goals
There are several goals of this project. The overarching goal is, of course, to illustrate how AI detectors work and show an applied end-to-end LLM project including evaluation, training, and local deployment for real-world use.
The outcome of this is an AI-detector API that can be used by humans and agents, and a user-friendly UI.
Method overview
Here, we are going to develop a method similar to Pangram models, which, as far as I know, are behind Substack AI detection feature.
I wrote a short article about AI-text detection a while back in 2023: What Are the Different Approaches for Detecting Content Generated by LLMs Such As ChatGPT? And How Do They Work and Differ?
In essence, there are different ways to detect AI-written text, from supervised classifiers and perturbation-based probability tests to perplexity measures and watermarking.
In this tutorial, we will build a model that returns a 0-100 score. It’s essentially a classifier with an estimated probability score. The probability score will denote how likely a text is AI-generated according to the classifier. (Or, to be precise the score is the classifier’s estimated probability for the AI-generated class based on its training distribution. However, we shouldn’t interpreted it as a general probability that the text was written by AI.)
For this, we are going to fine-tune a DistilBERT classifier (similar to what I described in one of my early Substack articles, Finetuning Large Language Models), but more details on that later when we get to that stage.
正文保留英文原文,标题与摘要由机器翻译。
原文发布于 Sebastian Raschka(Building an AI Text Detector From Scratch),标题、摘要与正文由机器翻译,术语按行业惯例统一,未经人工逐句校订。


