GPT-6 Astra、循环 Transformer 与隐藏推理
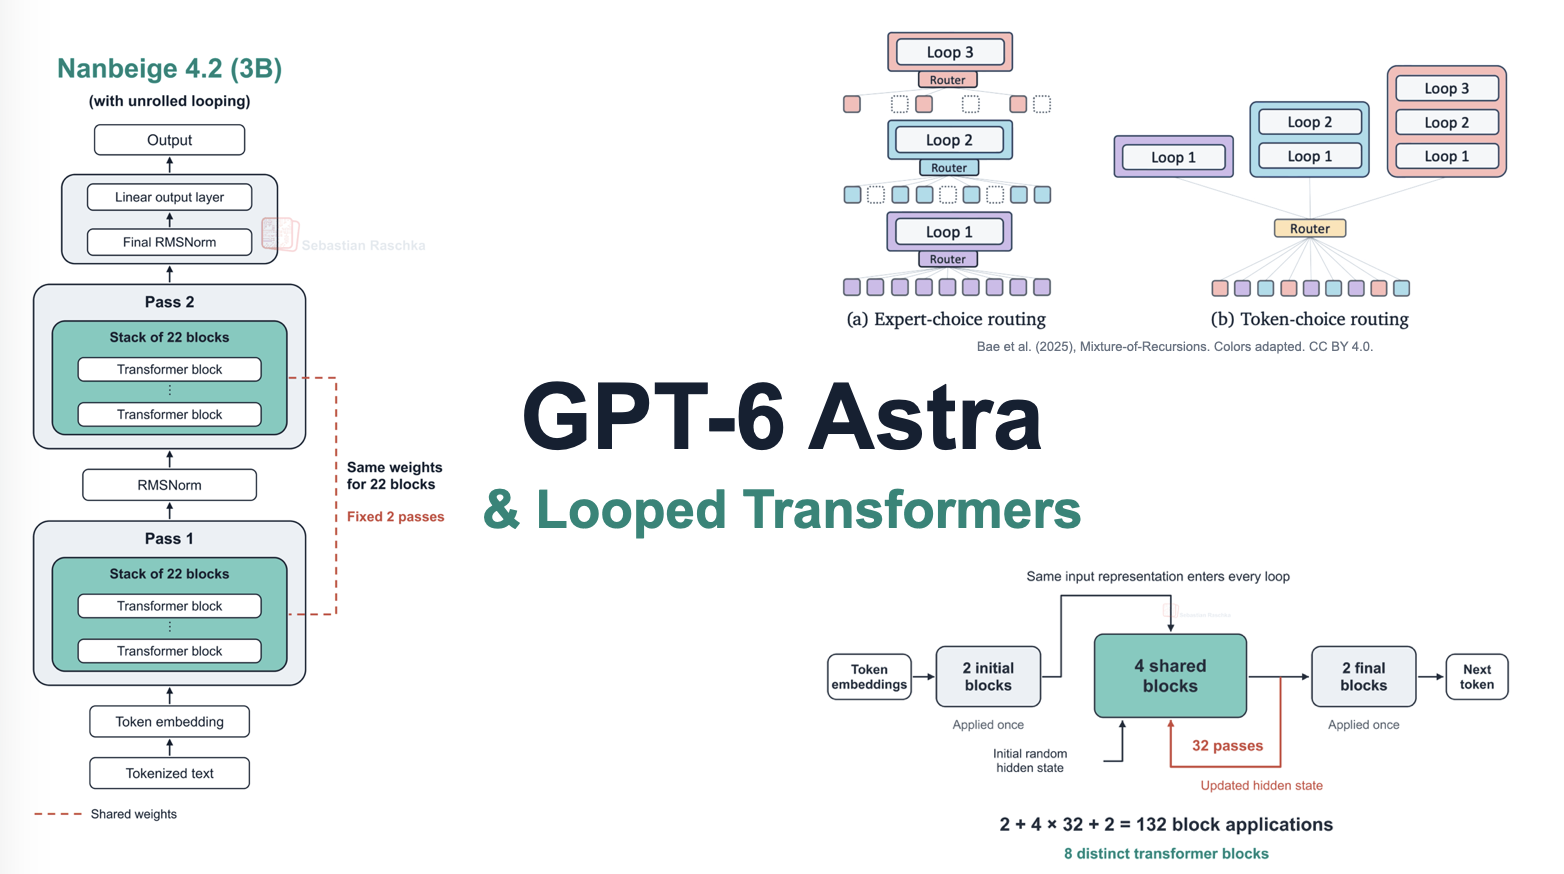
过去几周发生了很多事。我相信 OpenAI 的 GPT-6 Astra 现在是所有人最关注的焦点。尤其是关于它的性能、循环 transformer/递归深度方面的讨论,以及有关 Astra“隐藏”其推理轨迹(即思维链)的传闻。
因此,在本文中,我想先谈谈对 Astra 的一些初步印象,以及我对这一切将走向何方的思考。然后,我会详细讨论什么是“循环 transformer”,以及这与隐藏思维链有何关系(或者说,是否真的有关)。
最后,在介绍完循环 transformer 的基础知识后,我想重点分享近期相关研究论文中的一些新见解。
附:我这里还有一个更短的视频版本,是在撰写这篇更长的文章之前录制的:
先说重点。在深入探讨架构传闻和相关研究文献之前,让我先简要总结一些关于 GPT-6 Astra 的观察和花絮。
上周,OpenAI 的新模型 GPT-6 Astra 在大张旗鼓中发布。过去几天我一直在使用它,它是一款异常出色的模型,可能是截至本文写作时我用过的最好的模型。但它究竟在哪些方面有所改进,又是如何改进的?
Astra 是我迄今为止用过的最好的模型,而且它在 3D 渲染和动画任务上表现得出奇地好(相对于其他模型而言)。我的意思是,虽然它在几乎所有类别(写作、数学、编程等)上都大幅超越前代 GPT-5.6,但在图形演示方面尤为突出。
这一点也体现在基准测试中。例如,如下图所示,GPT-6 Astra 在数学和编程方面表现非常出色。
其中一个亮点(未在图中显示)是,Astra 在 ARC-AGI-3 基准测试上也达到了 99.9%(GPT-5.6 Sol 仅为 7.8%),该基准测试衡量的是解逻辑谜题与泛化能力的综合表现。不过,数学、编程和计算机使用类基准测试更值得关注,因为它们更接近真实使用场景。(不过,随后 OpenAI 还有一篇文章描述了评测框架的另外两项改动,同样将 GPT 5.6 Sol 的性能提升到三倍,从 13.3% 提高到 38.3%。)
回到 Artificial Analysis Coding Agent Index v1.4(上一张图的右下角),它融合了若干智能体式编程任务;GPT-6 Astra 显然处于前沿,但并未实现大幅领先。这一点在下面所示的通用 Artificial Analysis Intelligence Index 中同样可以看到,该指数融合了不同类型的任务,而不只是编程任务。
Artificial Analysis 基准测试的一大优势在于它们是独立的,因此可能比模型开发者自行评测的基准测试更值得信赖。
评测框架的设置取决于具体基准测试。例如,GDPval-AA 和 AA-Briefcase 在它们所比较的不同 LLM 上使用其开源的精简 Stirrup 框架。在上面所示的 Intelligence Index v4.2 中,Terminal-Bench v2.1 使用 Terminus 2,τ³-Banking 使用 τ-Bench 框架。单独的 Coding Agent Index 也比较了不同的编程智能体框架。
对于使用共享框架的评测来说,这更接近同等条件下的对比。与此同时,在模型训练过程中,模型通常是以某一个主要框架为目标来开发的(在其他框架上的微调较少)。此外,主要框架往往是为了贴合并放大模型自身的优势而开发的。
所以,一些智能体式评测可能低估了 Astra 在其主运行框架下的表现。这对它的 Intelligence Index 分数有多大影响,还需要通过在同一批任务上跨运行框架比较 Astra 来验证。
顺带说一句,正如一位同事最近向我建议的(Claude Code 负责人也这么推荐),删除(/归档)你现有的一些 AGENTS.md 内容和 SKILL.md 文件也许并不是坏主意,因为较新的 LLM 在理解提示词、解决手头问题方面已经变得更高效。过多的手把手引导可能会不必要地束缚较新的模型,导致更差的解决方案。
当然,我并不是建议再也别用 SKILL.md 文件了——对某些工作流来说,它们在复用时确实能提升效率,因为模型不必重新摸索一遍。但我想说的是,有些工作流并不需要描述,而“旧”的描述可能已不再理想,LLM 或许能给出更好的解决方案。所以,也许是时候更新或重新生成这些指令文件了。
GPT-6 Astra 在图像和渲染任务上似乎格外强。当这些任务涉及与图形用户界面交互时,它还展现出电脑操作(computer use)能力,也就是说模型通过 Codex/ChatGPT 应用在你本地电脑上操作软件。
电脑操作正是这款模型相较其他模型真正出彩的地方,而且任何与图形相关的东西在社交媒体平台上都能成为有趣又直观的演示。外面有大量令人印象深刻的演示案例,从在 Blender 中建模渲染纽约市,到虚拟的看房参观之旅。
举个例子,下面是一组对比:我让 GPT-6 Astra Medium 和 High 在我电脑上、用鼠标在浏览器版 MS Paint 里重画了一张我的画像(没有用 Extra High 和 Max,因为我不想把 Token 都浪费掉 :))。
这不仅凸显了模型的绘画能力,更重要的是展现了它在用户电脑上使用工具的能力(这里用的是 Paint;你能看到模型通过鼠标光标操作界面)。
这并不是第一个能在框架(harness)内实现通用电脑操作的模型。例如,从今年早些时候起,我就已经成功用 GPT 系列模型完成了一些 UI 任务(比如 Excel 中与报销相关的任务)等等。不过,电脑操作是一项相对较新的能力,由框架赋予,通常感觉还不太成熟。这很合理。LLM 是文本模型,所以更容易实现的自然就是写作、编程以及使用 API 和 CLI。
与此同时,还有许多工具和软件(目前)并不提供 CLI。与其等到有人设计出这样的接口,为什么不改进模型,让它们能够使用图形用户界面呢(而且如前所述,这无论如何都能做出漂亮且令人印象深刻的演示)?这在一定程度上类似于正在兴起的人形机器人发展。当然,人形机器人并不是最高效的机器人,比如在流水线上,那里有专用机器。但它们用途广泛。
所以,我预计未来几个月(或几年)也将是 LLM 与智能体执行框架两个层面不断打磨计算机使用能力的时代。也就是说,除了现有能力之外,在扩展数学与编程能力的同时,模型在训练时也会越来越多地考虑到计算机使用场景。这还将让 LLM 更容易胜任科技圈之外的日常计算机任务(“嘿 ChatGPT,帮我报个税吧” :))
计算机使用的这一趋势,也与近期有关 OpenAI 购入数万台 Mac Mini 和 Mac Studio 用于强化学习的报道相吻合。在这里,Mac 并不是真的用来训练模型(做这件事用 GPU 更好),而是为了在模型训练过程中把 macOS 暴露给模型,让它学会使用这一操作系统及其中的工具。
那么,在这些 Mac 上进行的计算机使用训练是如何运作的?简而言之,Mac(确切地说,是其 macOS 操作系统)充当了一个环境,模型可以在训练过程中与之交互。
基本工作流程如下:
给模型一个任务作为提示,例如“打开 xyz 应用并执行 abc”。
向它提供 macOS 界面的截图(这一步通常由执行框架完成)。
随后 LLM 预测鼠标/键盘操作(点击、按键、滚动等)。
在 Mac 上执行这些操作(同样,这一步由执行框架完成)。
将上一步执行操作后所更新环境的新截图输入。
重复步骤 2-5,直到任务成功或失败。
将成功/失败信号和验证器(或评分器)用作训练反馈,包括后训练期间的强化学习;这类似于常规的可验证奖励强化学习(RLVR)。
再次说明,这里的 Mac 主要是充当环境,而不是在训练期间运行或更新模型的机器。模型很可能位于 NVIDIA GPU 上,并通过 API 提供给这台 Mac。顺便一提,NVIDIA 的 CEO 提到,GPT-6 Astra 正在约 100,000 块 Grace Blackwell GPU 上训练。
上一节讨论的对计算机使用训练的侧重,并不是训练流程中的根本性范式转变。GPT-6 Astra(以及未来可预见的任何 LLM)仍然是推理模型。这意味着该 LLM 使用可验证奖励强化学习(RLVR)进行训练,并生成中间推理轨迹(思维链)。
原文较长,译文为节选;译文由英文原文机器翻译,术语按行业惯例统一,可在文末展开原文核对。
查看英文原文(GPT-6 Astra, Looped Transformers, and Hidden Reasoning)
A lot has happened in the last few weeks. I am sure that OpenAI’s GPT-6 Astra is top of mind for everyone right now. In particular, thoughts on its performance, the looped transformer/recurrent depth aspects, and rumors that Astra is “hiding” its reasoning trace (i.e., chain of thought).
So, in this article, I want to start with some brief impressions of Astra and some thoughts on where all this is headed. Then, I will discuss, in detail, what “looped transformers” are, and how (or rather, if) this relates to hiding chains of thought.
Lastly, after covering the basics of the looped transformer, I wanted to highlight some new insights from recent research papers on the topic.
PS: I also have a shorter video version here that I recorded before writing this more extended article:
1. GPT-6 Astra impressions
First things first. Before getting into the architecture rumors and related research literature, let me briefly summarize some GPT-6 Astra observations and tidbits.
Last week, OpenAI’s new GPT-6 Astra was released with a big fanfare. I used it over the past couple of days, and it’s an exceptionally good model, likely the best I’ve used as of this writing. But what, exactly, has it improved, and how?
1.1 Astra benchmarks
Astra is the best model I’ve used so far, and it’s disproportionately good at 3D rendering and animation tasks (relative to other models). With that, I mean that while it leapfrogs its GPT-5.6 predecessor in practically all categories (writing, math, coding, and more), it especially does so when it comes to graphical demos.
We can see this also reflected in the benchmarks. For instance, GPT-6 Astra is really good at math and coding, as shown below.
One of the highlights (not shown in the figure) is that Astra also achieves 99.9% on the ARC-AGI-3 benchmark (GPT-5.6 Sol only 7.8%), which measures a mix of solving logic puzzles and generalization. However, the math, coding, and computer use benchmarks are more interesting because they are closer to real-world use. (However, there was then also an article by OpenAI describing two further changes to the harness that also tripled GPT 5.6 Sol’s performance from to 13.3% to 38.3%.)
Coming back to the Artificial Analysis Coding Agent Index v1.4 (lower right in the previous figure), which blends several agentic coding tasks, GPT-6 Astra is clearly at the frontier, but it doesn’t pull ahead by leaps and bounds. This can also be seen in the general Artificial Analysis Intelligence Index shown below, which blends different types of tasks, not just coding tasks.
Now, the big advantage of Artificial Analysis benchmarks is that they are independent and thus may be a bit more trustworthy than self-evaluated benchmarks by model developers.
The harness setup depends on the benchmark. For example, GDPval-AA and AA-Briefcase use their open-source, minimal Stirrup harness across the different LLMs they compare. In the Intelligence Index v4.2 shown above, Terminal-Bench v2.1 uses Terminus 2, and τ³-Banking uses the τ-Bench harness. The separate Coding Agent Index also compares different coding-agent harnesses.
For evaluations that use a shared harness, this makes it more of an apples-to-apples comparison. At the same time, during model training, models are typically developed with one primary harness in mind (and fine-tuned less on other harnesses). Plus, the primary harness is often developed to suit and amplify a model’s strengths.
So, some of the agentic evaluations might underestimate how well Astra performs in its primary harness. How much this affects its Intelligence Index score would need to be tested by comparing Astra across harnesses on the same tasks.
As a side note, as a colleague recently suggested to me (as also recommended by the Claude Code lead), it’s maybe not a bad idea to delete (/archive) some of your existing AGENTS.md contents and SKILL.md files, as newer LLMs have become more efficient at understanding the prompt and solving the problem at hand. The extra hand-holding could unnecessarily constrain newer models and lead to worse solutions.
Of course, I am not suggesting never using SKILL.md files again, but for some workflows, because they can improve efficiency upon reuse, since the model doesn’t have to rediscover them. But what I am suggesting is that some workflows don’t need describing, and “old” descriptions may no longer be ideal, and the LLM may be able to come up with better solutions. So, it’s perhaps time to update or regenerate said instruction files.
1.2 Computer use capabilities
GPT-6 Astra seems to be exceptionally strong in image and rendering tasks. When these tasks involve interacting with graphical user interfaces, they also demonstrate computer-use capabilities, meaning the model operates software on your local computer through the Codex/ChatGPT app.
Computer use is where the model really shines compared to others, and anything graphic-related also makes for interesting and intuitive demos on social media platforms. There are tons of examples of impressive demos out there, from modeling rendering New York City in blender to virtual open house tours.
To pick one example, below is a comparison where I had GPT-6 Astra Medium and High redraw a picture of me in a browser version of MS Paint using the mouse on my computer (not Extra High and Max, because I didn’t want to waste all my tokens :)).
This highlights not only the model’s artistic capabilities but, more importantly, its ability to use tools on one’s computer (in this case, Paint; you can see the model using the interface via the mouse cursor).
This is not the first model that, inside a harness, is capable of general computer use. For example, I successfully used GPT models for some UI tasks (e.g., expense-related tasks in Excel) and so on since earlier this year. However, computer use is a relatively new capability, enabled by the harness, and usually feels not quite as mature yet. This makes sense. LLMs are text models, so naturally the lower-hanging fruit is writing and coding and using APIs and CLIs.
At the same time, there are many tools and software that don’t expose CLIs (yet), and instead of waiting until someone designs that interface, why not improve models to use graphical user interfaces (and, as mentioned before, this makes for pretty and impressive demos, anyway)? This is somewhat analogous to the emerging humanoid robot developments. Sure, humanoid robots are not the most efficient robots, for example, at the assembly line, where special-purpose machines exist. But they are versatile.
So, I expect the upcoming months (or years) also to be an era of computer use refinement on both the LLM and the agent harness layer. I.e., in addition to the current capabilities, and expanding their math and coding capabilities, models will be trained with an increasing amount of computer use in mind. And this will also make LLMs more accessible for everyday computer tasks outside the tech world (”Hey ChatGPT, please do my tax return” :))
1.3 Computer use training
The computer usage trend is also consistent with the recent reporting that OpenAI purchased tens of thousands of Mac Minis and Mac Studios for Reinforcement Learning. So, here the Macs are not used to literally train the models (it’s better to use GPUs for that) but rather to expose macOS during the model training for the model to learn to use said operating system and the tools therein.
So, how does computer-use training on said Macs work? In short, the Macs (or their macOS operating system, to be precise) serve as an environment that the model can interact with during training.
The basic workflow looks like this:
Prompt the model by giving it a task, such as “open an app xyz and do abc”.
Provide it with screenshots of the macOS interface (this is usually done by the harness).
The LLM then predicts mouse/keyboard actions (click, key presses, scrolling, and so on).
Execute those actions on the Mac (again, this is done by the harness).
Feed new screenshots of the updated environment after performing the actions in the previous step.
Repeat steps 2-5 until the task succeeds or fails.
Use success/failure signals and verifiers (or graders) as training feedback, including reinforcement learning during post-training; this is analogous to regular Reinforcement Learning with Verifiable Rewards (RLVR).
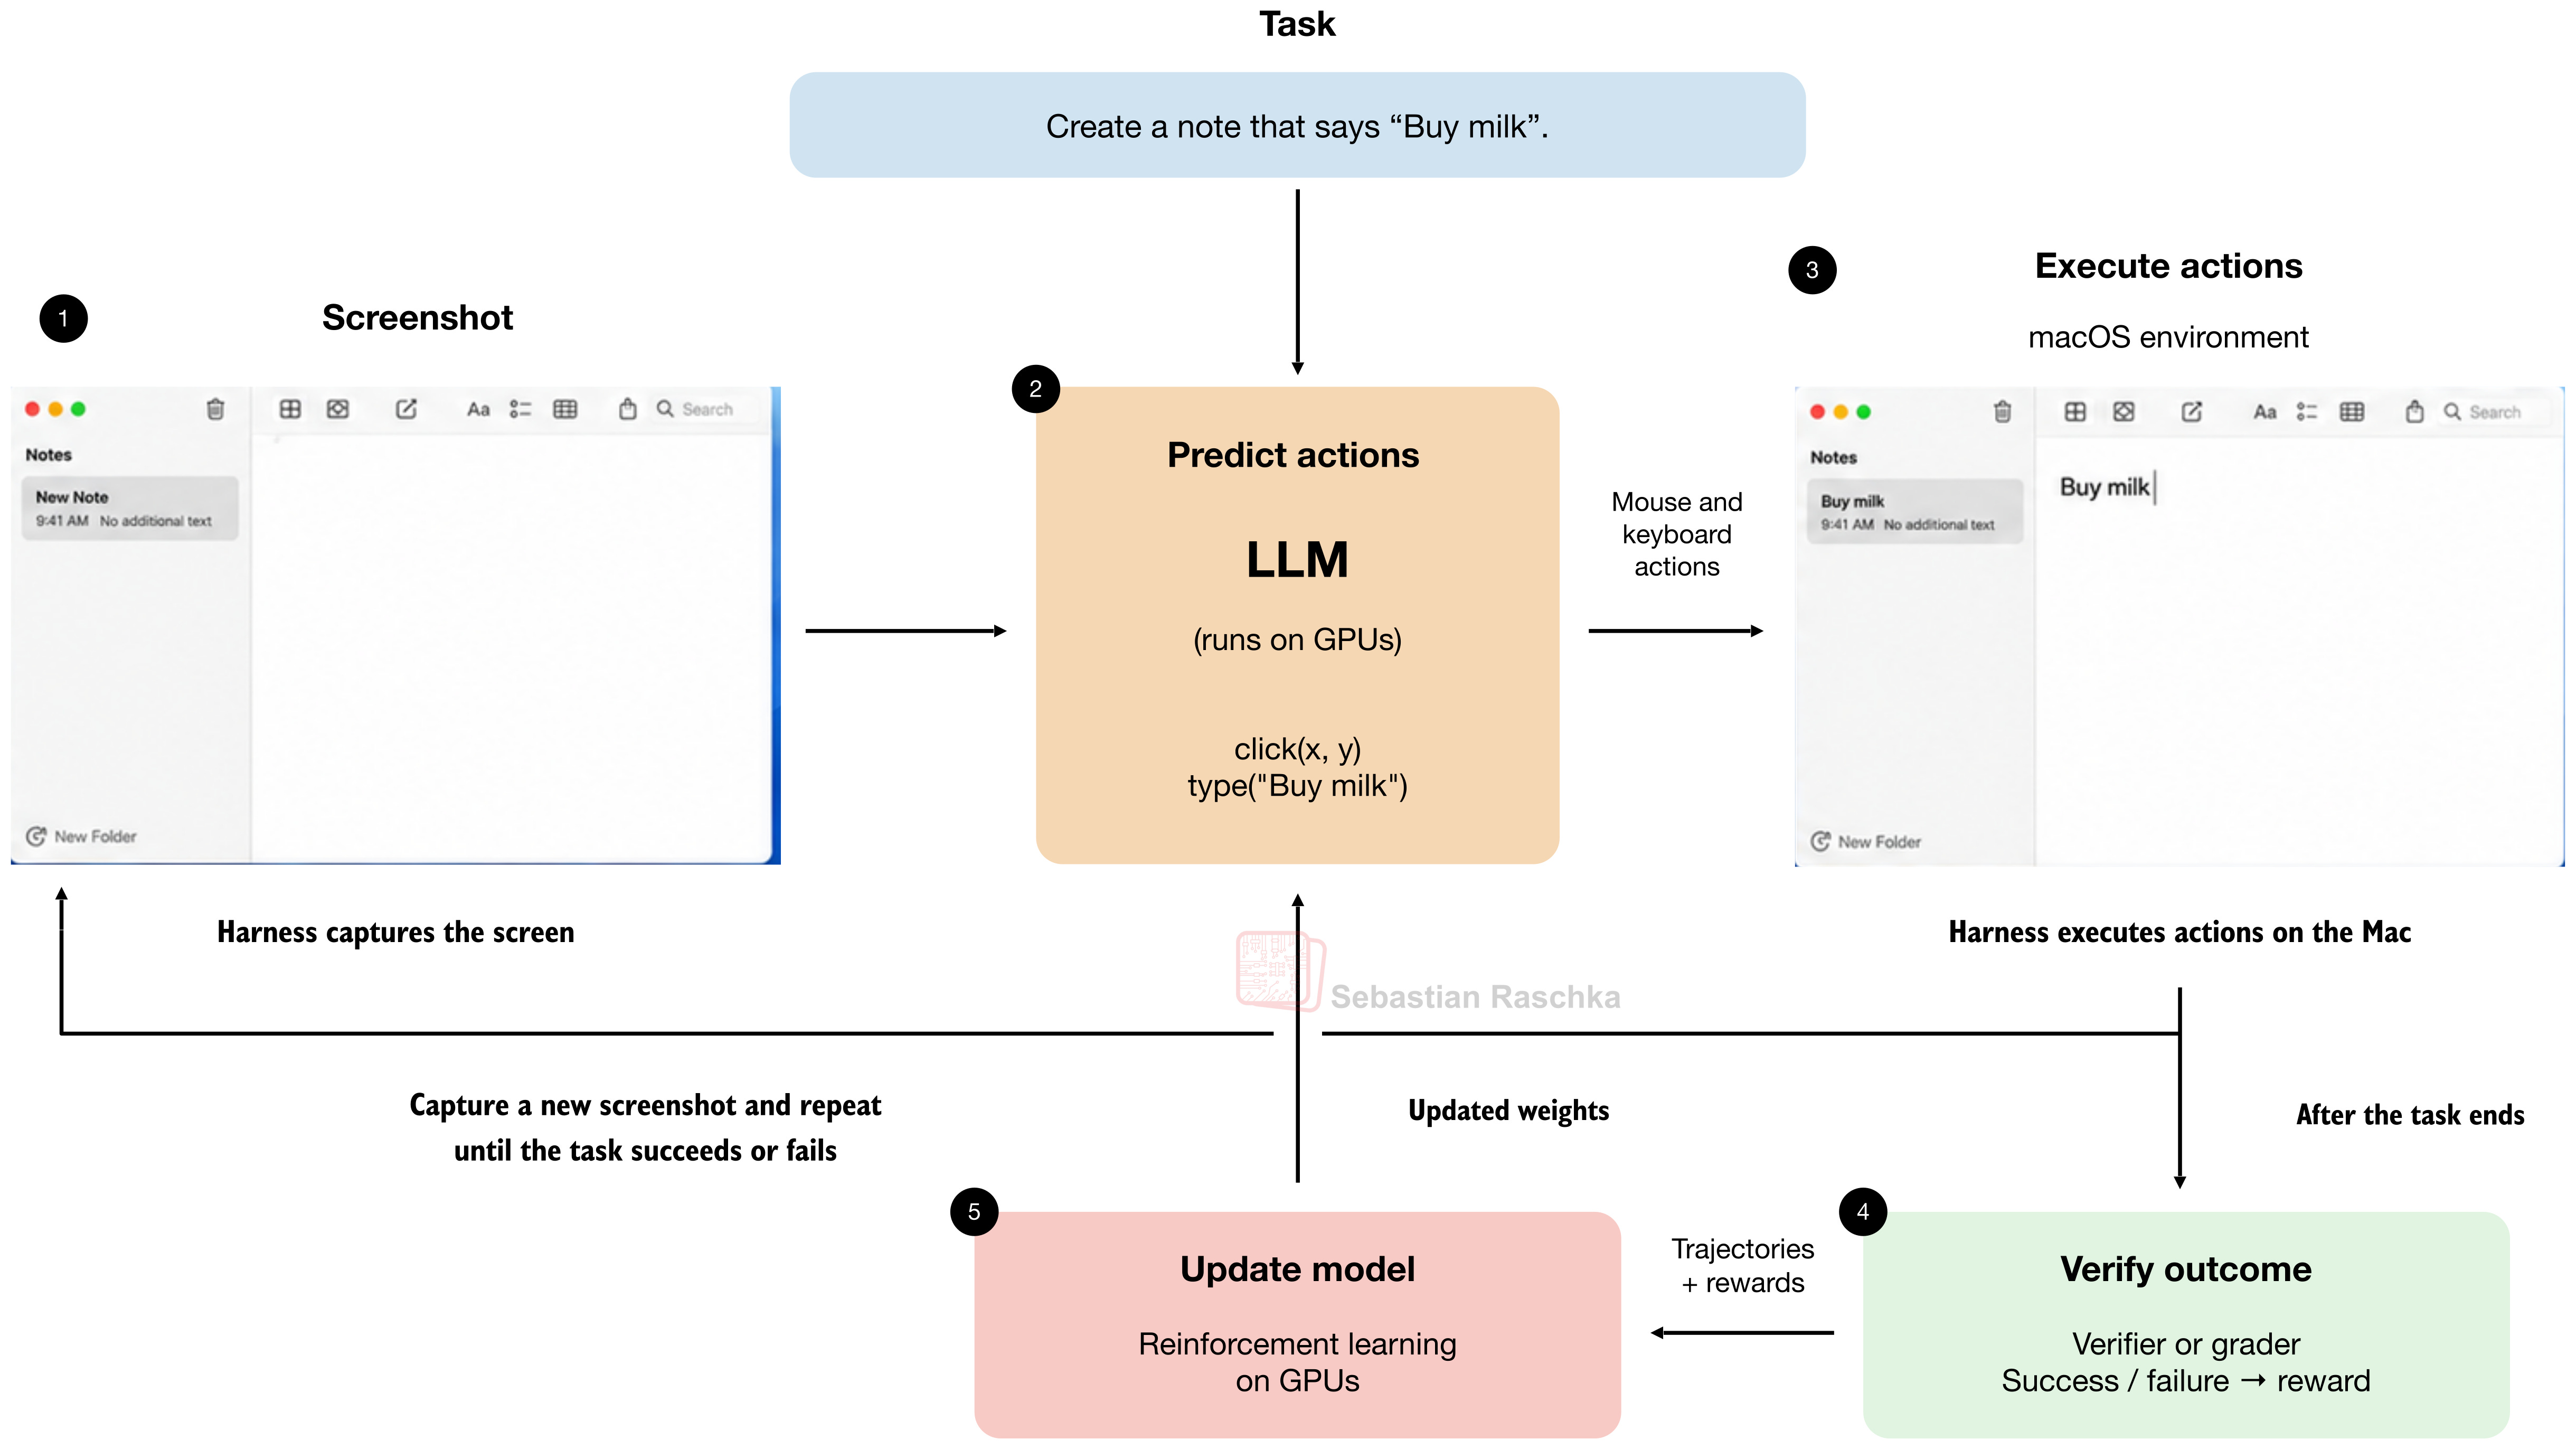
Again, the Mac is mostly the environment here and not the machine for running or updating the model during training. The model likely sits on NVIDIA GPUs and is fed via API to said Mac. By the way, NVIDIA’s CEO mentioned that GPT-6 Astra was being trained on ~100,000 Grace Blackwell GPUs.
1.4 GPT-6 Astra is still a reasoning model
The focus on computer-use training discussed in the previous section is not a fundamental paradigm shift in the training pipeline. GPT-6 Astra (and likely any LLM in the foreseeable future) is still a reasoning model. This means the LLM is trained with reinforcement learning with verifiable rewards (RLVR) and produces intermediate reasoning traces (chains of thought)
But I will discuss the reasoning model aspects of GPT-6 Astra (especially regarding hiding chains of thought) a bit later in this article.
2. Looped transformers
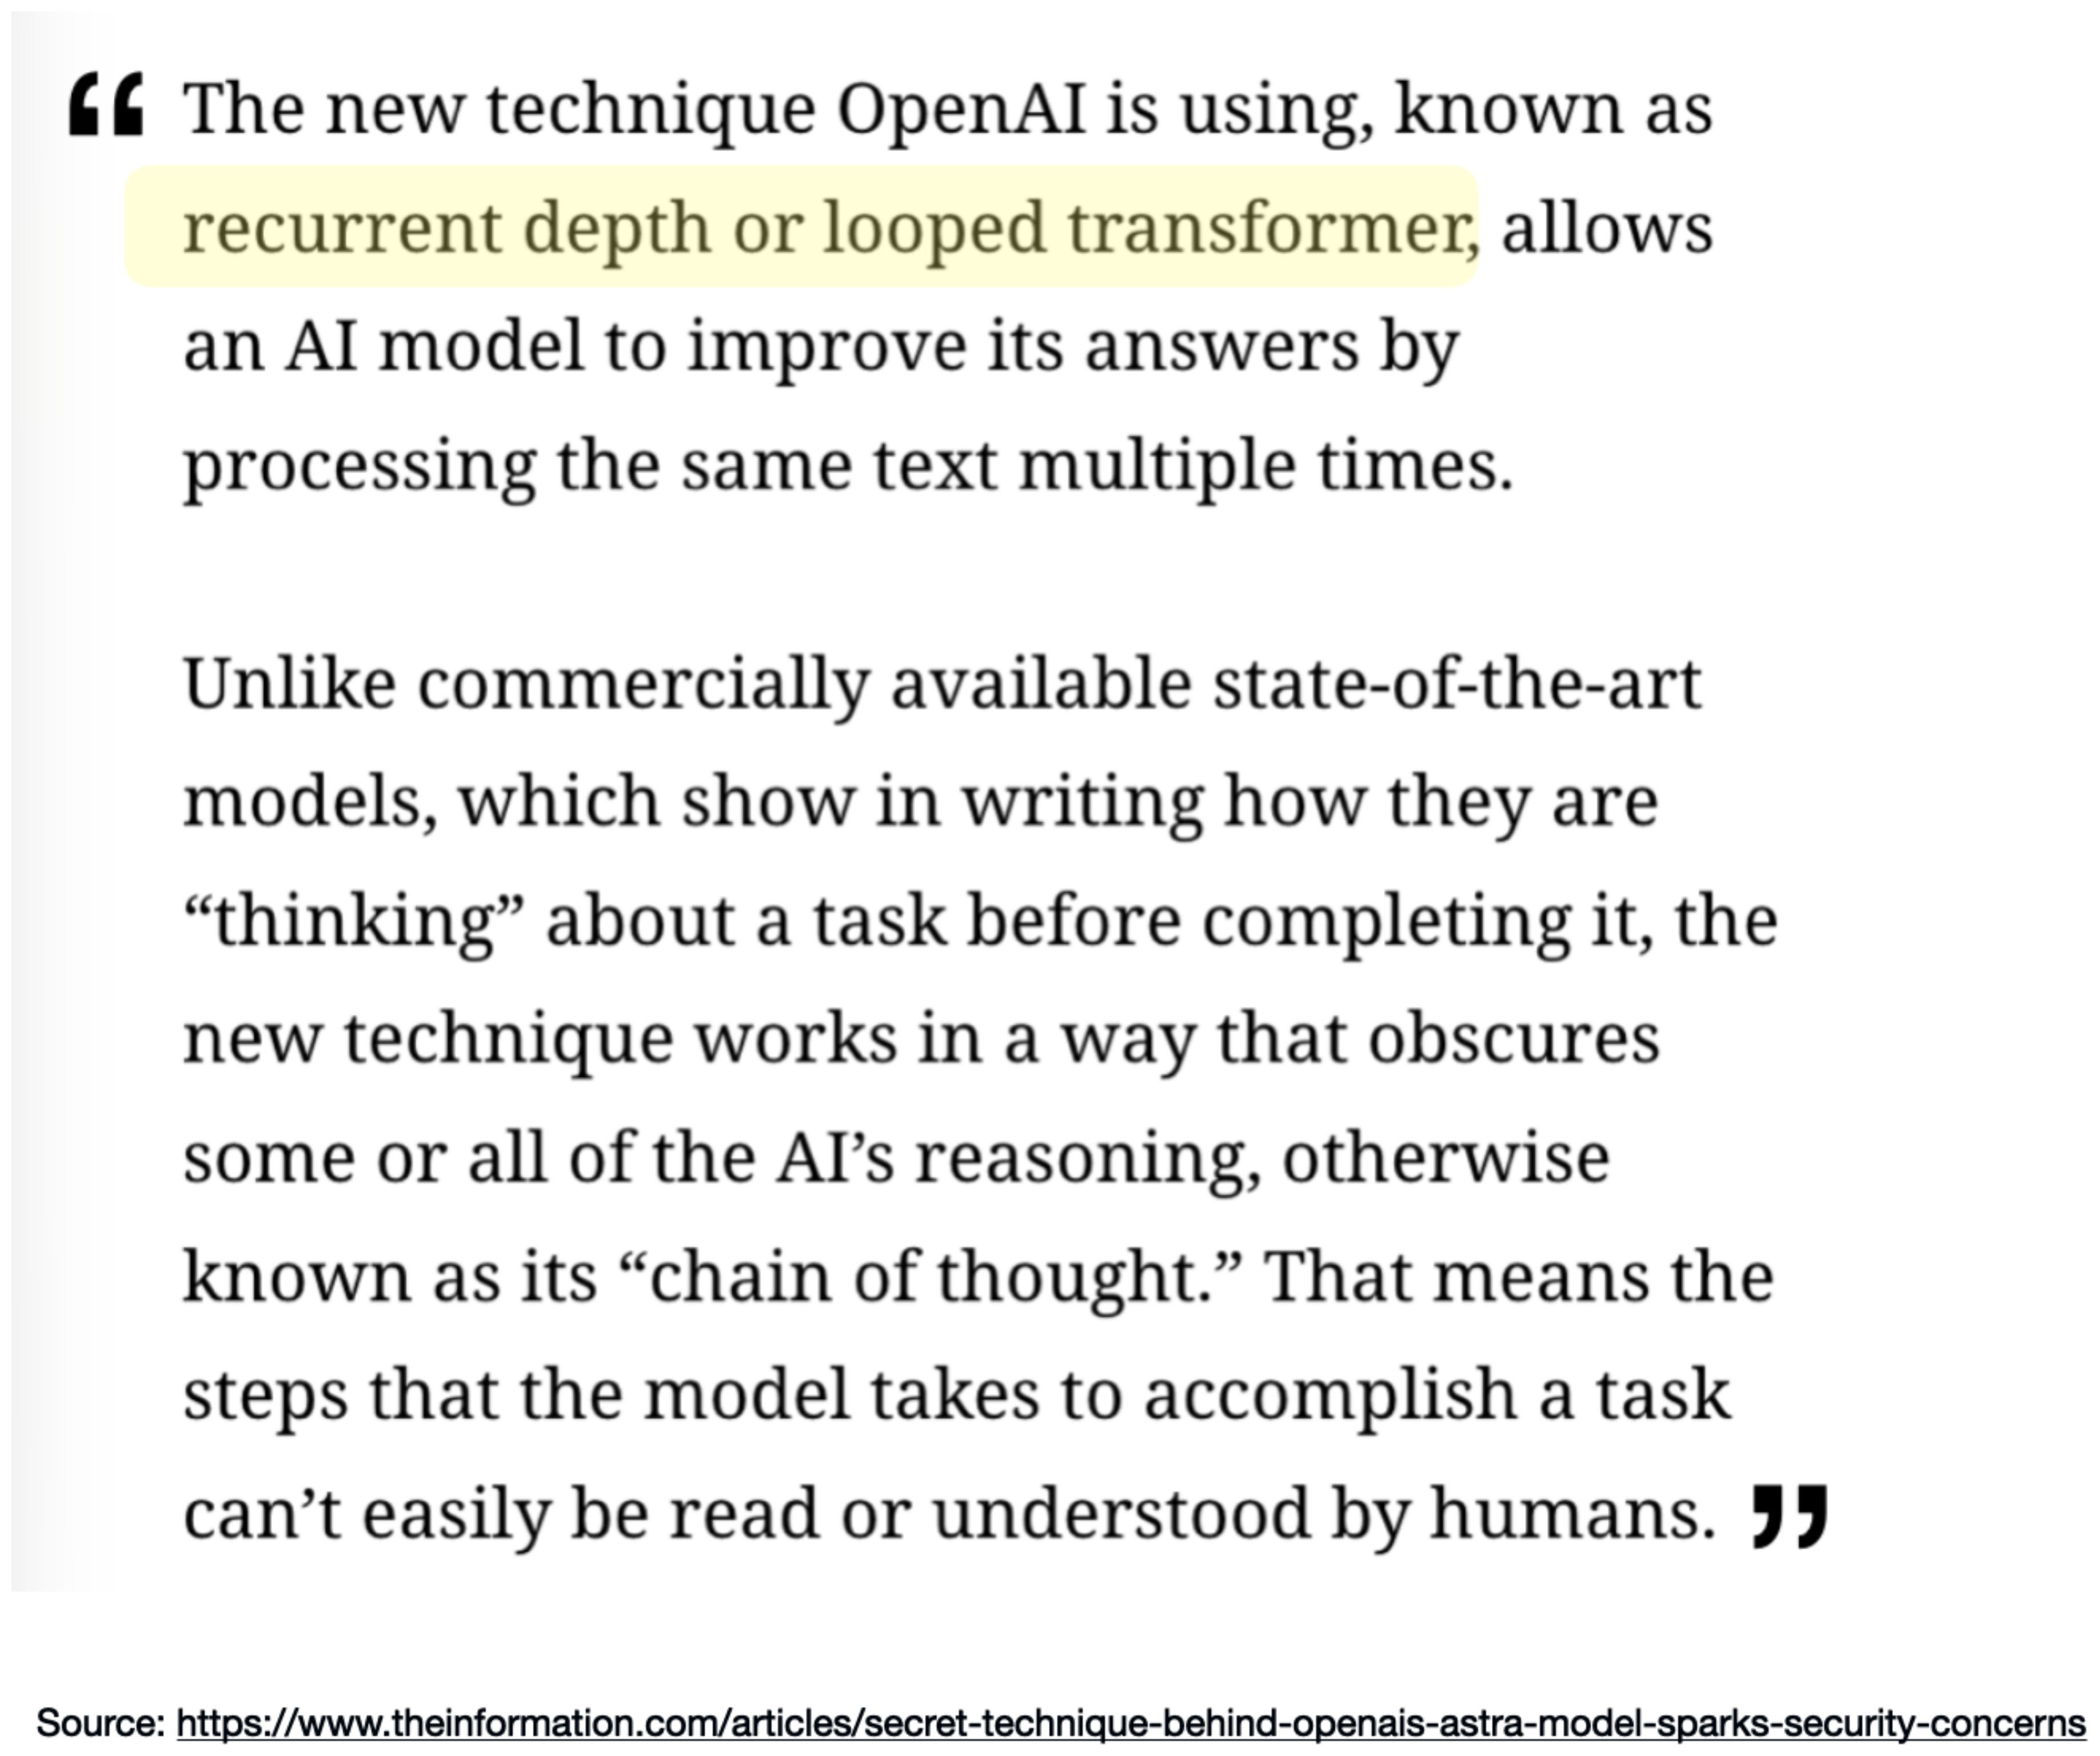
That being said, about two days before the official model, the news magazine The Information published an articlereporting that, according to some inside information, Astra is using a concept called “recurrent depth” or “looped transformers.”
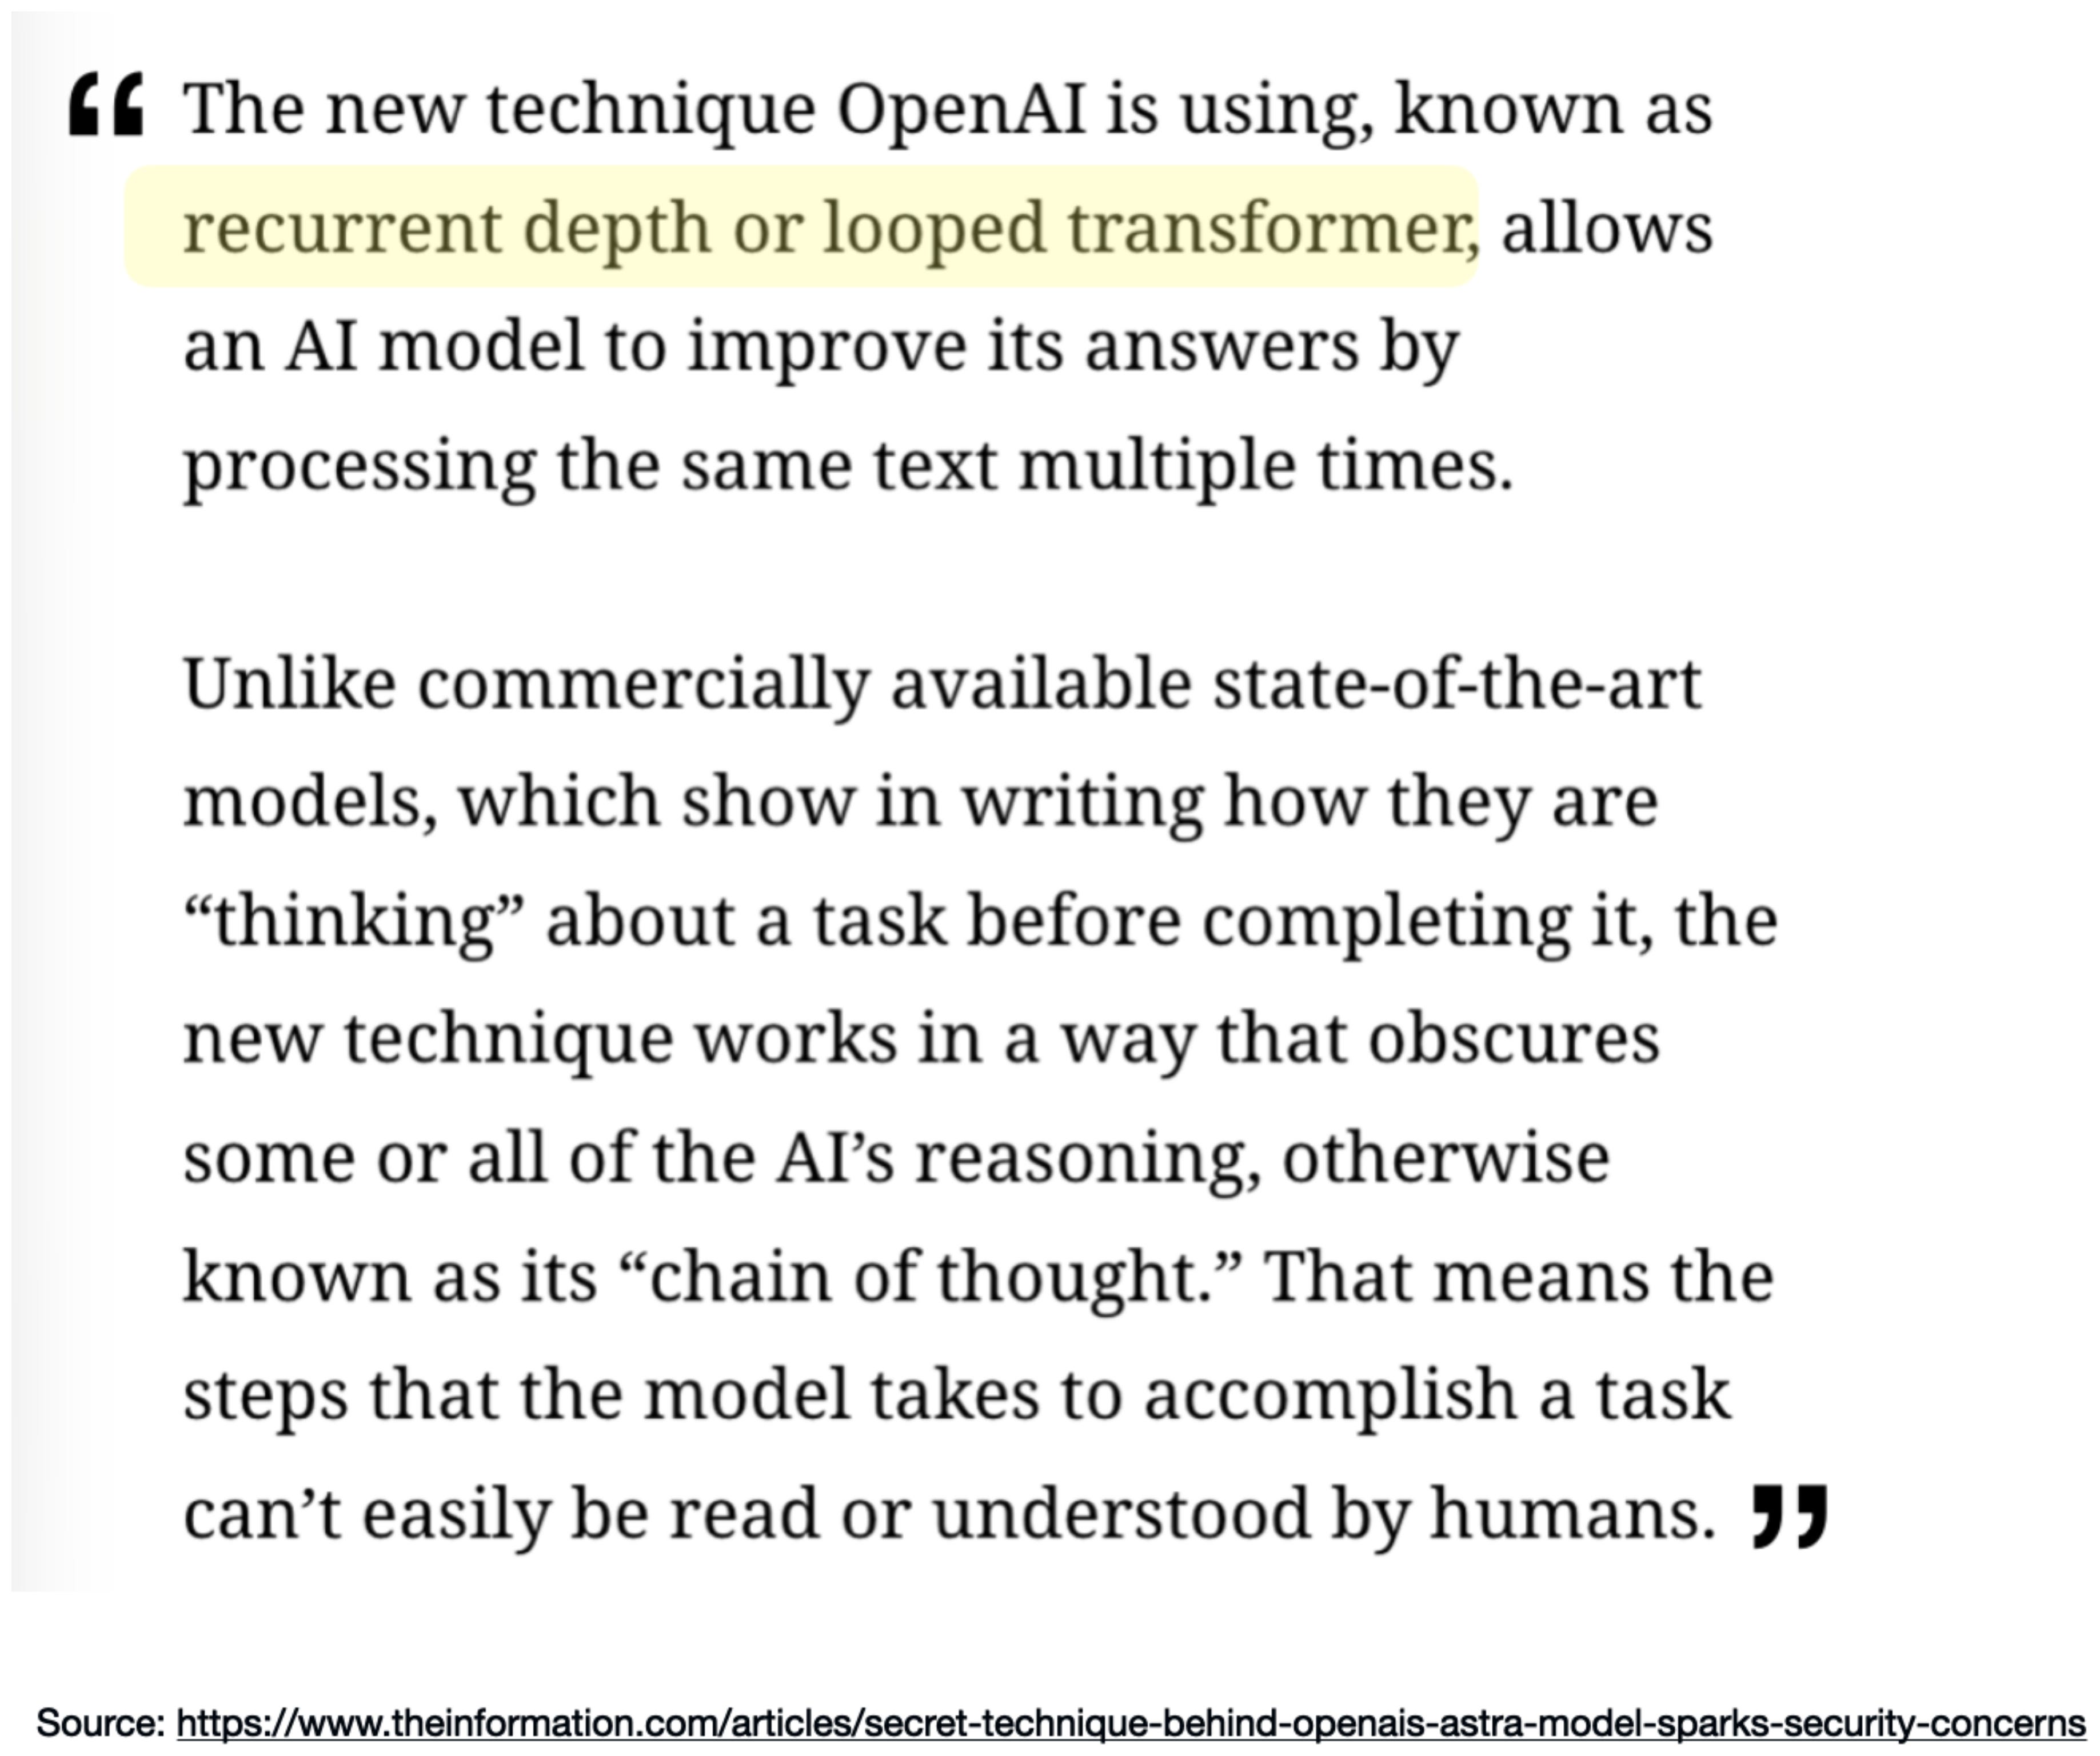
Since LLM architectures are within my area of expertise and my passion, I created a short lecture video explaining the general looped transformer mechanism and addressing the comment about hidden reasoning chains, which you can find below.
In the following subsections, I’ll first explain what looped transformers are, and I’ll revisit the comment about the hidden chains of thought later in this article.
(The looped transformer explanation may seem a bit long, but I really think that it helps with establishing a foundational understanding of the technique, which is then useful to judging the claim that it obscures the reasoning traces or chains of thought.)
2.1 Reusing transformer blocks
So, what’s a looped transformer?
A Looped Transformer is essentially an architectural tweak, with the main idea being to pass the intermediate representations through the same transformer blocks multiple times (instead of just once). Compared to just adding more blocks, the “trick” here is that the weights stay the same across these passes.
Definitions & Jargon
Throughout this article, I’ll use the following terms:
A transformer block is a unit containing attention, a feedforward module, normalization, and shortcut connections. These blocks are often called “transformer layers” in papers.
A stack is a sequence of transformer blocks.
A block application means running an input through a transformer block once.
The looped transformer is nothing new, and the basic idea already appeared in the Universal Transformers paper from 2018. But before discussing Universal Transformer, let’s start with a simpler example, Nanbeige4.2-3B, a recent open-weight LLM that came out in July and that I covered on Substack Notes and in my LLM Architecture Gallery earlier this summer.
The Nanbeige architecture, shown below, essentially looks like a regular transformer. However, notice that it has an extra (orange) arrow looping back to the beginning of the transformer stack.
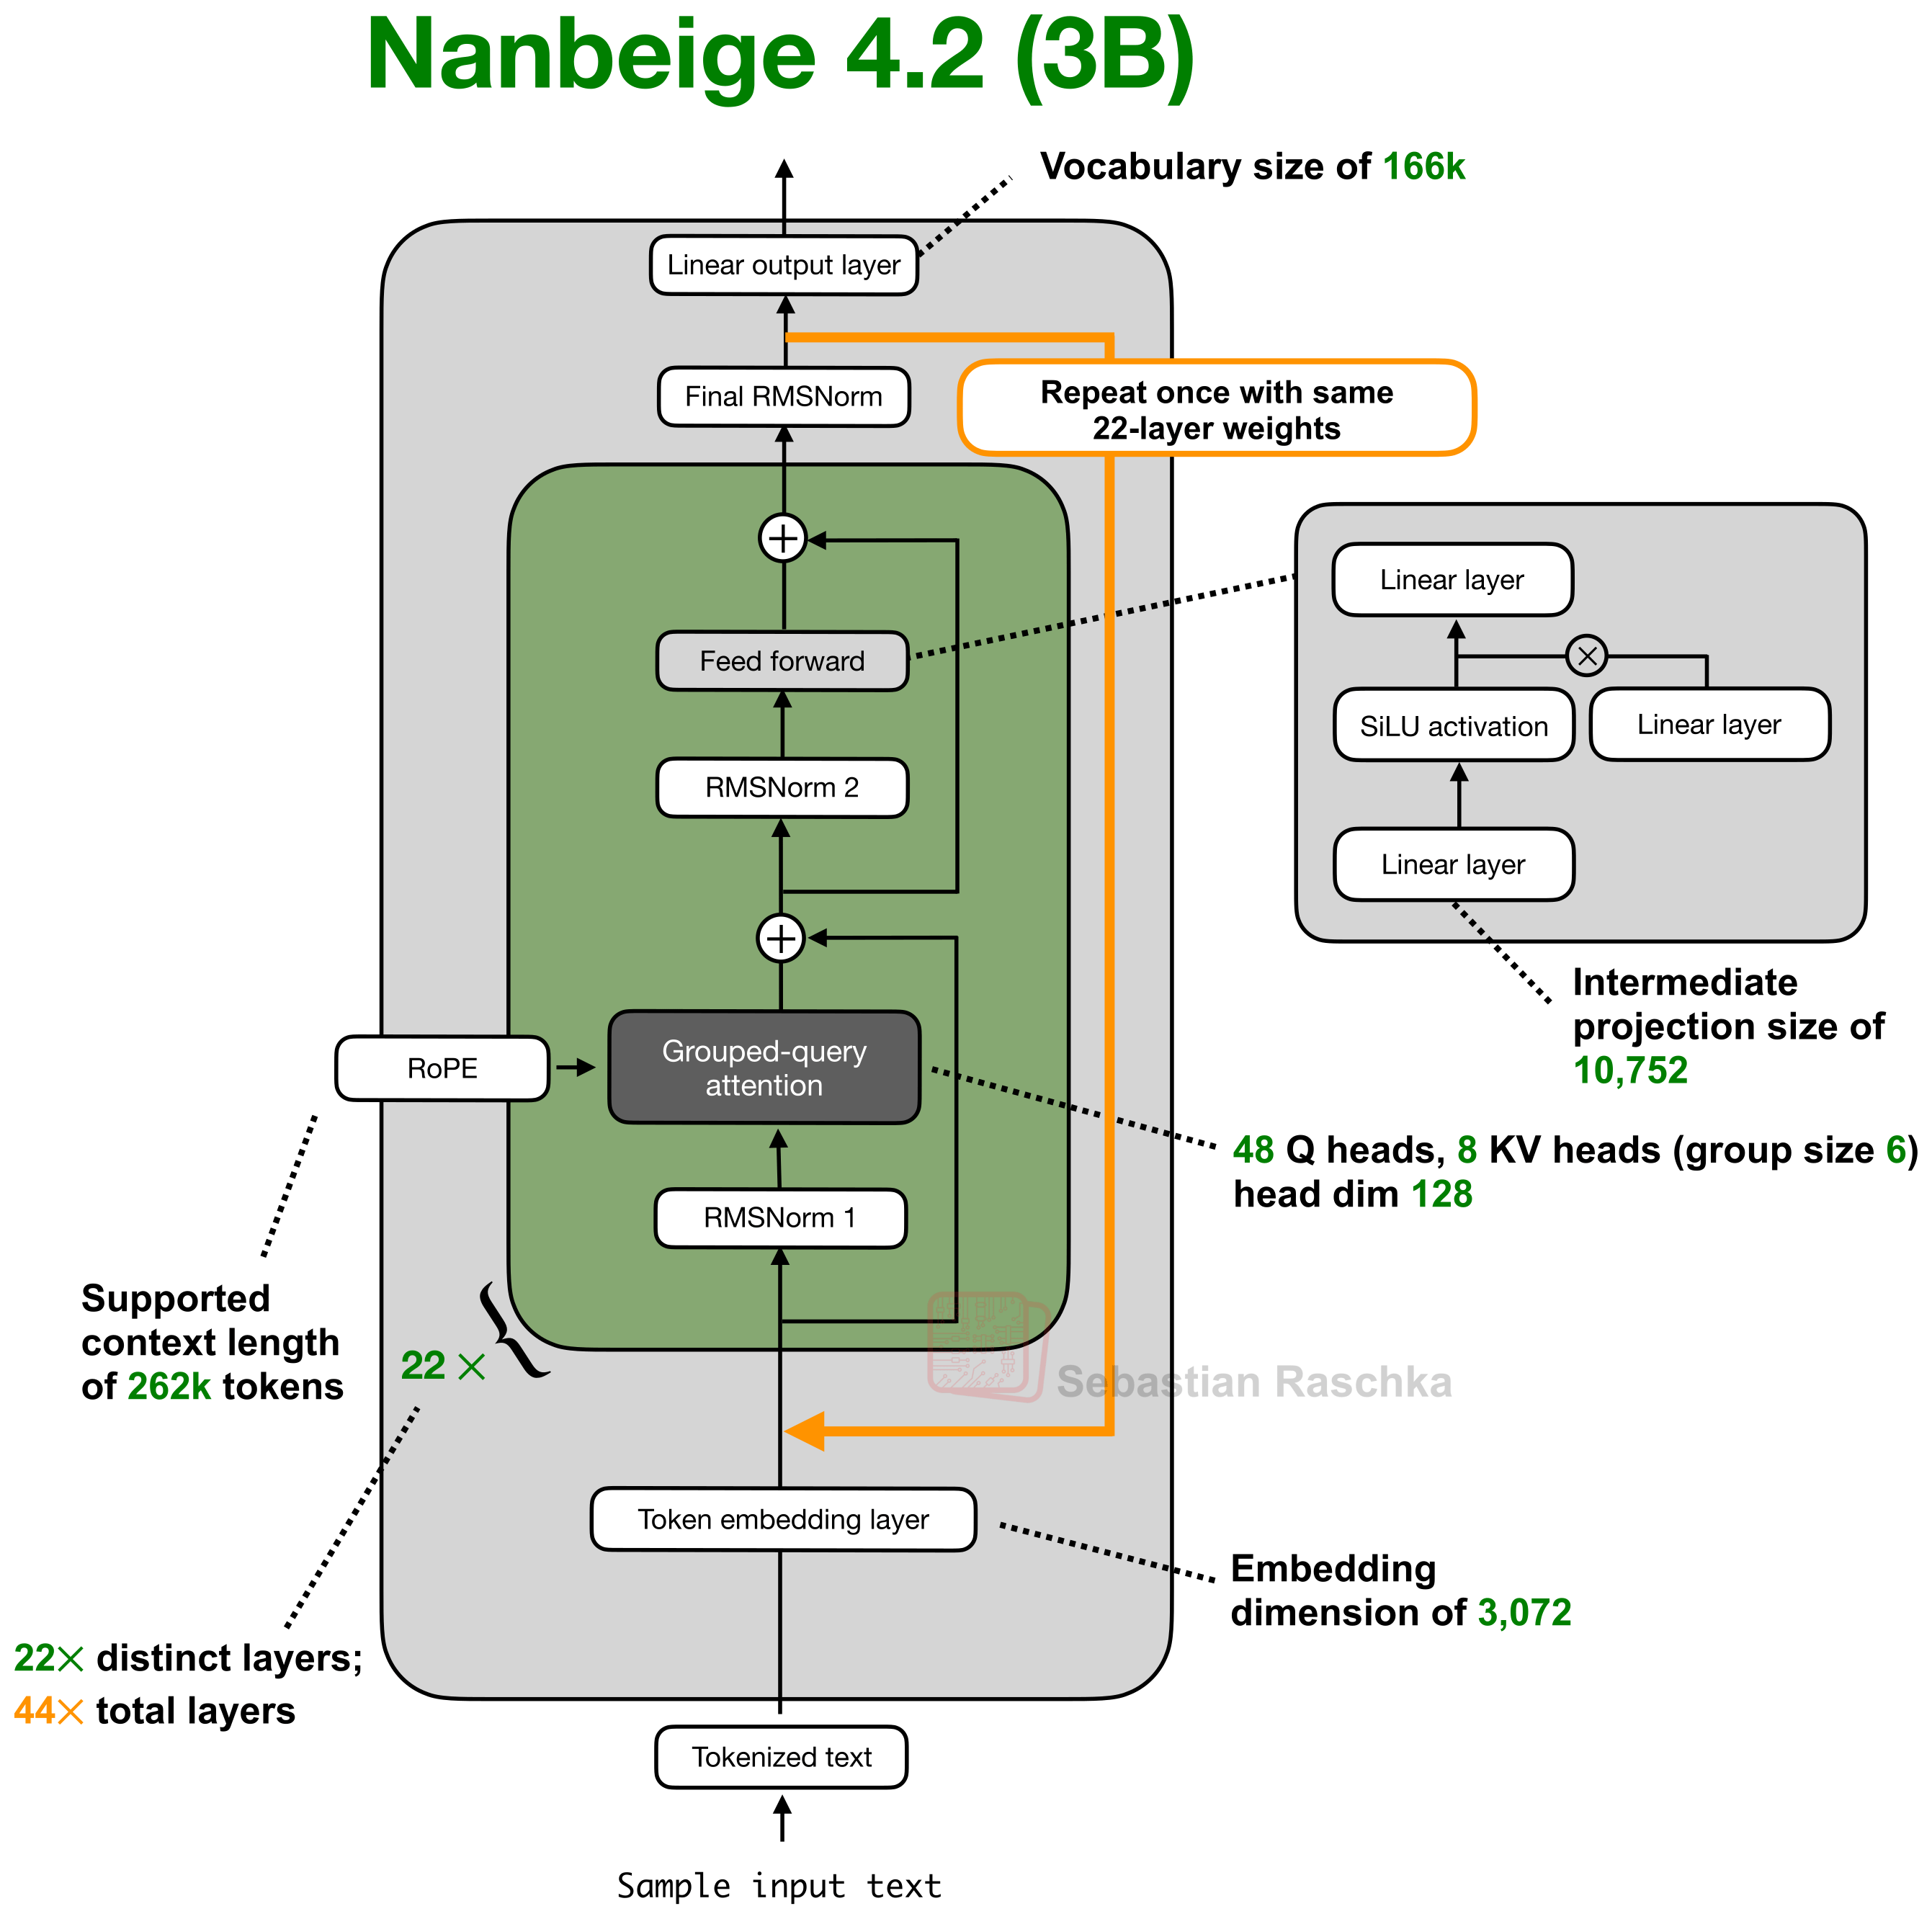
Let’s walk through this from the bottom up. First, as in any other transformer-based LLM, the input text is tokenized and converted into embedding vectors. These vectors then pass through 22 transformer blocks, and each of these 22 blocks has its own weights.
However, the looping transformer aspect here is that after the first pass, the hidden states are fed back through the same 22 blocks. So, block 1 is applied again, followed by block 2, and so on up to block 22.
If we were to unroll this computation, we would have 44 transformer block applications. However, compared to a conventional transformer with 44 distinct blocks, the second stack of 22 block applications reuses the weights from the first stack. For example, block application 23 uses the weights of block 1, block application 24 uses the weights of block 2, and so on.
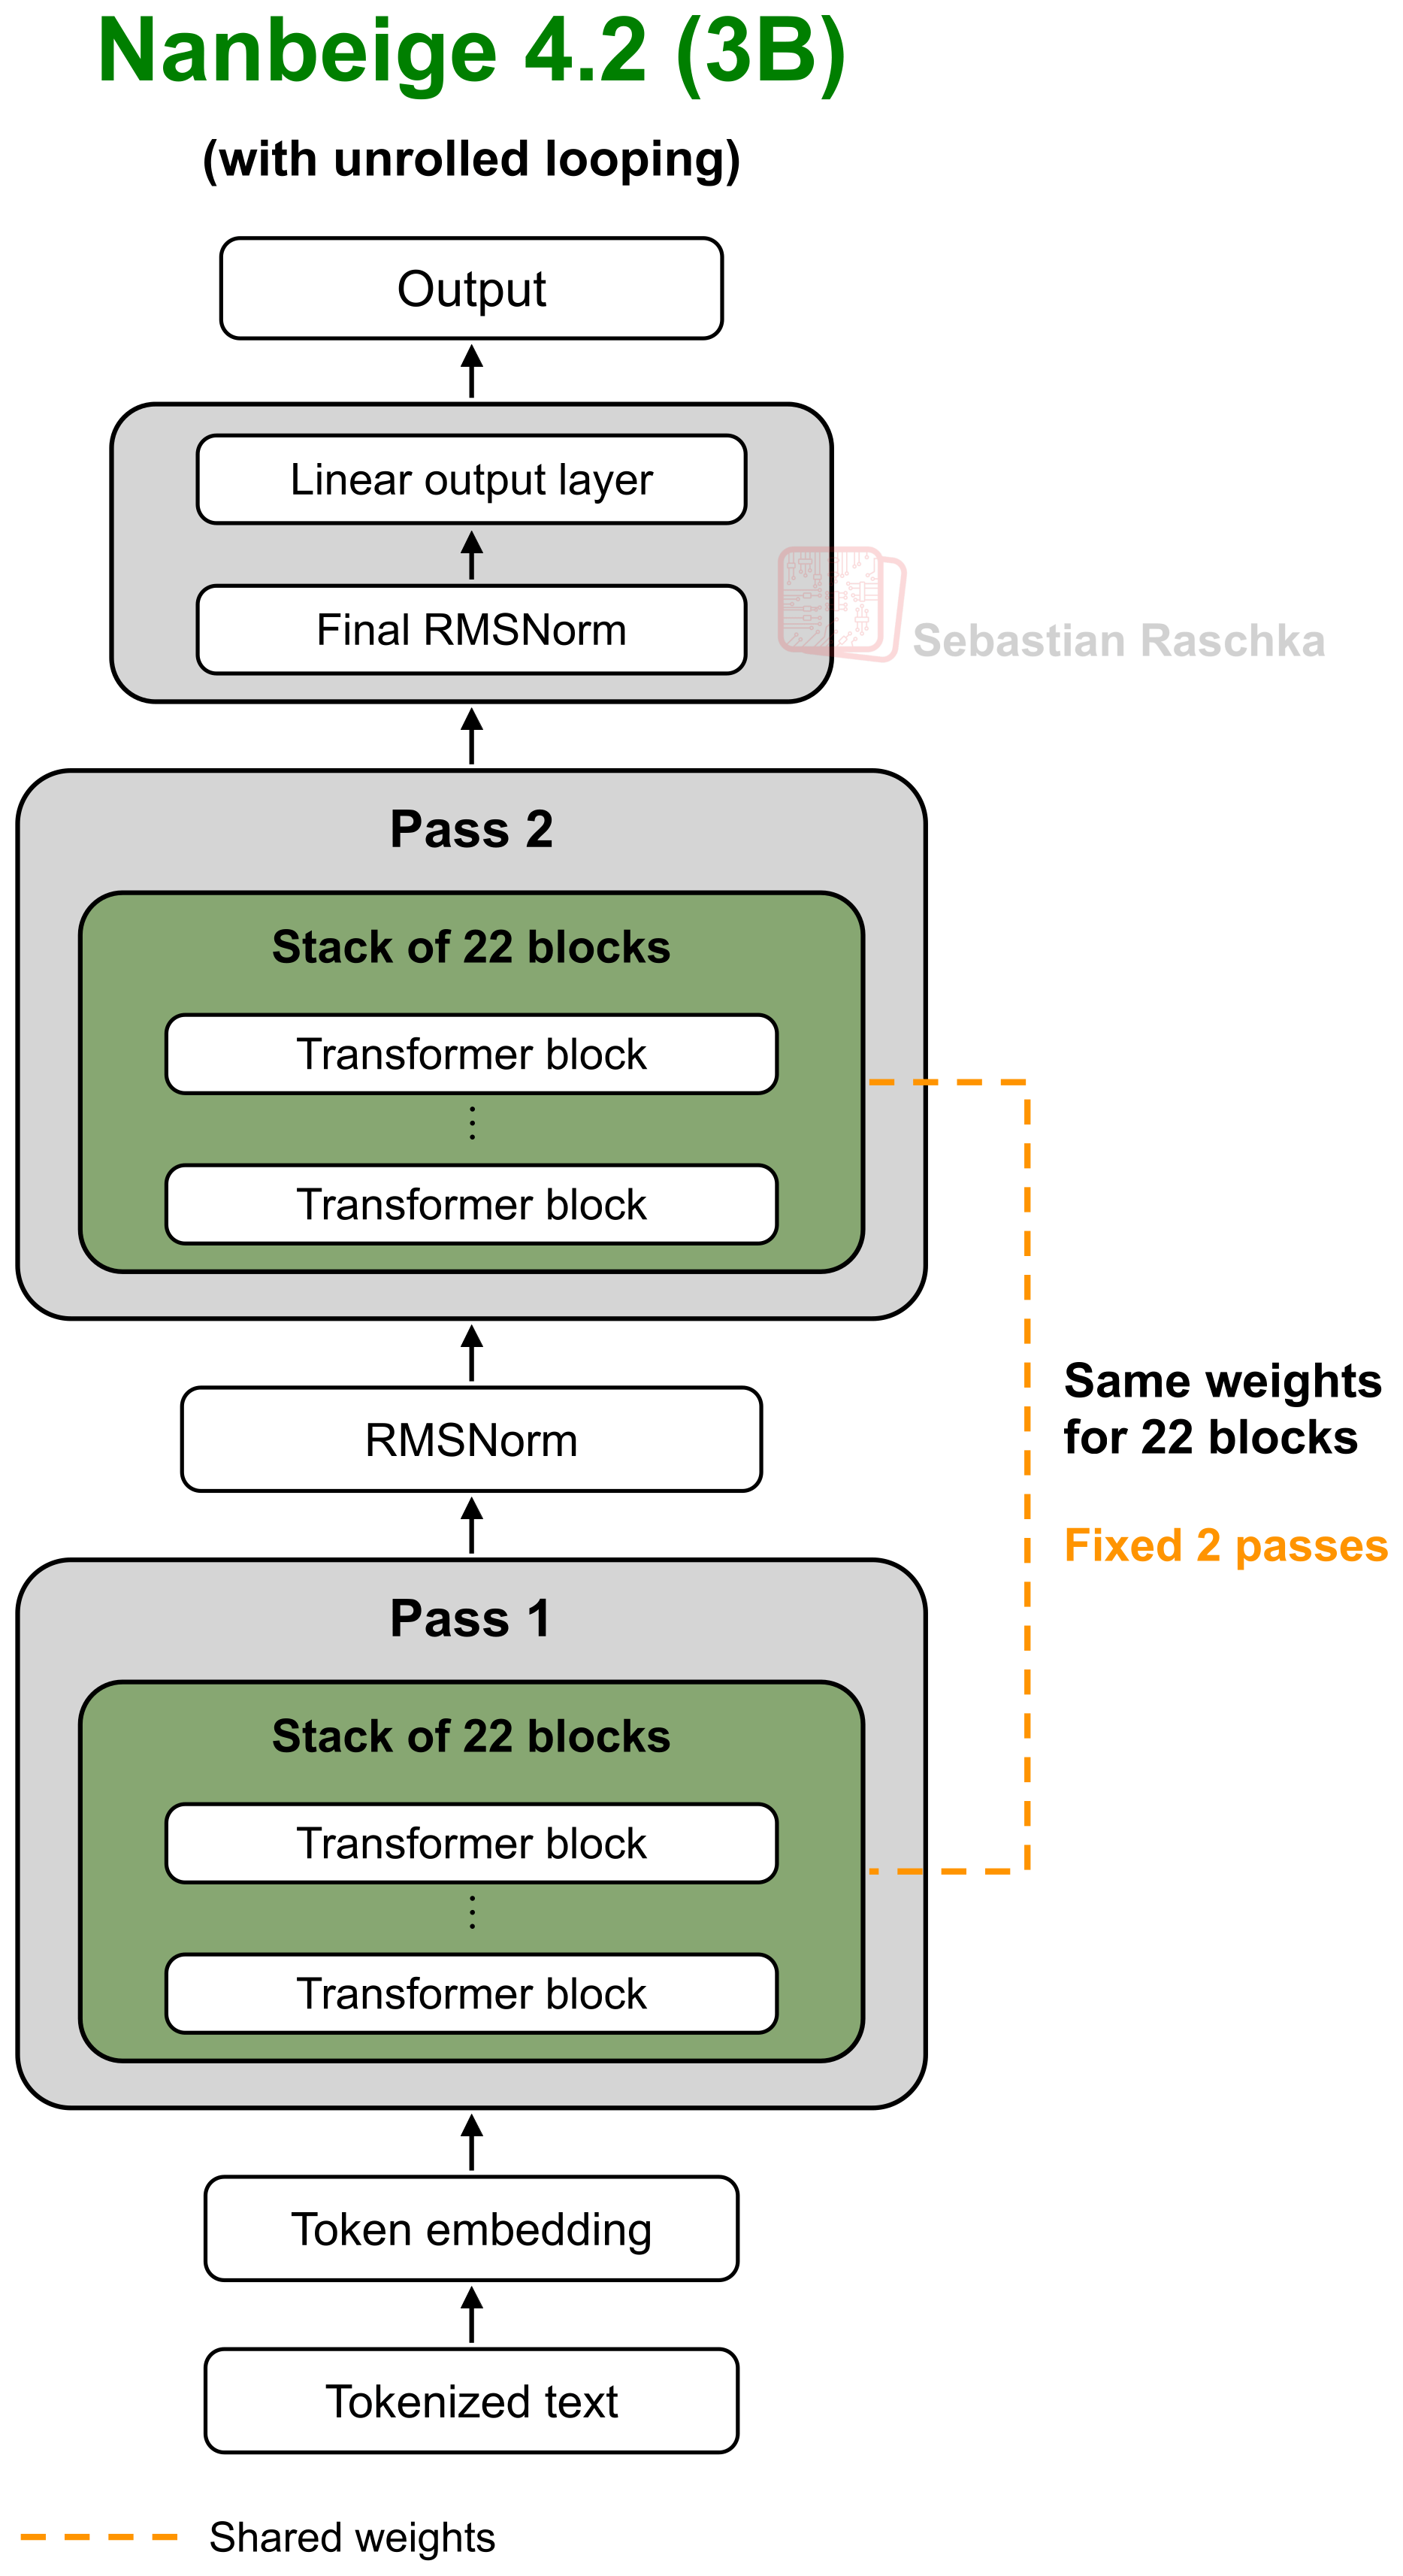
So, the whole idea here is that we increase the effective depth from 22 to 44 block applications without adding another set of transformer weights.
By the way, why 2 rounds, not 3, 4, or more? There are not many details in the Nanbeige paper, but they say that this was essentially the most efficient setup. Increasing the loops from 2 to 3 can increase modeling performance, but the extra computational cost wasn’t worth it.
2.2 Looping costs
So, why would we do this looping in general? This is essentially an alternative to just making the model bigger by adding more transformer blocks.
So, for instance, a model that uses 22 transformer blocks twice has roughly half as many (transformer-block) parameters compared to a model with 44 conventional blocks.
This then reduces the memory needed to store the weights. As a side note, note that the embedding and output layers, which are usually large and make up a substantial portion of the total, are separate from this comparison. (In the case of Nanbeige 4.2 3B, the embedding and output layers make up ~25% of the total 3B parameters; with weight sharing between those two, we could reduce that to 12.5%.)
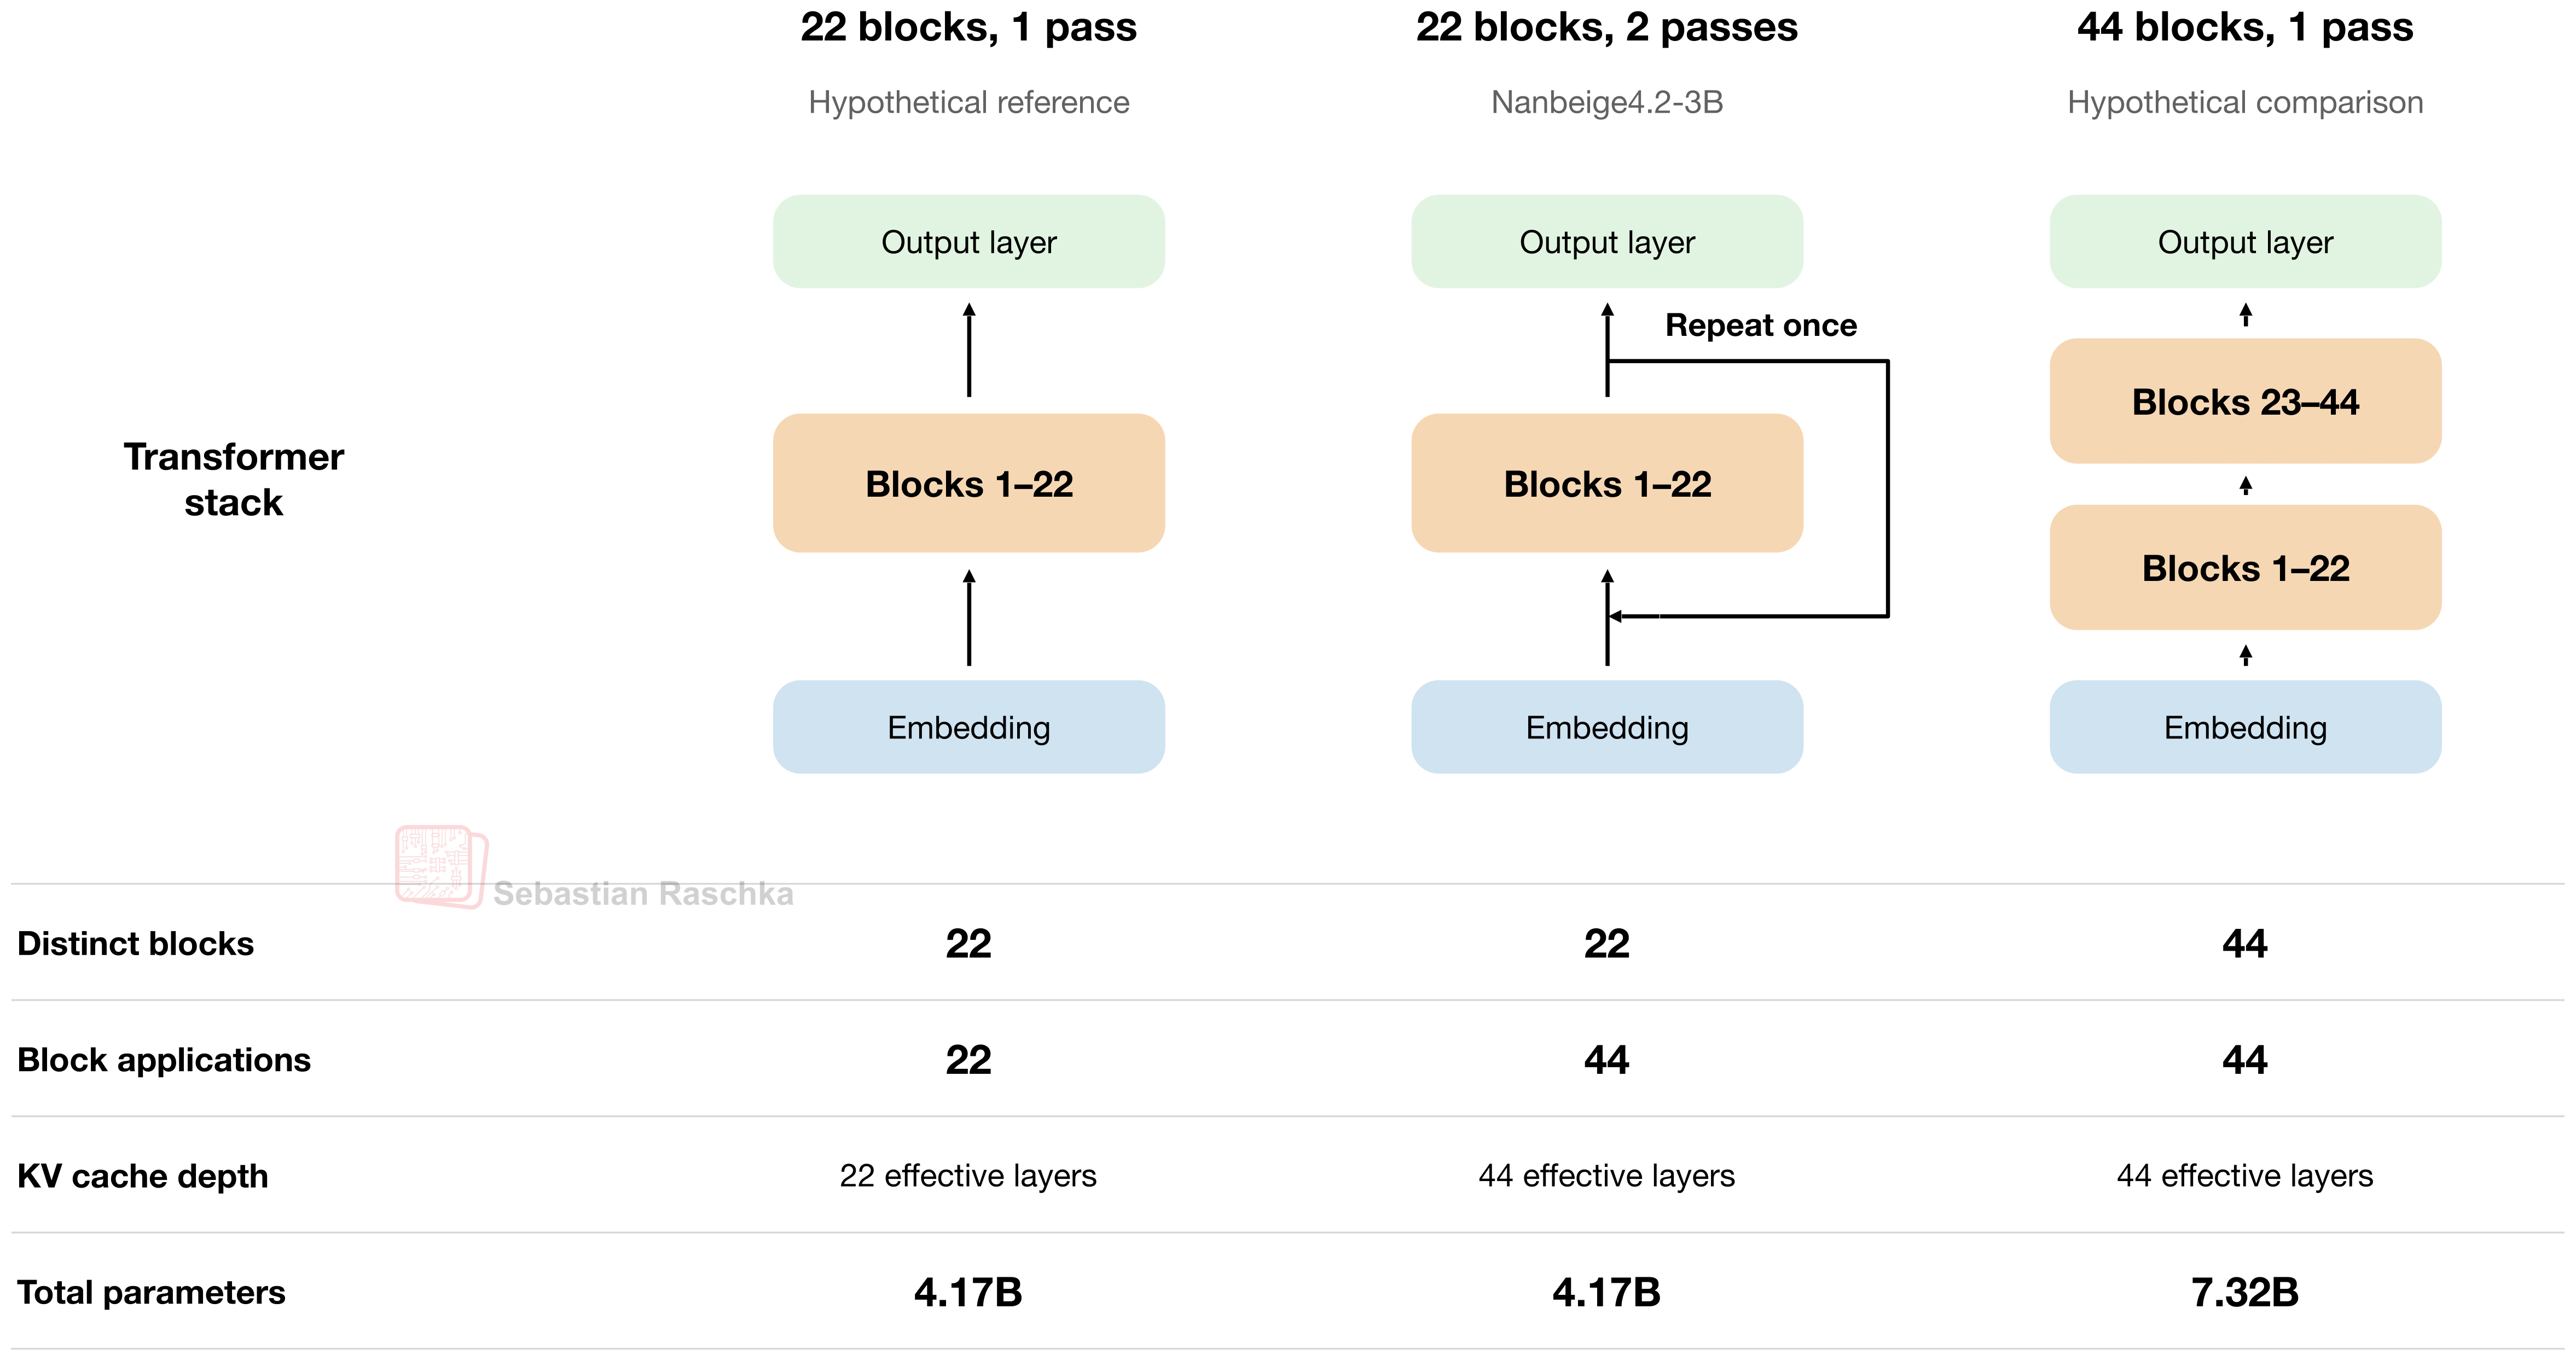
Of course, reusing the same blocks in a loop still requires computation. More precisely, we pass the intermediate inputs through 44 block applications during the forward pass. And, during training, gradients flow backward through both repetitions of the shared stack. So, compared to using the 22 blocks only once, this adds substantial work. Actually, it’s similarly expensive as having 44 distinct blocks (except the optimizer has fewer distinct parameters to update; backprop still runs through all 44 block applications).
There is also the KV cache, which stores the attention keys and values of previous tokens for reuse in conventional and looped transformers in each next-token generation step. By the way, I have a standalone article on KV caching here if useful:
But back to the topic. Even though there is weight-sharing in looped transformers, the intermediate states that enter a block are different on the second pass. Consequently, in KV caching, the resulting keys and values are also different between these two transformer stacks (just like in the no-looping case). So, there are no KV cache-related savings either.
To make this more concrete, for example, consider block applications 1 and 23, which both use block 1 in the looped transformer setup. But each application still needs its own KV cache entries. So, since we have to keep separate caches for both passes, the repeated stack of 22 blocks has the same KV cache requirements as a conventional transformer with 44 distinct blocks.
Interestingly, the Nanbeige researchers reported in the paper that they tried sharing the KV cache between passes. This, of course, halved the KV cache size, but the model performed worse than the version with separate caches (which is the version they released).
Just to complete the Nanbeige discussion before moving on and looking at some other looped transformer designs, their technical report also discusses two other choices or trade-offs.
Training the looped architecture from scratch worked better than converting an already pre-trained transformer through upcycling.
And two passes gave their preferred trade-off, as mentioned in the previous section. More passes brought only small additional gains while slowing training and making optimization less stable.
So, the number of passes is another architectural choice we have to make. As mentioned before, in Nanbeige, this is fixed at two. But we can also make it depend on the token, as we will see next.
2.3 Universal Transformers and flexible loop counts
Now, let’s come back to Universal Transformers. In Nanbeige, we apply a stack of 22 transformer blocks twice. In the Universal Transformer paper from 2018, we repeatedly apply the same transformer block instead of repeating a stack of transformer blocks. The main idea is similar, though.
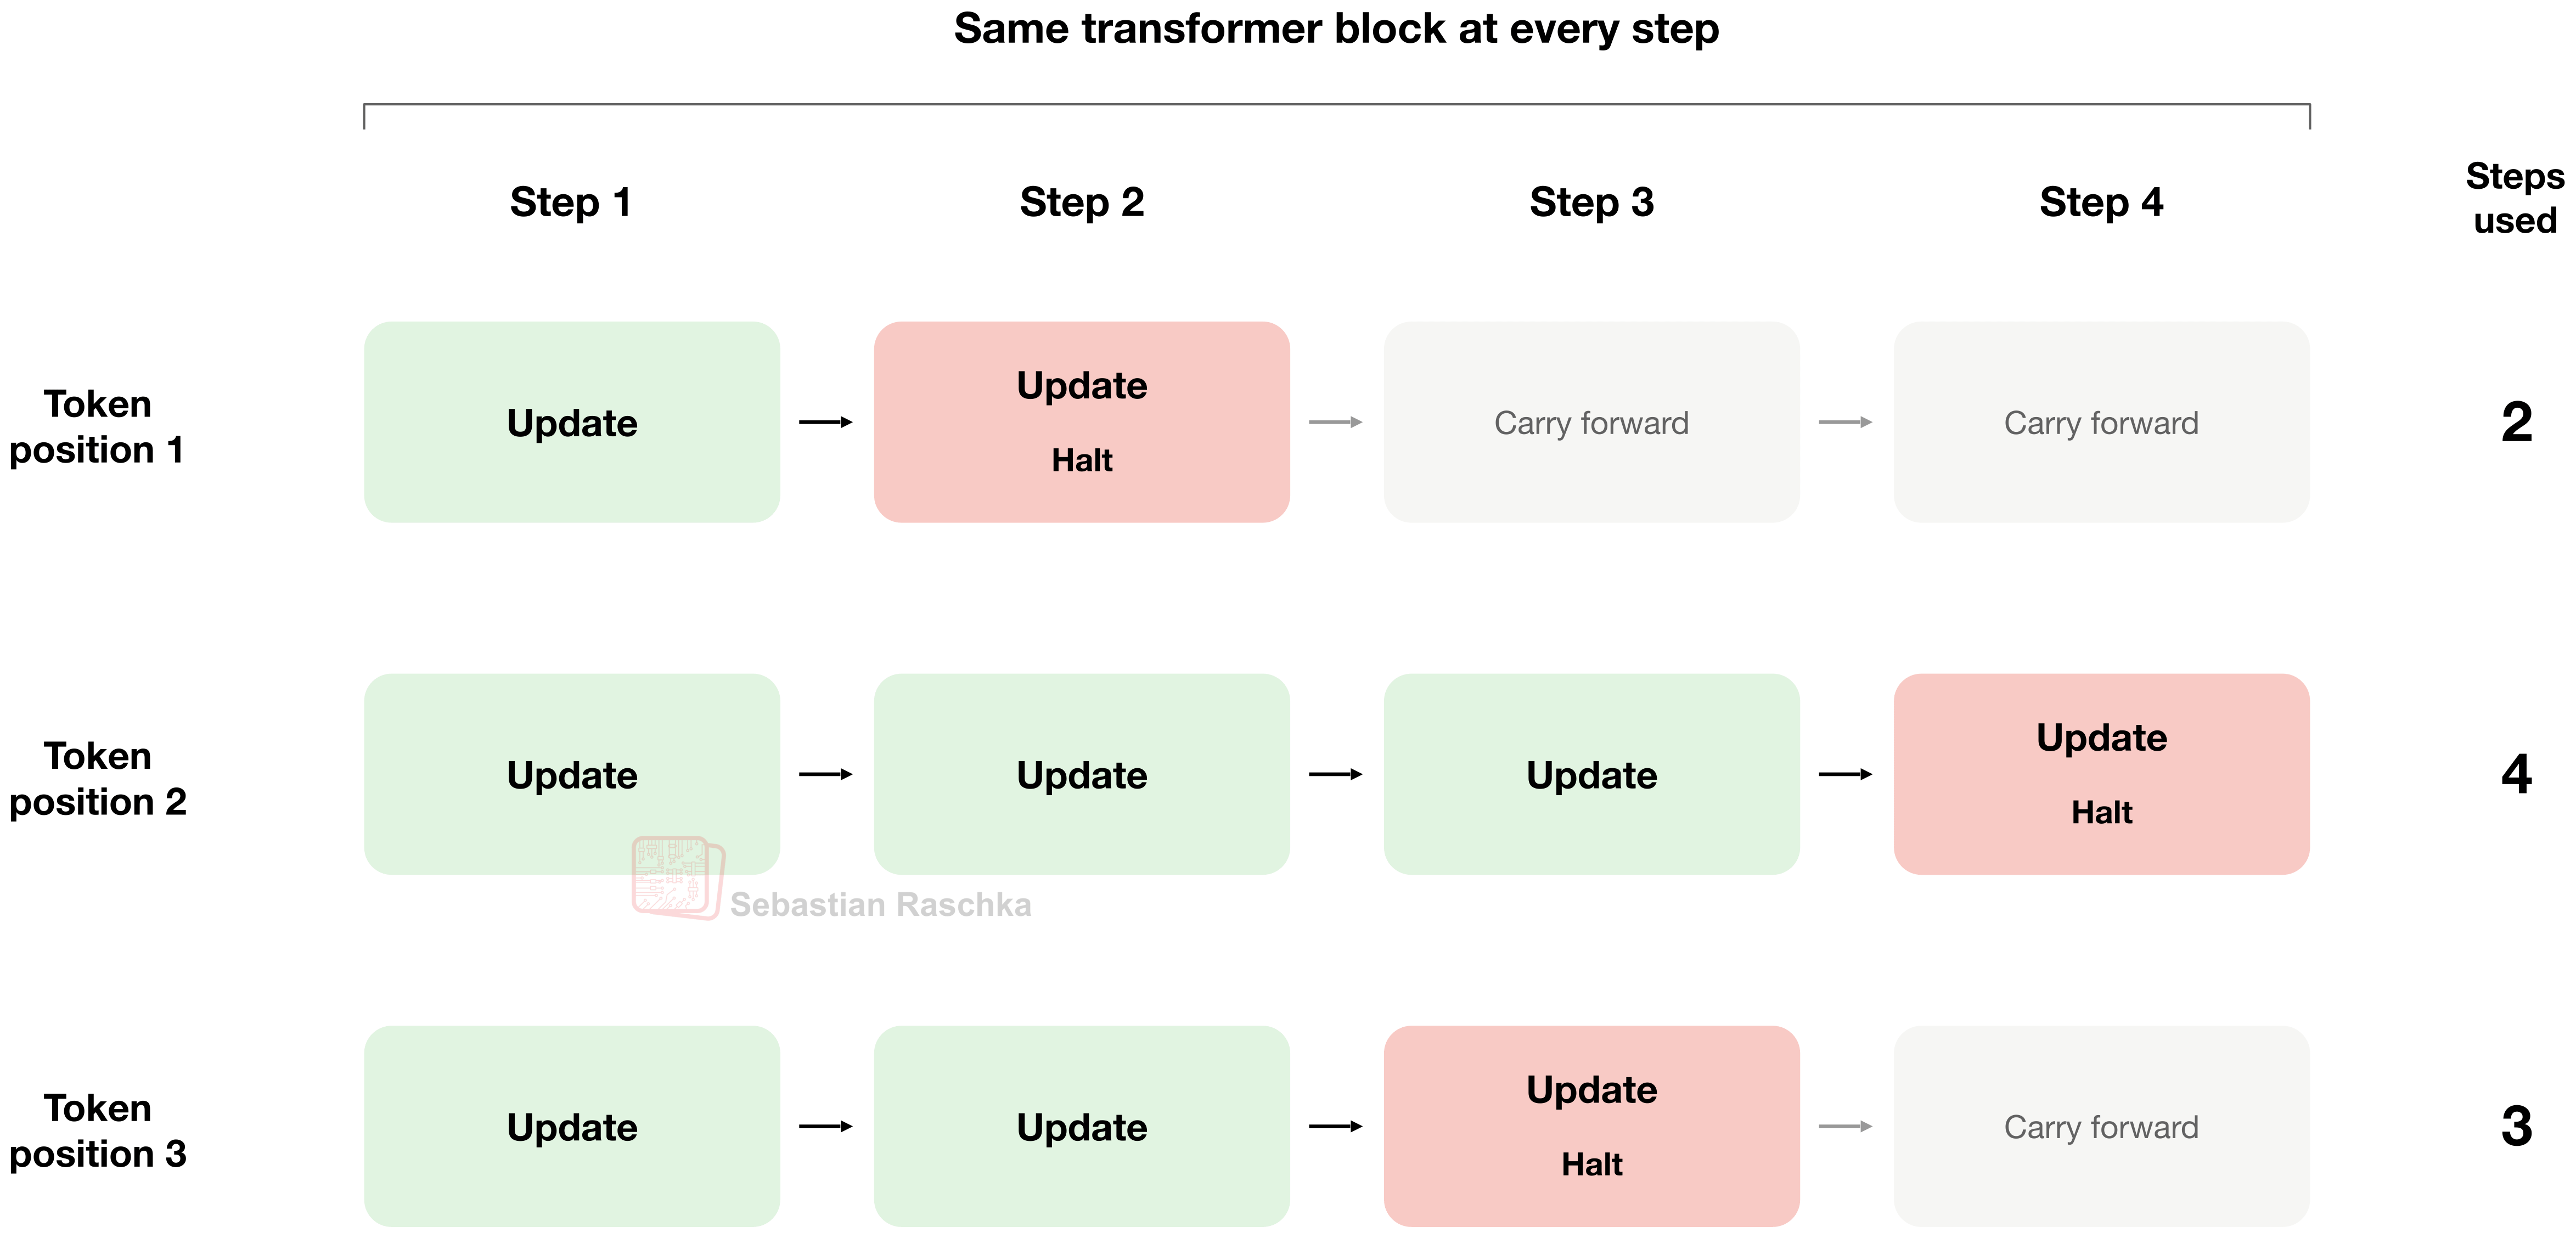
Also, the number of steps can be fixed, but the paper also explores adaptive halting. For example, a token at a particular position may only go through one or two loops. Another may go through three or four loops, and so on. This gives the model flexibility to allocate the compute to those tokens that benefit from extra computation.
How is the looping number decided? Here, the model uses a small, trained function that outputs a so-called halting probability for each position at each step. It adds up these probabilities over these successive loops and then stops looping at a given position once the sum exceeds a threshold value. In addition, a maximum loop count also limits the computation just in case.
Another example of a looped transformer is ByteDance’s Ouro, which I also covered in my LLM Architecture Gallery. For instance, Ouro-Thinking 2.6B applies the same stack of 48 transformer blocks four times. That’s 192 block applications while storing weights for 48 distinct blocks. Basically, that’s a more extreme case than Nanbeige. Additionally, a learned exit gate assigns probabilities to the different exits, and a threshold on the cumulative probability determines which pass supplies the output. So, it’s also borrowing the adaptive halting idea from Universal Transformer, which Nanbeige didn’t use. (However, there is a practical caveat here. The released Hugging Face implementation computes all configured passes before selecting an output, so it seems like the number of loops is effectively hard-coded to 4).
2.4 Routing flexible loop counts
Another approach is Mixture-of-Recursions, a paper from 2025 that is essentially a more sophisticated version of the Universal Transformer discussed earlier. Similar to the Universal Transformer, individual tokens pass the transformer blocks one or more times as illustrated in the figure below. However, the innovation is how this looping number is determined on a per-token basis.
In the following figure from the paper, the looped (repeated) stack is called a recursion block here. This contains several transformer blocks, and it sits between separate first and last transformer blocks (labeled Layer 0 and Layer L-1).
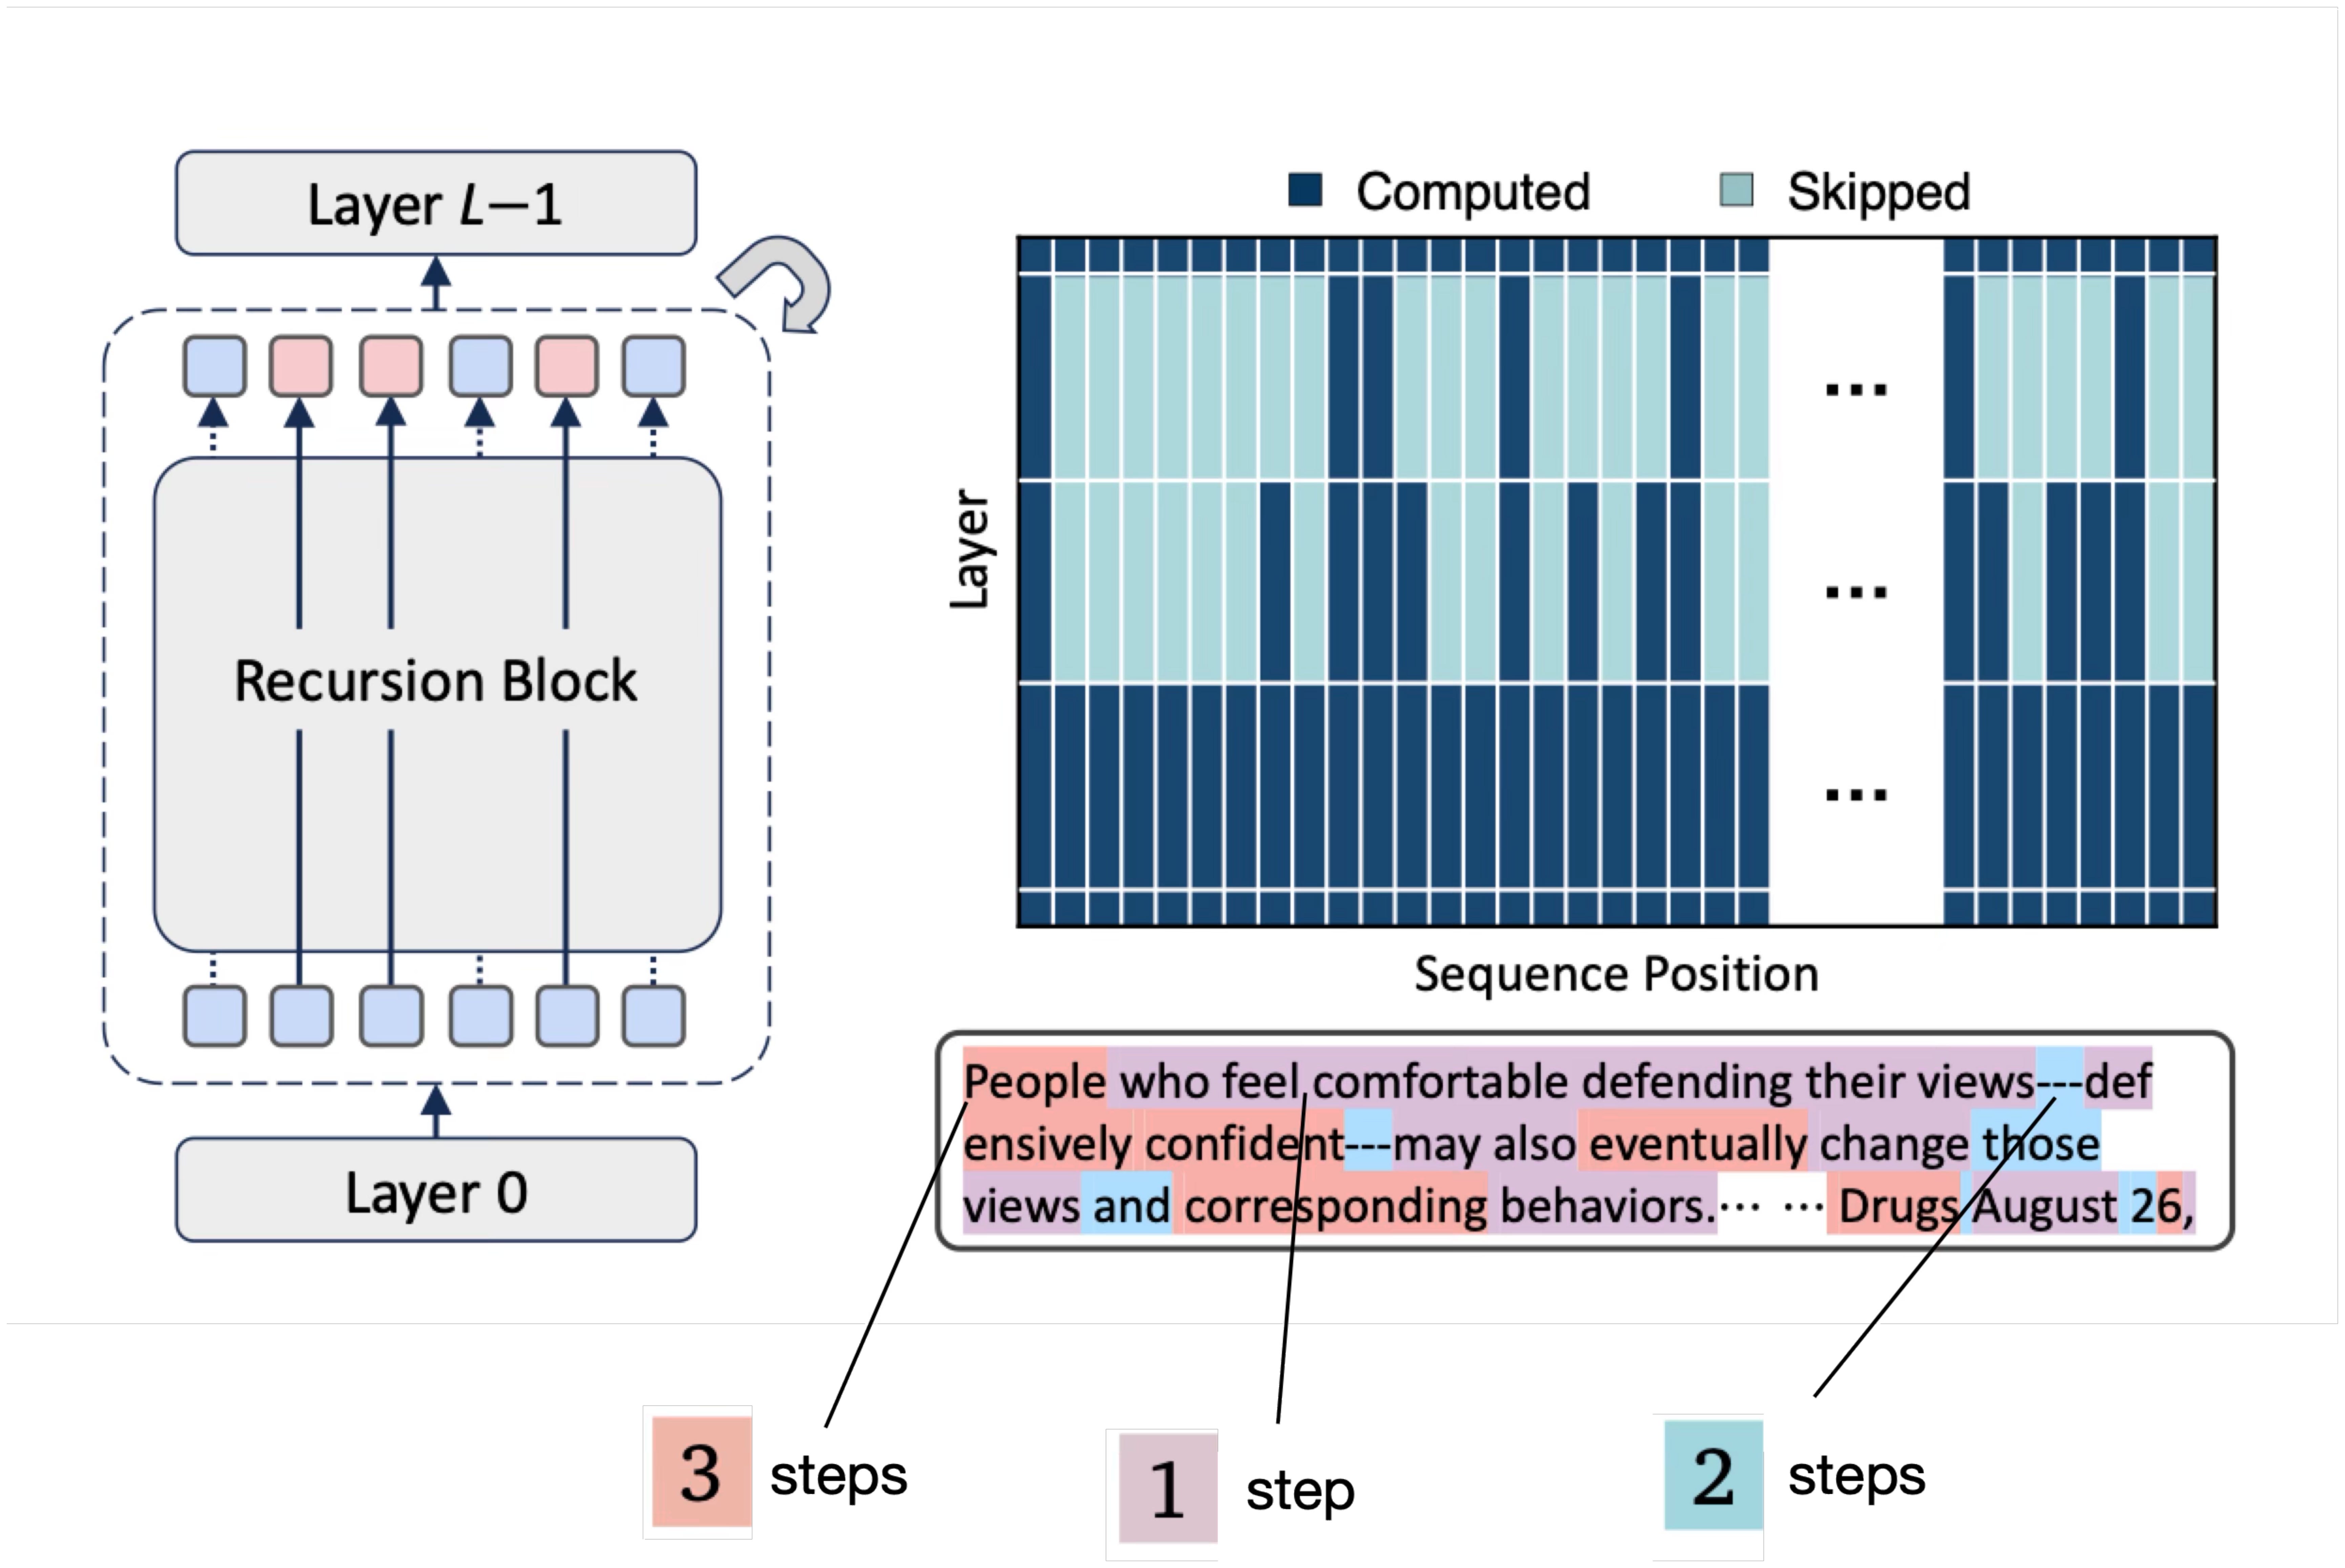
How does the model decide how many times a token should go through the recursion block? In the previously discussed Universal Transformer, it’s based on a learned halting probability at each step. This Mixture-of-Recursion approach here uses a small, learned router. This is similar to the routing idea in a mixture-of-experts model, except that here the routing decision determines how many times to apply the shared stack.
The router operates on a token’s hidden representation, which also contains information about its context. So, we shouldn’t think of this as assigning every occurrence of a particular token the same number of passes (i.e., the word “People” in the figure above doesn’t always go through a loop of 3). The decision can change depending on where that word appears and what came before it.
Now, how does the routing work exactly? The paper explores two ways to make this routing decision, as illustrated below.
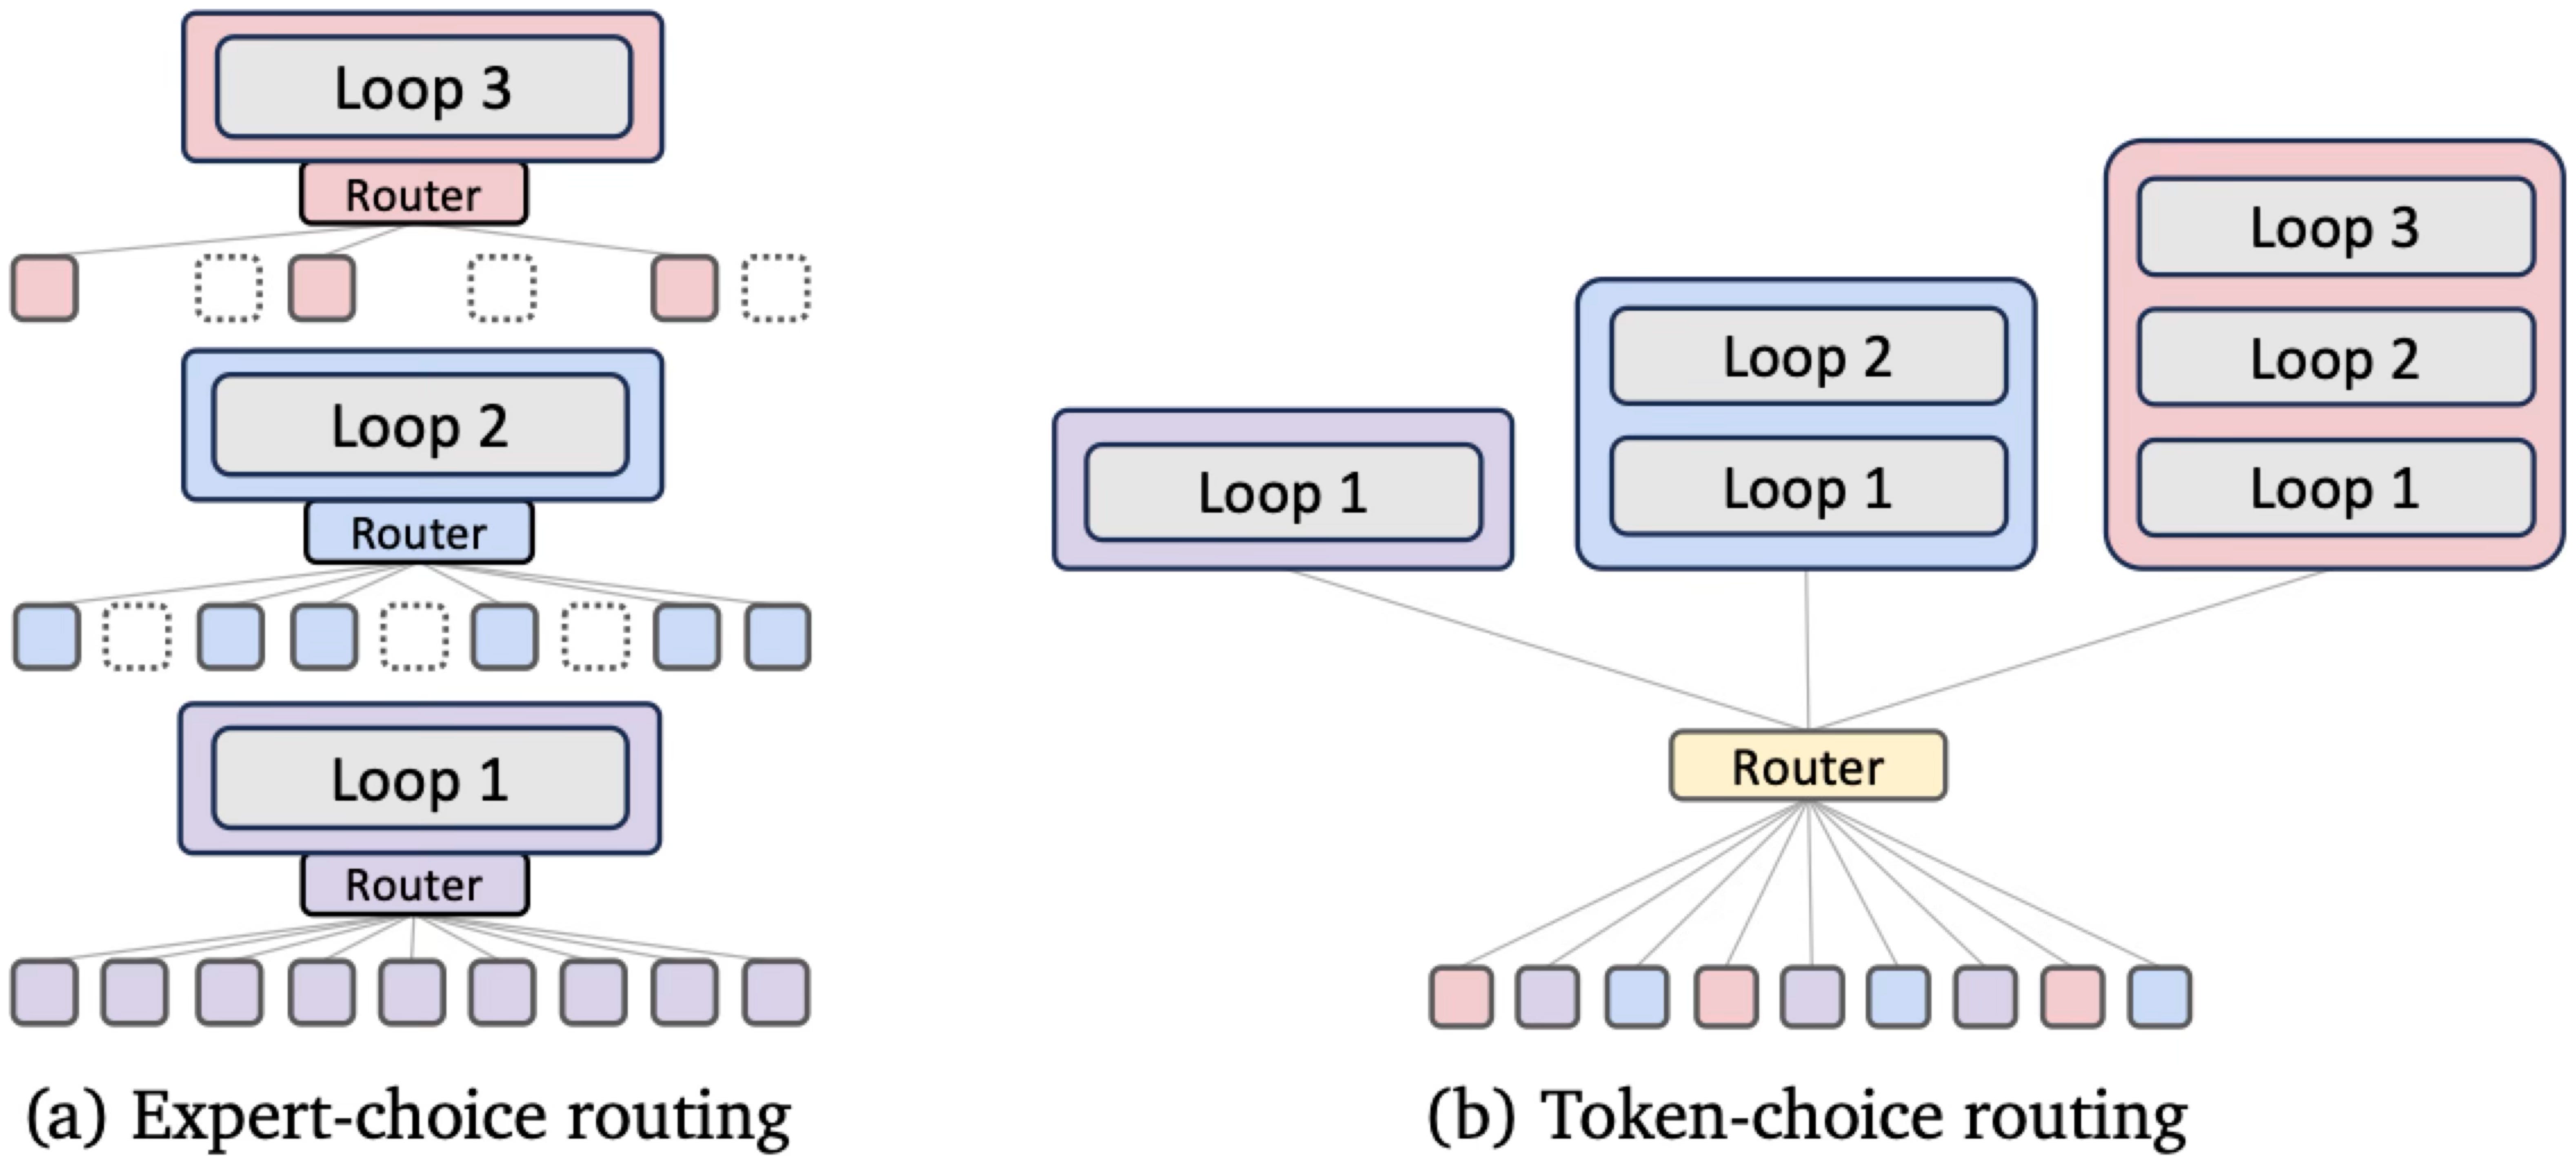
In expert-choice routing, which is shown in the left subpanel in the figure above, each recursion step selects which tokens it will process. Tokens that exit are excluded from later steps. In token-choice routing, shown on the right, the router makes one decision at the beginning, assigning each token to a path with one, two, or three passes.
In both cases, the transformer weights are reused across passes, similar to Nanbeige, etc. But the additional flexibility comes from choosing how much computation each token receives. The model and its routers are trained together, so the model learns to work with these different paths during training.
2.5 How well does this work?
The plot from the Mixture-of-Recursions paper below compares a regular transformer (Vanilla), a transformer with fixed recursion (Recursive), and Mixture-of-Recursions (MoR) for different model sizes and compute budgets (x-axis).
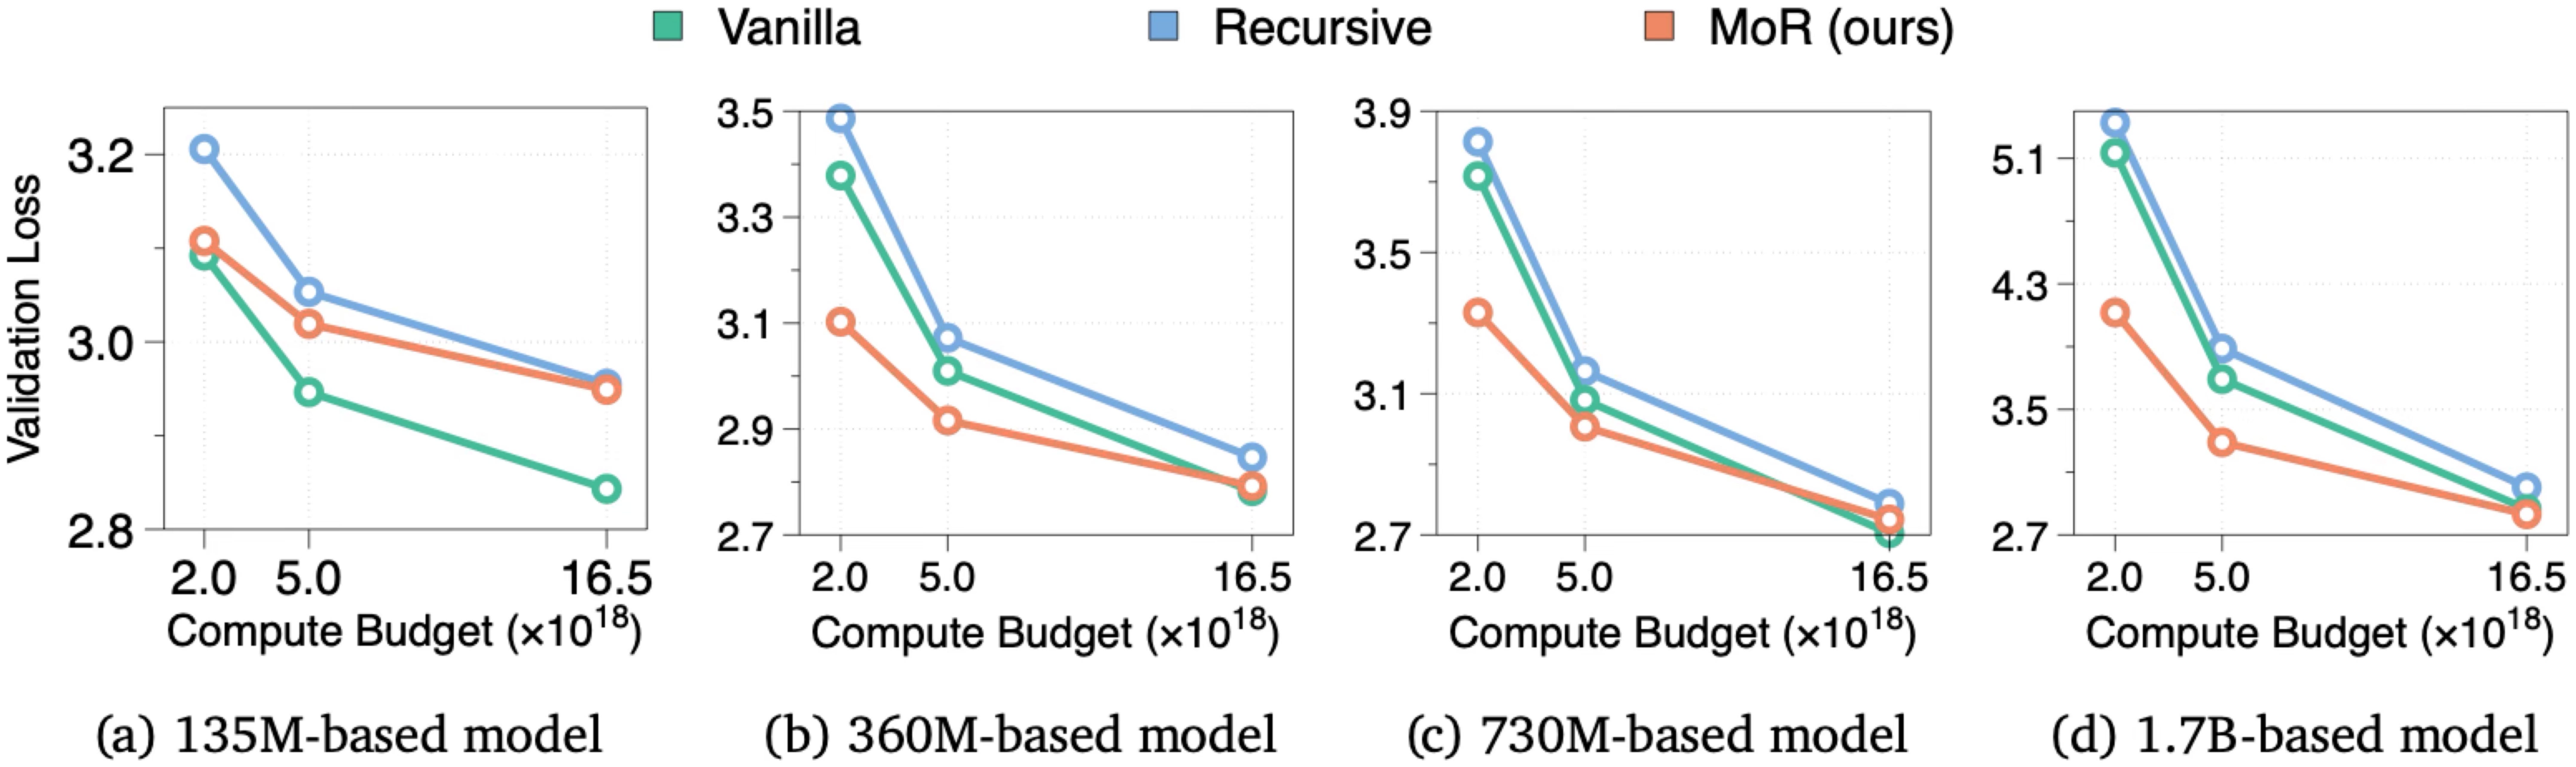
At the smallest model scale, the regular transformer performs best. For the larger models, Mixture-of-Recursions catches up and often performs better, especially at the smaller training budgets. At the largest budget, several of the curves are very close. So, the advantage depends on the model size and how much compute we spend on training.
Another detail here is that equal training compute doesn’t necessarily mean an equal number of training tokens. By skipping some computation, Mixture-of-Recursions can process more tokens within the same budget.
I think this is an interesting example because it shows that there are several choices within the looped-transformer idea, that is, how many loops there are at each position and how that’s decided.
So, in short, we can say that using looped transformers can improve model quality at a fixed compute budget if the model is large enough. (It also illustrates the importance of running some experiments at scale; e.g., just looking at the smaller 135M parameter model, we would have drawn the opposite conclusion.)
3. Side note: Recurrent Neural Networks (RNNs)
By the way, if you have a background in deep learning (or even artificial neural networks in the 1990s), the looping or “recurrent depth” idea should be somewhat familiar. Remember recurrent neural networks (RNNs)? The whole idea in RNNs is to reuse the layers (weights) from a previous iteration.
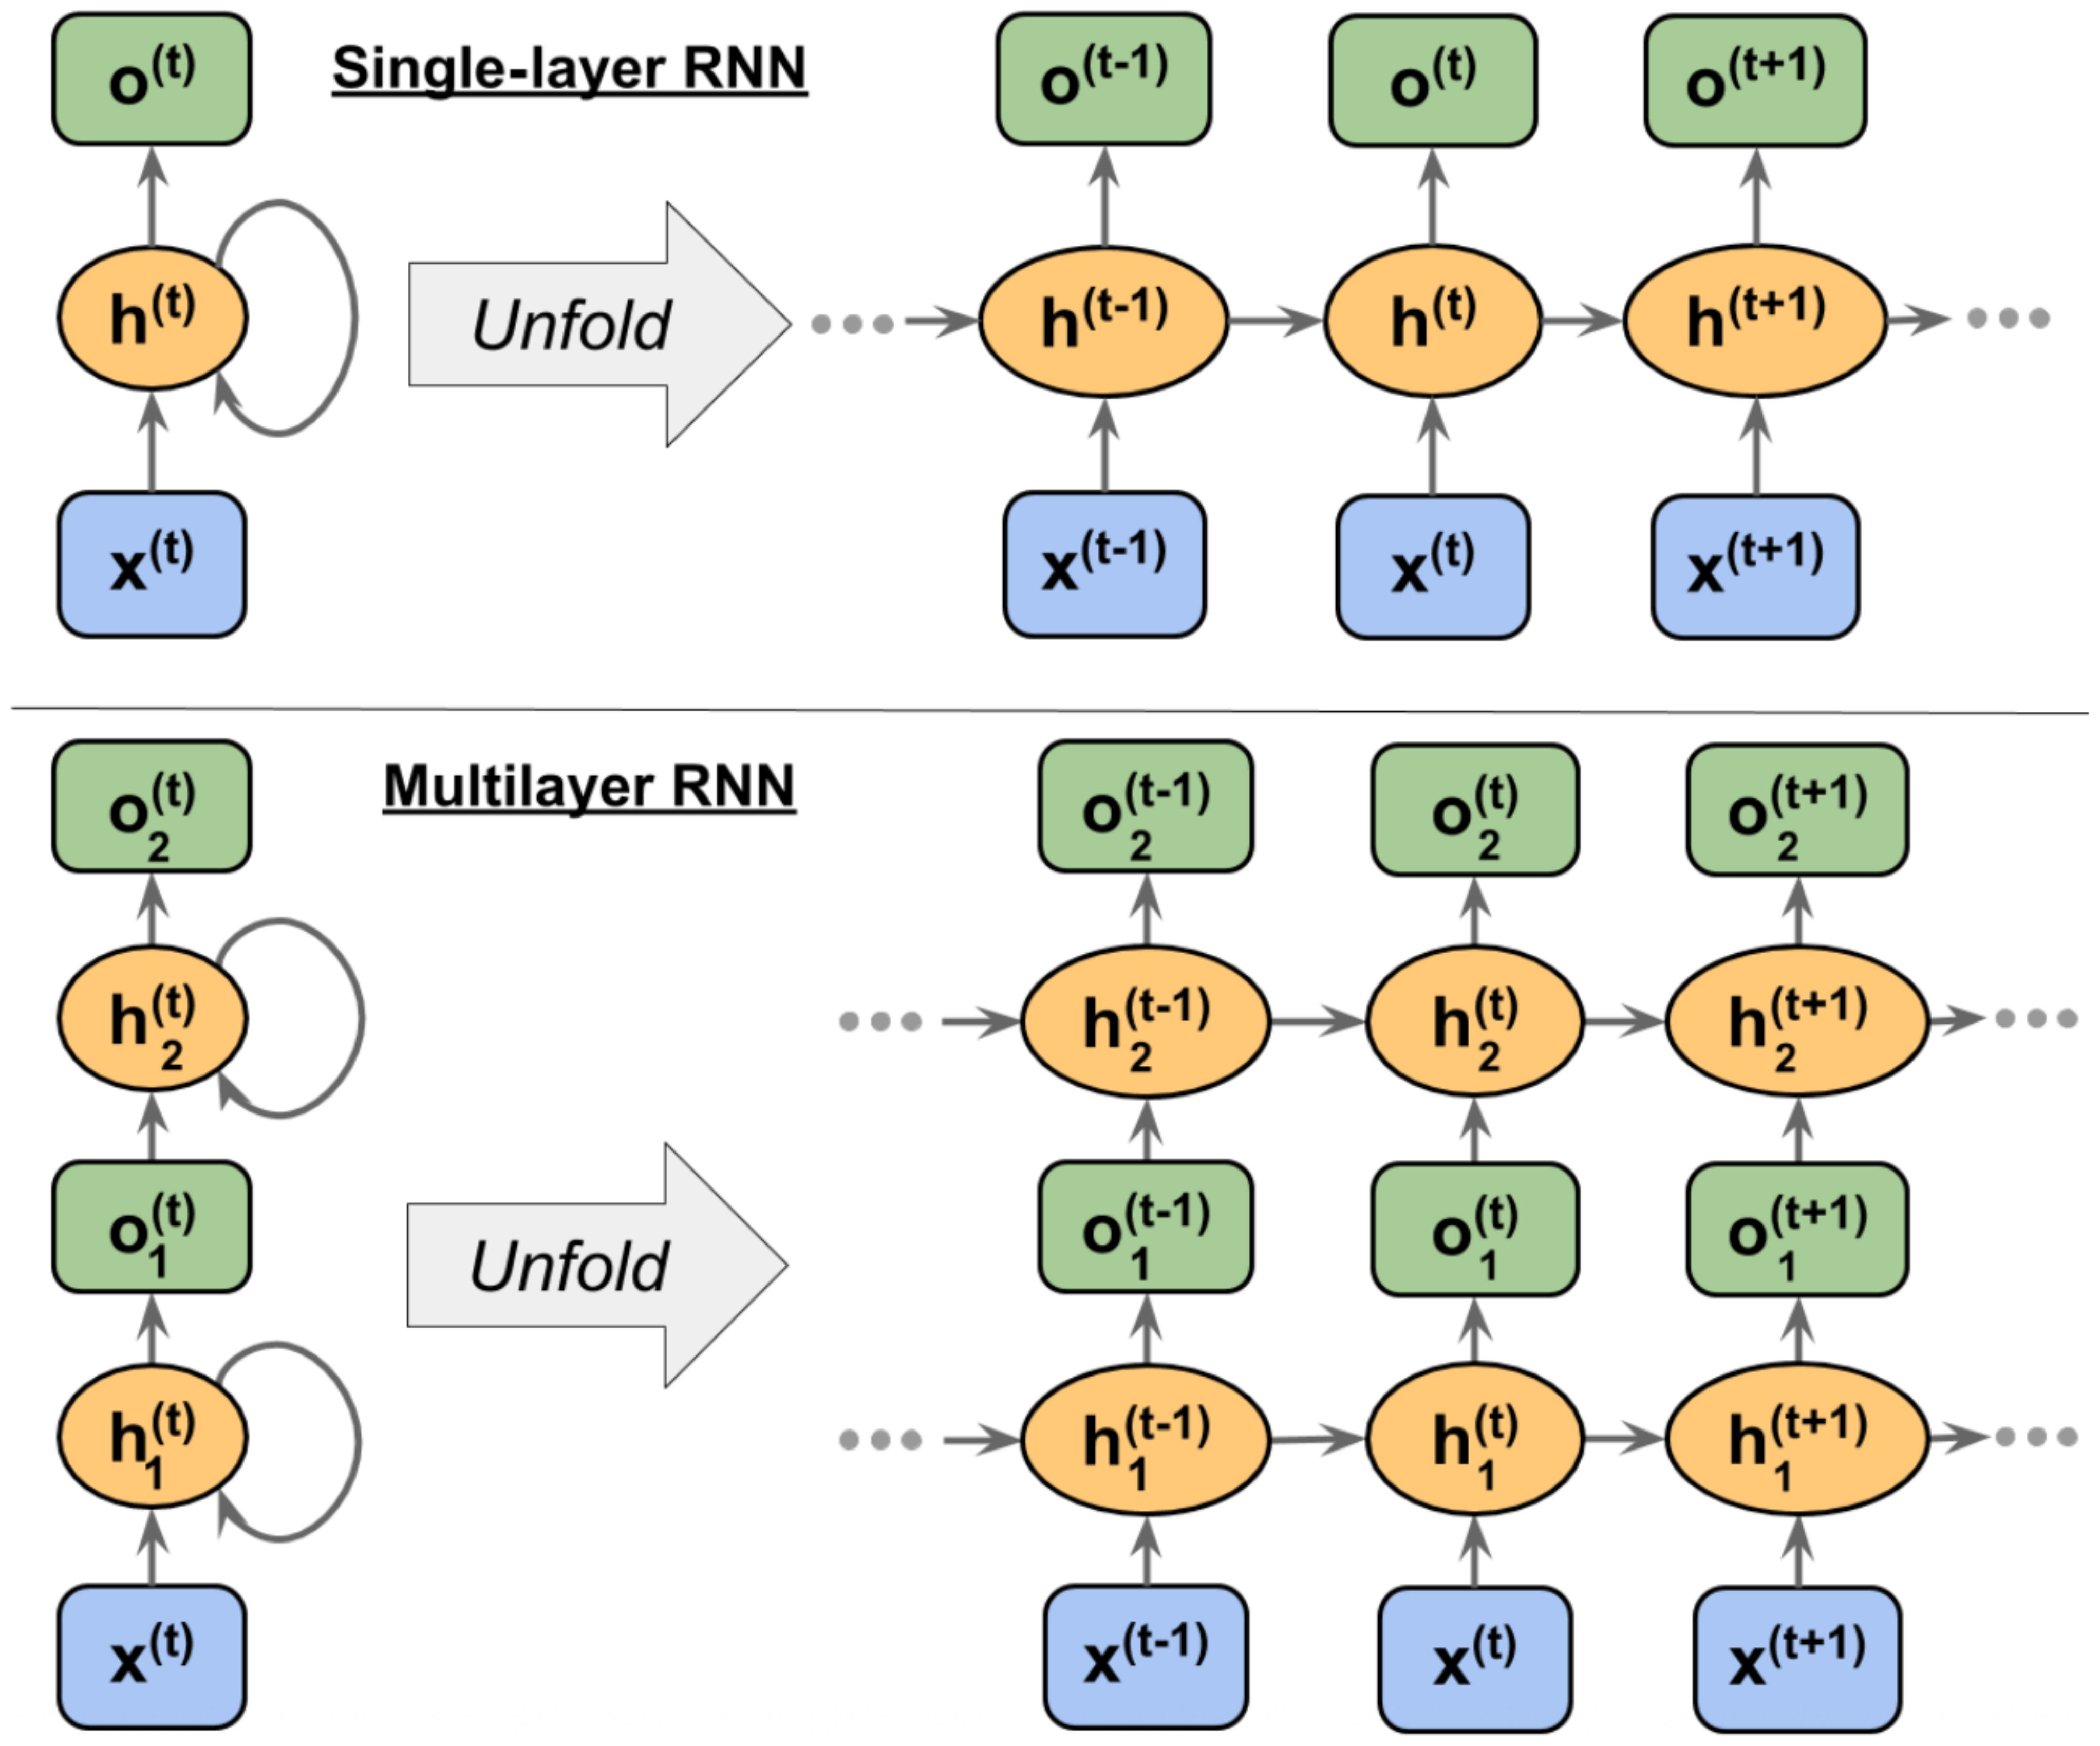
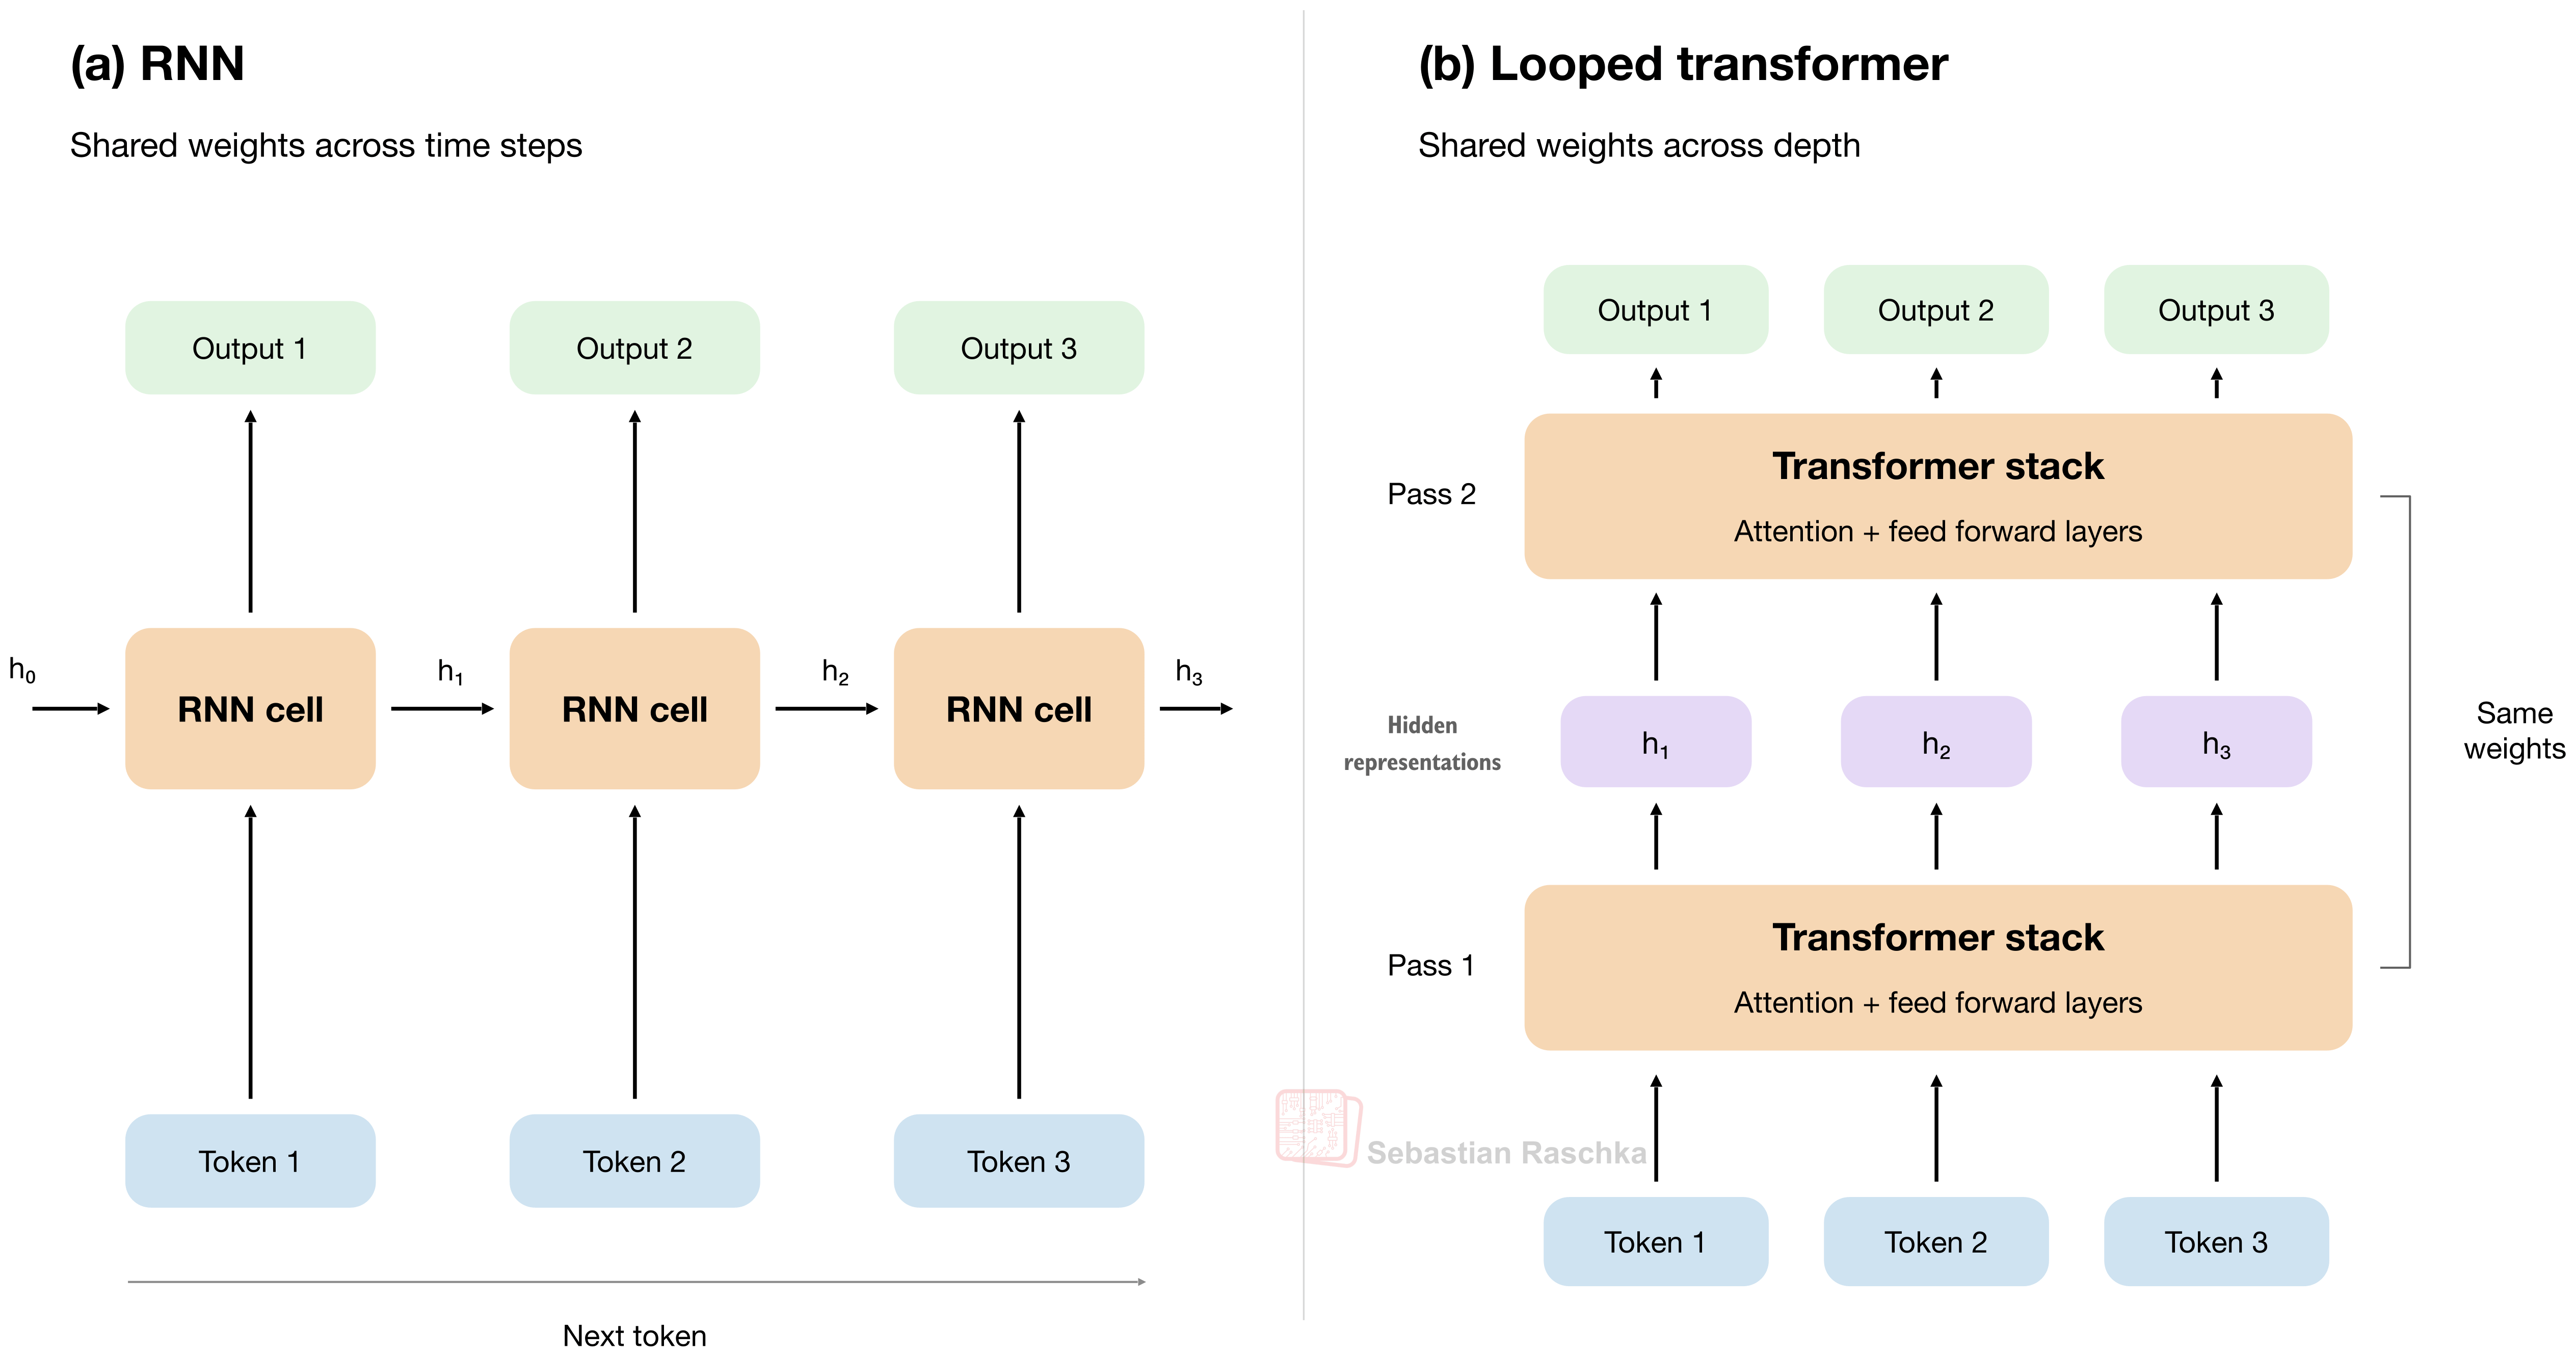
The main distinction is that RNNs reuse their weights across time steps. That is, the hidden state is carried forward from one token to the next. In the looped transformer, the looping of a token is across the architecture depth.
Or, in other words, in a conventional RNN, each step takes the next element in the input sequence and the hidden state from the previous step. So, when the RNN is processing a chunk of text, it reads one word or token at a time and carries information from the earlier words forward in its hidden state.
In a looped transformer, the intermediate representation of a given token goes through the transformer stack multiple times. The model still uses attention to pass information between tokens.
If this analogy is a bit too confusing, don’t worry about it too much. A perhaps simpler way to think about looped transformers is to think of them as reusing transformer blocks, similar to making the model bigger but with weight sharing.
4. Does Astra even use looped transformers?
Before we discuss whether the looped transformer mechanism obscured reasoning traces, as rumored in The Information quote from earlier, does GPT-6 Astra even use the looped transformer concepts?
We have to keep in mind that this is still just a rumor or scoop, with no official confirmation. If the model were open-weight, we could double-check this ourselves, of course, but in this case we have to rely on unverified reporting.
However, I think it’s highly likely that GPT-6 Astra uses looped transformer aspects. First, there is the reporting mentioned above. Second, it’s a technique that has shown promise in past studies (as discussed earlier), so why not? Third, OpenAI’s chief scientist said the following.
[...] The depth of the computation graph for our present frontier models, including Astra, is within a factor of two of GPT-4. [...]
However, this doesn’t confirm the
正文保留英文原文,标题与摘要由机器翻译。
原文发布于 Sebastian Raschka(GPT-6 Astra, Looped Transformers, and Hidden Reasoning),标题、摘要与正文由机器翻译,术语按行业惯例统一,未经人工逐句校订。
