深入 GitHub 全新 Git 存储架构
上周在 GitHub Universe 大会上,我们发布了全新的 Git 存储架构,能够每秒处理数千次写入,读取能力则可按需扩展。通过内部测试,我们已证明该架构可支持 5,000 个智能体同时在一个仓库上工作,每秒向一个仓库发送 7,200 次 push,同时还能以始终如一的低延迟承载读取流量。这一新架构是 GitHub 为数亿开发者支持智能体式开发的基础,我们一直在 GitHub 持续运行的同时,于其底层构建这套架构。
过去一年里,智能体改变了 GitHub 上「繁忙仓库」的模样。在本系列的第一篇文章中,我们阐述了下一代 Git 存储架构背后的两条原则:最小化协调,以及将存储与计算解耦。在上一篇文章中,我们介绍了过渡方案:将 99.99999% 的仓库迁移到 Azure,把写入法定人数(write quorum)的范围限定到单个引用,并搭建由 Azure Blob Storage 支撑的虚拟副本。
我们在文末还留下了一个观察:一次写入中真正需要排序的部分非常少。Git 对象是不可变的,并且以其内容命名,这意味着两个写入者可以同时存储对象,而无需就任何事项达成一致。一次 push 中需要达成一致的部分是引用更新,而引用更新相比之下非常小。虚拟副本是围绕这一点进行构建的第一步,也是我们让仓库接入新架构的方式。
架构的其余部分正是建立在这一观察之上。只有引用(reference)更新需要达成一致。这让过去紧密耦合的 Git 基础设施各部分(存储数据、处理请求、维护仓库)得以独立扩展。对开发者而言,Git 依然是 Git:他们以同样的方式 push、fetch 和 branch,同样的保护机制也依然到位。下文我们将梳理这一设计背后的需求,跟踪一个请求在系统中的流转过程,并深入剖析其中两个组件。
我们从两个维度来思考 GitHub 平台的规模:
如今,GitHub.com 上最繁忙的仓库每秒最多接收几十次写入,且通常以短时突发的方式出现。随着越来越多此类工作转向并行运行、全天候工作的智能体,我们预计在未来一年内,这种突发将转变为持续速率。每次 push 都会带来更多读取:CI 运行、部署系统拉取新提交,以及其他智能体为获取上下文而抓取该提交。这种读取扇出对整体流量产生了巨大的放大效应,且随写入量同步增长。
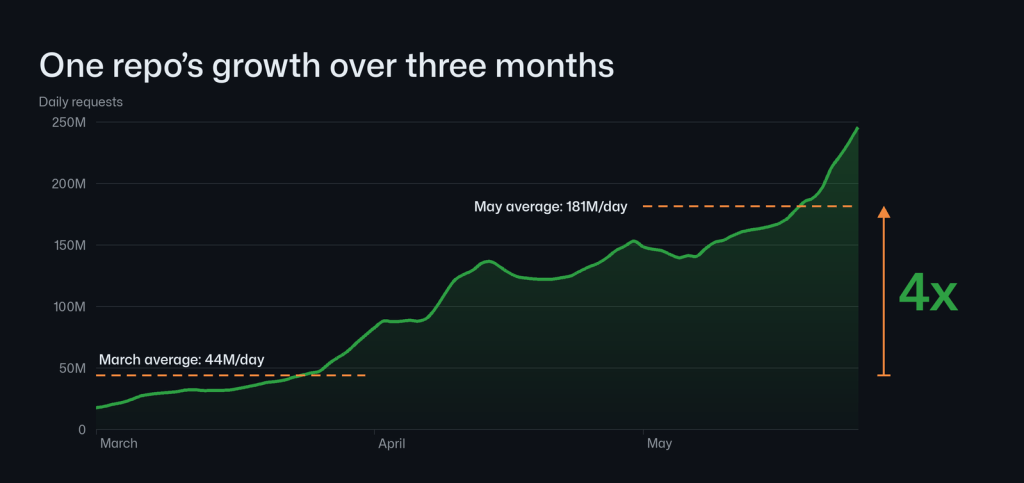
在处于曲线顶端的仓库上,我们已经看到这一趋势的显现。下图展示了 3 月至 5 月期间 GitHub 上某个仓库的每日请求量,其间其流量增长了约 4 倍。自那以后,它的增长一直保持指数级轨迹。
我们必须为一个智能体驱动的开发以这种速度持续加速的世界做规划。我们没有只规划下一个增量,而是把目标设定为规模至少提升两个数量级。对单个仓库而言,这意味着新架构需要:
除此之外,系统还必须能够提升整体可靠性并在全球范围内扩展。
2026 年 5 月,在初步完成 Azure 迁移之后不久,我们就开始着手设计一个能够满足这些需求的新方案。我们尝试了多种路径。在所有方案中,pack 数据都存放在 Azure Blob Storage 中,其中一些方案我们还尝试把引用状态也放在那里。我们会在下文中讨论发现的一些权衡取舍,但最终确定的设计,我们认为在保留 GitHub 这类平台所要求的正确性、持久性、可用性和延迟保证的同时,最大化了吞吐。我们把它称为“Rubicon”,以此致敬整个行业随着智能体式开发而跨过的不可回头之点。
让我们自上而下地梳理 Rubicon。许多东西保持不变:来自 Git 客户端、API 和 Web UI 的请求抵达 Spokes,Spokes 仍然负责路由与负载均衡,并提供供 GitHub 其余部分读写仓库数据的内部 API。Spokes 也继续充当放置与均衡服务,维护水平扩展所需的分区、隔离与租户公平性。相比之下,Spokes 之下的数据平面则是全新的。
Spokes 会把每个请求路由到分配给该仓库的一小组虚拟副本之一。虚拟副本是单一的一批可随时销毁的计算资源,负责处理读取、写入或两者兼有。虚拟副本的本地磁盘是一份缓存,任何时候都可以重建。
在条件允许时,Spokes 会把某个仓库的流量路由到同一批虚拟副本,以保持其缓存处于热状态、降低延迟,但正确性并不依赖于请求落在某个特定的虚拟副本上。当某个虚拟副本消失时,该仓库的其他虚拟副本会继续提供服务,替补副本则在流量到来时逐步填充自己的缓存。
当某个仓库变得繁忙时,我们会增加更多虚拟副本。另外,一组压缩节点在后台运行,直接对接 Blob Storage 和 Ref-CAS,合并每个仓库的 pack 并移除不可达对象。这项工作从不在虚拟副本上运行,这意味着它们的 CPU 和内存几乎可以全部用于处理请求。
持久化状态存放在两个地方:
让我们从一次写入和一次读取的视角来梳理这套架构:
在新架构中,我们采取了许多不同的做法,从虚拟副本上的软件栈,到针对不同使用场景(例如大量小型仓库 vs. 单个大型仓库)如何调优流量路由和工作负载调度。下面我们深入探讨该架构中的两个组件,并围绕这两条设计原则讲述它们的故事。
像 Azure Blob Storage 这样的对象存储服务在其擅长的领域表现得极为出色,也非常适合源码存储这类数据密集型应用。它们具备持久性和多副本,容量可按需扩展,每字节成本相对较低,并且只要流量分散到大量 key 上,就能提供极高的聚合吞吐。因此,新的 Git 存储架构中几乎所有需要持久化的数据都存放在 Azure Blob Storage 中,包括:
这些数据大多只写入一次到某个特定的 key,之后不再变化,这正是它非常适合 Blob Storage 的原因。
引用(references)则正好相反。一个繁忙仓库的引用是一小块相对较小的状态,却有许多写入同时争相更新它。这种访问模式更难由 Blob Storage 来承载,我们最初的几个原型也让我们明白了原因。对于这类工作负载,对象存储是一种直观的选择,而且在一定的规模范围内效果不错:条件写入免费提供了 compare-and-swap 语义,而且数据本身已经具备持久性并有副本。然而,我们陷入了一组棘手的选择,下面用我们尝试过的两种方案来说明。
我们的第一种方案是为仓库的所有引用建立一份预写日志(write-ahead log),并以单个 blob 作为索引。每一次更新都是针对该 blob 的一次条件写入。这个方案是正确的,读取成本也很低:虚拟副本只需询问该 blob 是否发生了变化,如果没有变化,就此结束。它的短板在写入。同一时刻只能有一个针对某个 blob 的条件写入在途,因此即便我们把一次写入期间到达的所有 push 都合批进下一次写入,仓库的写入上限仍是一趟访问单个 blob 的往返一次写入。在实践中,这给我们带来的写入吞吐只有每秒数百次。
我们的第二种方案是把引用拆分到多个分段 blob 中,每个引用通过哈希落入其中一个。对不同分段中引用的写入不再相互等待,从而抬高了上限。但一次读取现在必须检查每一个分段,才能知道是否有任何变化,而且它的速度取决于最慢的那个分段。我们等于用读取延迟换来了写入延迟的改善,而读取的次数比写入高出几个数量级。我们可以把多次写入和一次读取并排展示,来直观说明这一点:
两种方案都无法满足全部需求,于是我们造了另一种东西:一个专为引用服务的复制日志服务,即 Ref-CAS 服务。这就是我们在上一篇文章结尾提到过的、仍然存在于整个技术栈某处的那个(小型)共识组。下面是它的工作方式。
Ref-CAS 中的每一次引用更新,都是一次由法定人数提交的比较并交换操作。事务只锁定它触及的那些引用,检查每一个引用是否仍具有写入方所期望的值,并且只有当该日志的大多数副本都已记录之后,这次更新才会对外可见。智能体大多推送到各自的分支,因此大多数更新不会产生争用,并且可以并行复制。当两次推送确实更新了同一个引用时,只有其中一次会追加到日志中。
原文较长,译文为节选;译文由英文原文机器翻译,术语按行业惯例统一,可在文末展开原文核对。
查看英文原文(Inside GitHub’s new Git storage architecture)
Last week at GitHub Universe, we announced our new Git storage architecture, capable of handling thousands of writes per second with reads that scale on demand. Through internal testing, we’ve demonstrated the ability to support 5,000 concurrent agents working on a repository, sending 7,200 pushes per second to a repo, all while serving read traffic with consistently low latency. This new architecture is the foundation for GitHub to support agentic development for hundreds of millions of developers, and we’ve been building it underneath GitHub while it keeps running.
Over the past year, agents changed what a busy repository looks like on GitHub. In our first post in this series, we laid out the two principles behind our next-generation Git storage architecture: minimize coordination, and decouple storage from compute. In our last post, we covered the bridge: moving 99.99999% of repositories into Azure, scoping the write quorum to individual references, and standing up virtual replicas backed by Azure Blob Storage.
We also left off with an observation: very little of a write needs to be ordered. Git objects are immutable and named by their contents, meaning two writers can store them at the same time without agreeing on anything. The part of a push that needs agreement is the reference update, and a reference update is tiny in comparison. Virtual replicas were the first step toward building around that, and the means by which we onboard repositories to the new architecture.
The rest of the architecture builds on that observation. Only reference updates need agreement. That lets the parts of Git infrastructure that used to be tightly coupled (storing data, serving requests, and maintaining repositories) scale independently. For developers, Git stays Git: they push, fetch, and branch the same way, with the same protections in place. Below, we walk through the requirements behind the design, follow a request through the system, and dive deep into two of its components.
Building for agent scale
We think about the scale of the GitHub platform along two axes:
- Horizontal scale is how many developers and agents can work across many repositories. Many of GitHub’s current approaches on this axis have been battle-tested over the years and are carried forward to the new architecture: partitioning of tenants across infrastructure, isolation and/or fairness enforcement of tenant traffic, and load-aware routing, to name a few.
- Vertical scale is how many developers and agents can work on one repository. As agents write more code, we expect individual repositories to get larger and busier, so most of our requirements came from the vertical axis.
Today, the busiest repositories on GitHub.com receive at most dozens of writes in a single second, typically in short bursts. As more of that work shifts to agents running in parallel and around the clock, we expect those bursts to become a sustained rate within the next year. Each push leads to more reads: CI runs, deployment systems pull the new commit, and other agents fetch it for context. This read fan-out results in a large amplification effect on overall traffic that scales with writes.
We’re already seeing this trend play out on repositories at the top of the curve. The chart below shows daily requests to one repository on GitHub from March to May, when its traffic grew about 4x. Its growth has continued on an exponential trajectory since then.
We have to plan for a world where agent-driven development keeps accelerating at this speed. Instead of planning for the next increment, we set a target of at least two orders of magnitude more scale. For a single repository, that meant the new architecture needed to:
- Accept thousands of writes per second.
- Support multiple writer nodes. There are two reasons for this:
- Experience has taught us that indexing incoming packs and checking object connectivity are the most CPU-expensive parts of a write, and that cost scales with the size of the write, so a single node will become compute-bound quickly.
- Spreading that work across many nodes improves fault tolerance and shortens recovery when a node fails.
- Minimize commit latency. An agent waits on each push before it moves to its next step.
- Record changes in order for each reference with the ability to quickly linearize across references. A virtual replica that falls behind needs to catch up by downloading only the data it needs to serve the incoming request.
- Keep reads cheap when nothing has changed, which is the common case given the read-to-write ratio.
- Let each component scale independently.
On top of that, the system had to be able to improve overall reliability and scale globally.
Introducing “Project Rubicon”
In May of 2026, hot on the heels of the initial Azure migration, we started working on a design that could meet those demands. We tried several approaches. In all of them, pack data lived in Azure Blob Storage, and in some we experimented with keeping reference state there too. We’ll cover some of the trade-offs we found below, but we settled on a design we felt maximized throughput while preserving the correctness, durability, availability, and latency guarantees a platform like GitHub requires. We called it “Rubicon,” a nod to the point of no return the industry crossed with agentic development.
Let’s walk through Rubicon from the top down. Many things stay the same: requests from Git clients, the API, and the web UI arrive at Spokes, which still handles routing and load balancing, and serves the internal API that the rest of GitHub uses to read and write repository data. Spokes also maintains its role as a placement and balancing service, maintaining the partitioning, isolation, and tenant fairness required for horizontal scale. The data plane underneath Spokes, in contrast, is new.
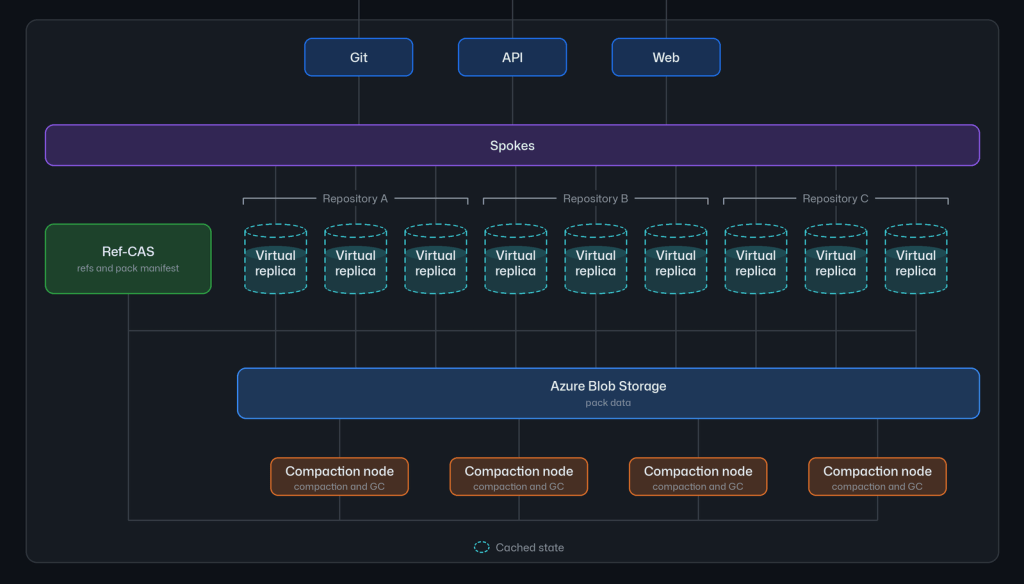
Spokes routes each request to one of a small group of virtual replicas assigned to that repository. Virtual replicas are a single fleet of disposable compute that serves reads, writes, or both. A virtual replica’s local disk is a cache that can be rebuilt at any time.
Spokes routes a repository’s traffic to the same virtual replicas when it can, which keeps their caches warm and latency low, but nothing about correctness depends on a request landing on any particular virtual replica. When a virtual replica goes away, the repository’s other virtual replicas keep serving, and a replacement fills its cache as traffic arrives.
When a repository gets busy, we add more virtual replicas. Separately, a fleet of compaction nodes works in the background, directly against Blob Storage and Ref-CAS, to merge each repository’s packs and remove unreachable objects. That work never runs on a virtual replica, meaning their CPU and memory can be almost entirely dedicated to serving requests.
Durable state lives in two places:
- Git objects, in the form of packs and auxiliary read acceleration data, live in Azure Blob Storage.
- References and the list of packs that make up the repository (the pack manifest) live in a separate replicated log service we call Ref-CAS (for “Reference Compare-and-Swap”).
Let’s walk the architecture from the perspective of a write and a read:
- Write: a virtual replica indexes the incoming pack and uploads it to Blob Storage, then commits one transaction to Ref-CAS that lists the pack in the manifest and updates the references. Later, a compaction node merges that pack with others to keep reads fast.
- Read: a virtual replica checks its reference version with Ref-CAS, pulls the packs it needs from Blob Storage into its cache, and serves the read from there.
There are many distinct approaches we’ve taken within the new architecture, from the software stack on the virtual replicas to how traffic routing and workload scheduling are tuned for different use cases (e.g., many small repos vs. one large one). Let’s dive deep into two components of the architecture and tell their stories centered on the two design principles.
Minimizing coordination: mutating reference state at high throughput
Object storage services like Azure Blob Storage are incredibly good at what they do, and natural fits for many data-heavy applications like source code storage. They are durable and replicated, hold as much as we need them to, have a relatively low cost per byte, and deliver exceptionally high aggregate throughput so long as traffic is spread across many keys. As a result, nearly everything durable in the new Git storage architecture lives in Azure Blob Storage, including:
- Packs and indexes written by pushes, compaction, and garbage collection.
- Various read accelerators (like multi-pack indexes, reachability bitmaps, and some custom formats) that our maintenance process builds from those packs.
- Records that let compaction and garbage collection resume or audit their work, along with the leases that compaction nodes use to claim work.
- Cached responses for frequently repeated fetches.
- Checkpoints for the reference state of the repository, though not the authoritative state used to serve requests.
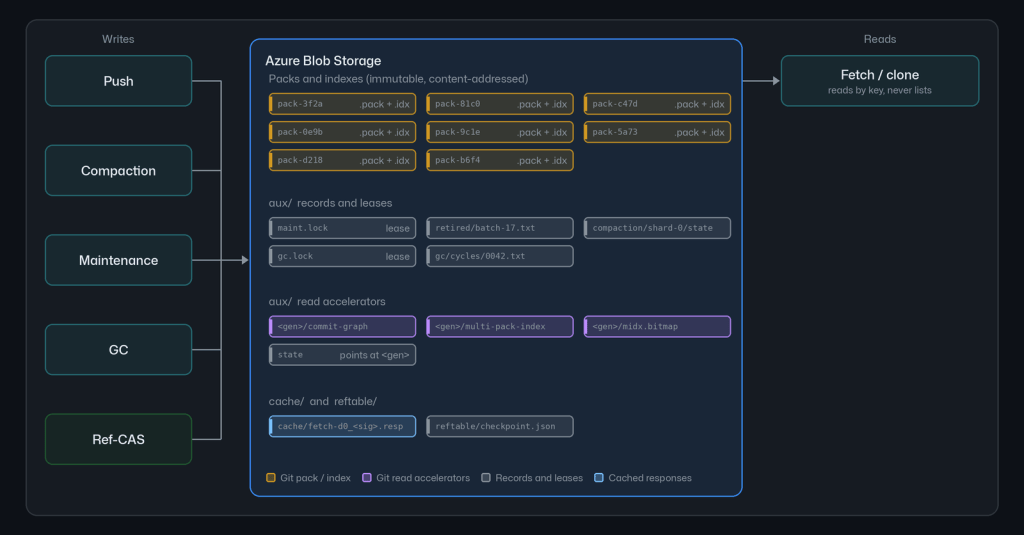
Most of that data is written once to a distinct key and never changes afterward, which is what makes it highly suitable for Blob Storage.
References are the opposite. A busy repository’s references are a relatively small piece of state that many writes race to update at the same time. That access pattern is harder to serve from Blob Storage, and our first prototypes showed us why. Object storage for this kind of workload is an intuitive choice, and one that works well up to a certain level of scale: conditional writes give a compare-and-swap for free, and the data is already durable and replicated. However, we ran into a difficult set of choices, illustrated below by two approaches we tried.
Our first approach was a write-ahead log for all of a repository’s references, indexed by a single blob. Every update is a conditional write against that blob. It’s correct, and reads are cheap: a virtual replica asks whether the blob has changed, and if it hasn’t, it’s done. Writes are where it falls short. Only one conditional write to a blob can be in flight at a time, so even when we batch every push that arrives during a write into the next one, the repository’s write ceiling is one write per round trip to a single blob. In practice, this netted us write throughput in the mid-hundreds per second.
Our second approach split the references across several segment blobs, with each reference hashing to one of them. Writes to references in different segments no longer wait on each other, which raises the ceiling. But a read now has to check every segment to know whether anything changed, and it’s only as fast as the slowest segment. We’d traded write latency for read latency, and reads outnumber writes by orders of magnitude. We can visualize this by showing multiple writes and a read side by side:
Neither option met every requirement, so we built something else: a replicated log service dedicated to references, or the Ref-CAS service. This is the (small) consensus group we said at the end of the last post was still somewhere in the stack. Here’s how it works.
Each reference update in Ref-CAS is a compare-and-swap committed by a quorum. A transaction locks only the references it touches, checks that each one still has the value the writer expects, and becomes visible once a majority of the log’s replicas have recorded it. Agents mostly push to their own branches, so most updates don’t contend, and they replicate in parallel. When two pushes do update the same reference, only one will append to the log.
Each commit to Ref-CAS gets a log sequence number (LSN), and the repository’s version is the LSN of its latest commit. Reads start with a version check against that version. A virtual replica sends the version of the reference state it already holds. If that version is still current, the reply carries no references at all, and an unchanged repository costs a single comparison. If the virtual replica is behind, it gets back the current references and version, along with pointers to pack data and anything else that needs to be known, such as when the last garbage collection cycle occurred.
Unlike the consensus group in our legacy architecture, Ref-CAS never holds or validates object data. It only stores pointers to it. A virtual replica uploads a push’s pack to Blob Storage before it commits the reference transaction. A reference only ever points at objects that are already durable.
These approaches allow us to transact reference state alone in the tens of thousands of operations per second, and provide a baseline for additional annotations on the replication log that help reads decide what to download for a given request.
But supporting thousands of writes per second on a single repository creates a second-order problem: maintaining the performance of reads and writes. For that, we needed a different approach to compaction.
Decoupling storage from compute: compaction at thousands of writes per second
Every push adds a pack to Blob Storage. Git can serve a repository from many packs, but each additional pack makes lookups slightly more expensive, so the pack count can’t grow without bound. In our legacy architecture, compaction runs on the same replicas that serve traffic, and it has to run on every replica. In the new architecture, it runs entirely in the background on separate nodes, directly against durable storage, using the Ref-CAS service to notify virtual replicas of the evolving state.
Compaction nodes each claim ownership over a subset of the repository’s data via a lease, which allows us to scale compaction horizontally. Here’s how one compaction node works through a single shard of a repository’s packs:
The node first takes a lease on the shard in Blob Storage, so only one node compacts a shard at a time. Meanwhile, virtual replicas keep uploading packs and listing them in the pack manifest. The node reads the manifest to find new packs and collects them into an open segment, which is effectively a holding ground for data about to be compacted. When the segment reaches a defined limit based on pack count, size, or age, it seals the segment so it accepts no new packs, then combines its packs into fewer, larger ones. While compaction happens, the next segment for the shard can begin capturing its input packs. Before anything is published, the node checks that the new packs contain exactly the same objects as the inputs. It then uploads the new packs and adds them to the manifest. A second transaction removes the inputs from the manifest, and cleanup deletes them later.
To scale out, this process runs independently for many shards at once. Each pack’s hash maps to a shard, so adding shards and nodes adds compaction throughput. A compacted pack that’s still under the size limit goes back into a shard by its own hash and merges again, so packs grow in tiers until they reach the limit. The net result is an effectively flat pack count while pushes climb:
Compaction merges packs, but it keeps every object. Garbage collection is the step that removes objects nothing references anymore, like the ones left behind by deleted branches and force-pushes. In our new architecture, garbage collection works very similarly to compaction by using dedicated workers to handle the compute-heavy portion. It also has a few special behaviors for safely removing data, which are worthy of their own discussion.
Using these approaches, we’ve been able to consistently demonstrate a flat latency curve as writes climb, and we have other planned optimizations to make the compaction and garbage collection processes themselves more performant.
What comes next
The two principles we started with let each part of this architecture scale on its own. We scale reads and writes by adding virtual replicas. Ref-CAS orders each reference independently instead of the whole repository. We scale maintenance by adding compaction nodes. Our goal is for every repository, from one developer’s side project to the busiest monorepo, to run on the same architecture with no special handling for the busy ones. Repositories don’t stay small. A side project can pick up a fleet of agents overnight, and it shouldn’t need a migration or special handling from us to keep up. One architecture also means every improvement we make reaches every repository at once.
This foundation lets us do a lot more. We’re focused on three areas next: scaling the architecture beyond what we can predict we’ll need today, making agents more efficient at the work they do on GitHub, and evolving Git itself for agentic development.
Improving the architecture
We have plans to take this architecture further. Each of these improvements lets a repository handle more activity while reducing the work behind each request:
- Read only what’s needed. Fetch a single object from Blob Storage instead of the whole pack that holds it.
- Organize packs by type. Group commits, trees, and blobs into their own packs. Many requests then touch less data.
- Partial replicas. Serve requests without every pack on local disk.
- Materialized views. Keep repository data in ready-to-use forms, like prepared archives, a near-live shallow copy of the default branch, and agent session context stored alongside each commit.
- Global replicas. Place replicas in any region, close to the workloads that use them. Reads stay within bounded staleness of the latest write.
- Scale to zero. Grow and shrink the fleet with the repositories that are actually active.
Efficient agent operations on GitHub
Scaling the infrastructure is one side of supporting agents. The other side is making each agent operation cheaper: fewer bytes to fetch, fewer round trips, and less waiting on changes. Each of these fast-follow items builds on the storage work in this post:
- Work without a clone. Many agent tasks never need a full working tree. They need a handful of files and enough context to make a change. They can read both straight from the server.
- Atomic commit API. Land a multi-file change in one operation. The whole change commits, or it’s rejected cleanly on conflict.
- Event streams. Agents and the systems around them work best with real-time information. A generic event stream lets them subscribe to changes and react as they happen.
Improving Git for agents
We also have work to do in Git itself. GitHub has been a longtime contributor to the Git project, and we’re not stopping now. A few examples of the work we’re excited to continue:
- Lightweight clones. Partial clone, shallow clone, and sparse checkout each let an agent fetch less. Each one has gaps. They don’t always work well together, either. We want to improve each piece and make them fit.
- Remove hidden scaling costs. Git still has code paths that slow down much faster than the repository grows. Recent releases fixed several of them, but we expect to find more.
- Faster history walks. Metadata like the commit-graph can answer merge-base and reachability questions without walking every commit. That matters most when an agent’s API call turns into Git work on the server.
- Avoid common gotchas. Agents make the same mistakes developers do. Git can catch more of the common ones and warn before they cause damage.
Agents have changed how software gets built. GitHub and Git are changing with it. We’re excited to take this new architecture across the starting line. It’s available in a limited private preview now, with a broader rollout early next year. We can’t wait to see what teams build when the number of agents working on a repository is limited by their ideas. We’ll keep evolving Git and GitHub alongside our customers and the Git community.
The post Inside GitHub’s new Git storage architecture appeared first on The GitHub Blog.
正文保留英文原文,标题与摘要由机器翻译。
原文发布于 GitHub Blog(Inside GitHub’s new Git storage architecture),标题、摘要与正文由机器翻译,术语按行业惯例统一,未经人工逐句校订。