在 AWS Trainium 上用 SGLang-Neuron 部署前沿模型
今天,Amazon 宣布 SGLang-Neuron 已公开发布,可通过 AWS Deep Learning Container 获取,该容器由 RadixArk 与 Annapurna Labs 合作发布。借助 SGLang-Neuron,你可以使用与如今相同的 SGLang 接口,在 AWS Trainium 上用 SGLang 提供模型服务并生成强化学习(RL)rollout。Trainium 是 AWS AI 芯片产品系列,可为大规模 AI 训练和推理带来出色的经济性。如今,在 Trainium 上运行 SGLang 遵循你已经熟悉的 SGLang 工作流:通过 SGLang 的服务端接口启动模型,并使用相同的生成 API 调用端点。在该接口之下,SGLang-Neuron 运行在原生 PyTorch 上。凭借其树外(out-of-tree)插件设计,Trainium 支持与 SGLang 核心可各自独立开发、更快迭代。
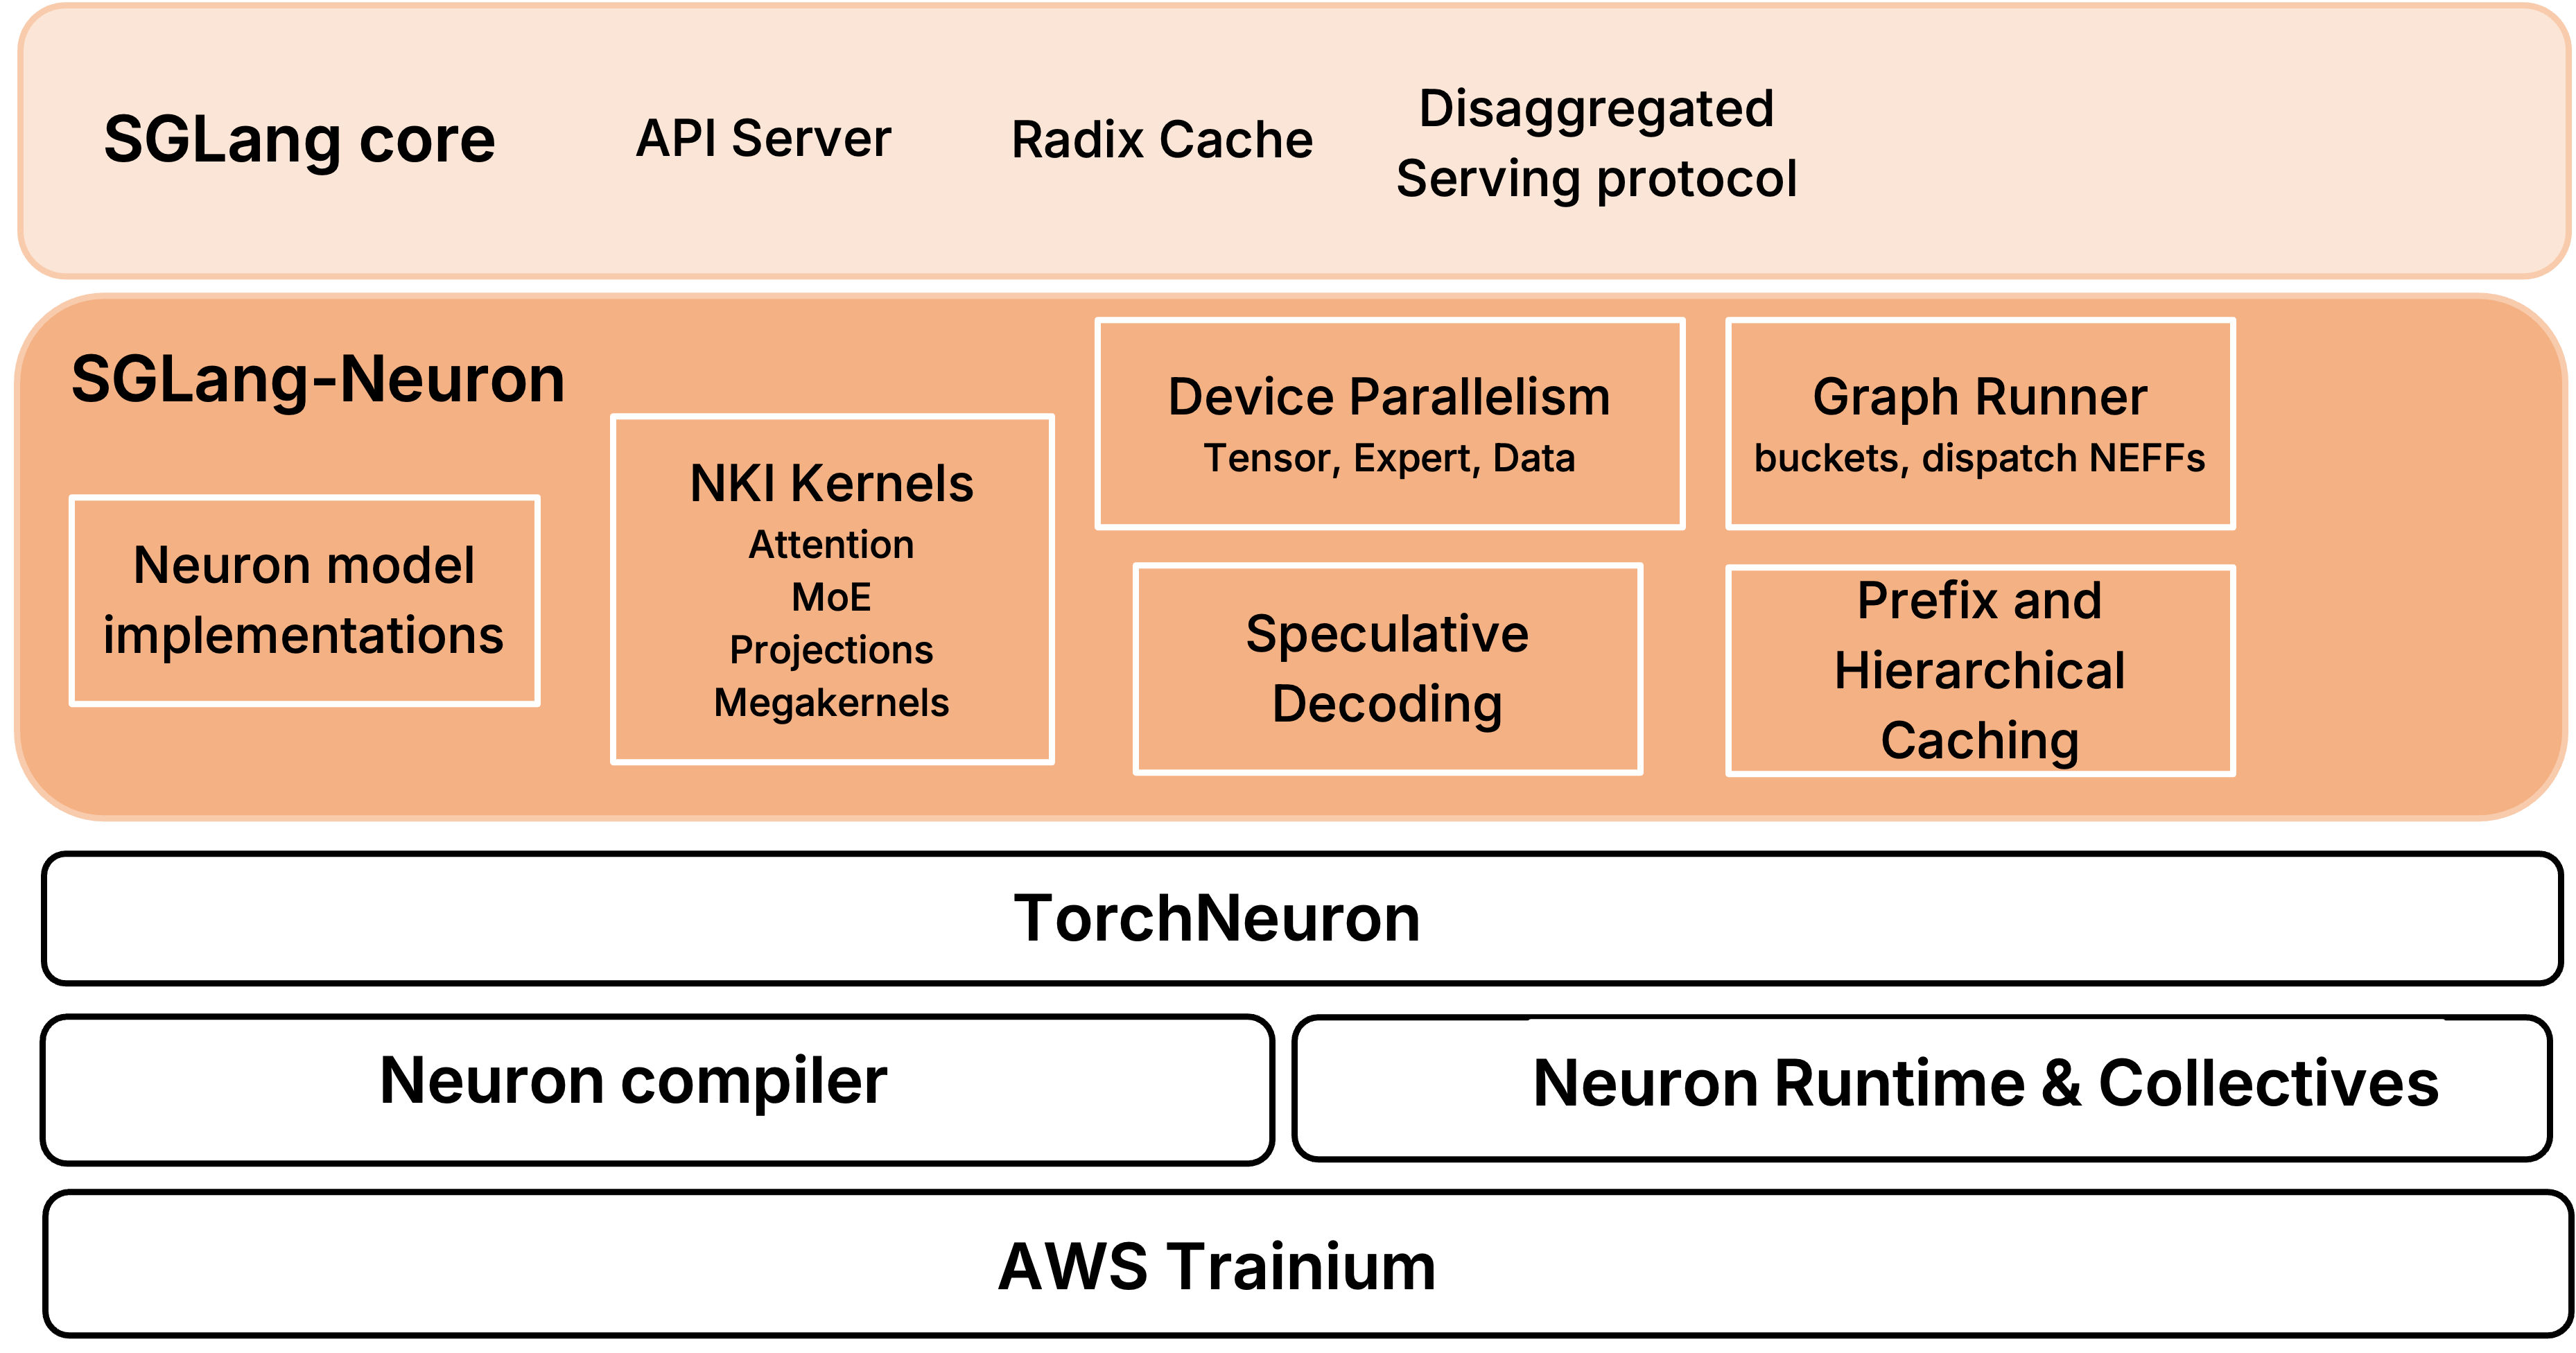
SGLang-Neuron 是一个树外插件,将 SGLang 与 AWS Trainium 连接起来。安装该插件会通过 SGLang 的插件入口点注册 neuron 平台,设置 SGLANG_PLATFORM=neuron 即可在服务器启动时选中它。SGLang 核心继续提供 API 服务器、请求生命周期、RadixAttention 和前缀缓存簿记。该插件则实现 Trainium 专属的模型、注意力、混合专家(MoE)以及图运行器。
图 1:AWS Trainium 上的 SGLang-Neuron
TorchNeuron 将 Trainium 注册为原生 PyTorch 设备。SGLang-Neuron 在模型执行路径中使用标准 PyTorch 算子,并集成以 Neuron Kernel Interface(NKI)编写的内核以提升性能。它通过 torch.compile 将这些算子和内核编译为可执行程序,由图运行器在服务期间准备并执行。
SGLang-Neuron 还支持 PD 分离。在此配置下,预填充服务器计算提示词的 KV 缓存,并通过 Elastic Fabric Adapter (EFA) 上的 NIXL 将其传输到解码服务器。随后,解码服务器生成剩余的 Token。每个服务器仍使用 SGLang 的调度器和请求生命周期,而插件负责管理 Trainium 的执行和 KV 缓存传输路径。
要按本演练操作,你需要使用一个带有 pytorch-inference-sglang-neuronx 容器的 Trainium3 Amazon Elastic Compute Cloud (Amazon EC2) 实例。步骤如下:
docker run --rm -it \ --privileged --ipc=host \ -v /path/to/work:/work \ public.ecr.aws/neuron/pytorch-inference-sglang-neuron:v0.1.0-neuron-py314-sdk-2.33.0-ubuntu26.04 \ /bin/bash 在容器内启动 SGLang 模型服务器。 SGLANG_PLATFORM=neuron \ python -m sglang.launch_server \ --model-path openai/gpt-oss-120b \ --tp-size 8 \ --ep-size 8 \ --kv-cache-dtype fp8_e4m3 \ --context-length 10240 \ --chunked-prefill-size 8192 \ --max-running-requests 64 \ --max-total-tokens 655360 \ --mem-fraction-static 0.8 \ --host 127.0.0.1 \ --port 30000 向模型服务器发送请求。 curl -s http://127.0.0.1:30000/v1/chat/completions \ -H 'Content-Type: application/json' \ -d '{ "model": "openai/gpt-oss-120b", "messages": [ {"role": "user", "content": "Explain why the sky appears blue."} ], "temperature": 0, "max_tokens": 128 }' 如需更多信息,请参阅 SGLang-Neuron 入门指南以获取设置说明,并浏览仓库文档以了解支持的模型、功能和已验证配置。
SGLang-Neuron 通过原生 PyTorch 将 SGLang 熟悉的部署工作流带到 AWS Trainium。你可以启动 SGLang-Neuron 容器,并按照快速入门指南部署一个受支持的模型来上手。在你的工作负载中试用它,通过项目仓库参与贡献,并分享反馈,以帮助塑造未来的模型与功能支持。
Alex 是 RadixArk 的技术员工(Member of Technical Staff)。他负责 MultiHardware,也是 SGLang 的核心开发者。
Yihao 是 RadixArk 的技术员工(Member of Technical Staff)。他同时从事多模态/扩散模型和多硬件方面的工作。
Lingyan 是 RadixArk 的产品经理。她负责 SGLang 的推广采用与多硬件支持工作。
Srecharan 是 Amazon Annapurna Labs 从事 AI 推理技术的软件工程师。
Zeyu 是 Amazon Annapurna Labs 从事 AI 推理技术的软件工程师。
Vinesh 是 Amazon Annapurna Labs 从事 AI 推理技术的软件工程师。
Yuchen 是 Amazon Annapurna Labs 从事 AI 推理技术的软件工程师。
Pinak 在 Amazon 的 Annapurna Labs 从事 AWS Trainium 上 AI 模型的性能优化工作。
Chi 是 Amazon 旗下 Annapurna Labs 的软件开发经理,从事 AI 推理技术工作。
译文由英文原文机器翻译,术语按行业惯例统一,可在文末展开原文核对。
查看英文原文(Deploy frontier AI models on AWS Trainium with SGLang-Neuron)
Today, Amazon announced that SGLang-Neuron is publicly available and can be accessed through an AWS Deep Learning Container, released by RadixArk in collaboration with Annapurna Labs. With SGLang-Neuron, you can serve models and generate reinforcement learning (RL) rollouts with SGLang on AWS Trainium using the same SGLang interface you use today. Trainium is a portfolio of AWS AI chips that delivers strong economics for AI training and inference at scale. Now, running SGLang on Trainium follows the SGLang workflow you already know: you launch models through SGLang’s server interface and invoke the endpoint using the same generation APIs. Underneath that interface, SGLang-Neuron runs on native PyTorch. With its out-of-tree plugin design, Trainium support and SGLang core develop independently and iterate faster.
How SGLang runs on Trainium
SGLang-Neuron is an out-of-tree plugin that connects SGLang with AWS Trainium. Installing the plugin registers the neuron platform through SGLang’s plugin entry points, and setting SGLANG_PLATFORM=neuron selects it when the server starts. SGLang core continues to provide the API server, request lifecycle, RadixAttention, and prefix-cache bookkeeping. The plugin implements the Trainium-specific models, attention, mixture of experts (MoE), and the graph runner.
Figure 1: SGLang-Neuron on AWS Trainium
TorchNeuron registers Trainium as a native PyTorch device. SGLang-Neuron uses standard PyTorch operations for the model execution path and incorporates kernels written with the Neuron Kernel Interface (NKI) for performance. It compiles these operations and kernels into executable programs using torch.compile, which the graph runner prepares and executes during serving.
SGLang-Neuron also supports PD disaggregation. In this configuration, a prefill server computes the prompt KV cache and transfers it to a decode server using NIXL over Elastic Fabric Adapter (EFA). The decode server then generates the remaining tokens. Each server still uses SGLang’s scheduler and request lifecycle, while the plugin manages the Trainium execution and KV-cache transfer path.
Serving models on AWS Trainium using SGLang-Neuron
To follow this walkthrough, you use a Trainium3 Amazon Elastic Compute Cloud (Amazon EC2) instance with a pytorch-inference-sglang-neuronx container. Here are the steps:
- Start the container.
docker run --rm -it \ --privileged --ipc=host \ -v /path/to/work:/work \ public.ecr.aws/neuron/pytorch-inference-sglang-neuron:v0.1.0-neuron-py314-sdk-2.33.0-ubuntu26.04 \ /bin/bash - Launch the SGLang model server inside the container.
SGLANG_PLATFORM=neuron \ python -m sglang.launch_server \ --model-path openai/gpt-oss-120b \ --tp-size 8 \ --ep-size 8 \ --kv-cache-dtype fp8_e4m3 \ --context-length 10240 \ --chunked-prefill-size 8192 \ --max-running-requests 64 \ --max-total-tokens 655360 \ --mem-fraction-static 0.8 \ --host 127.0.0.1 \ --port 30000 - Send a request to the model server.
curl -s http://127.0.0.1:30000/v1/chat/completions \
-H 'Content-Type: application/json' \
-d '{
"model": "openai/gpt-oss-120b",
"messages": [
{"role": "user", "content": "Explain why the sky appears blue."}
],
"temperature": 0,
"max_tokens": 128
}'
For additional information, please see the SGLang-Neuron getting started guide for setup instructions, and explore the repository documentation for supported models, features, and validated configurations.
Conclusion
SGLang-Neuron brings SGLang’s familiar serving workflow to AWS Trainium through native PyTorch. You can get started by launching the SGLang-Neuron container and following the quickstart to serve a supported model. Try it with your workloads, contribute through the project repository, and share feedback to help shape future model and feature support.
About the authors
Alex Nails
Alex is a Member of Technical Staff at RadixArk. He leads MultiHardware and is a core developer of SGLang.
Yihao Wang
Yihao is a Member of Technical Staff at RadixArk. He works on both multi-modal/diffusion models and multi-hardware.
Lingyan Hao
Lingyan is a Product Manager at RadixArk. She works on SGLang adoption and multi-hardware enablement.
Srecharan Selvam
Srecharan is a software engineer working on AI Inference technology at Annapurna Labs, Amazon.
Zeyu Wang
Zeyu is a software engineer working on AI Inference technology at Annapurna Labs, Amazon.
Vinesh Ravuri
Vinesh is a software engineer working on AI Inference technology at Annapurna Labs, Amazon.
Yuchen Jiang
Yuchen is a software engineer working on AI Inference technology at Annapurna Labs, Amazon.
Pinak Panigrahi
Pinak works on performance optimization of AI models on AWS Trainium at Annapurna Labs, Amazon.
Chi Wang
Chi is a Software Development Manager working on AI Inference technology at Annapurna Labs, Amazon.
正文保留英文原文,标题与摘要由机器翻译。
原文发布于 AWS Machine Learning(Deploy frontier AI models on AWS Trainium with SGLang-Neuron),标题、摘要与正文由机器翻译,术语按行业惯例统一,未经人工逐句校订。

