用于人类与模型置信度对比的软标签 MNIST 测试平台
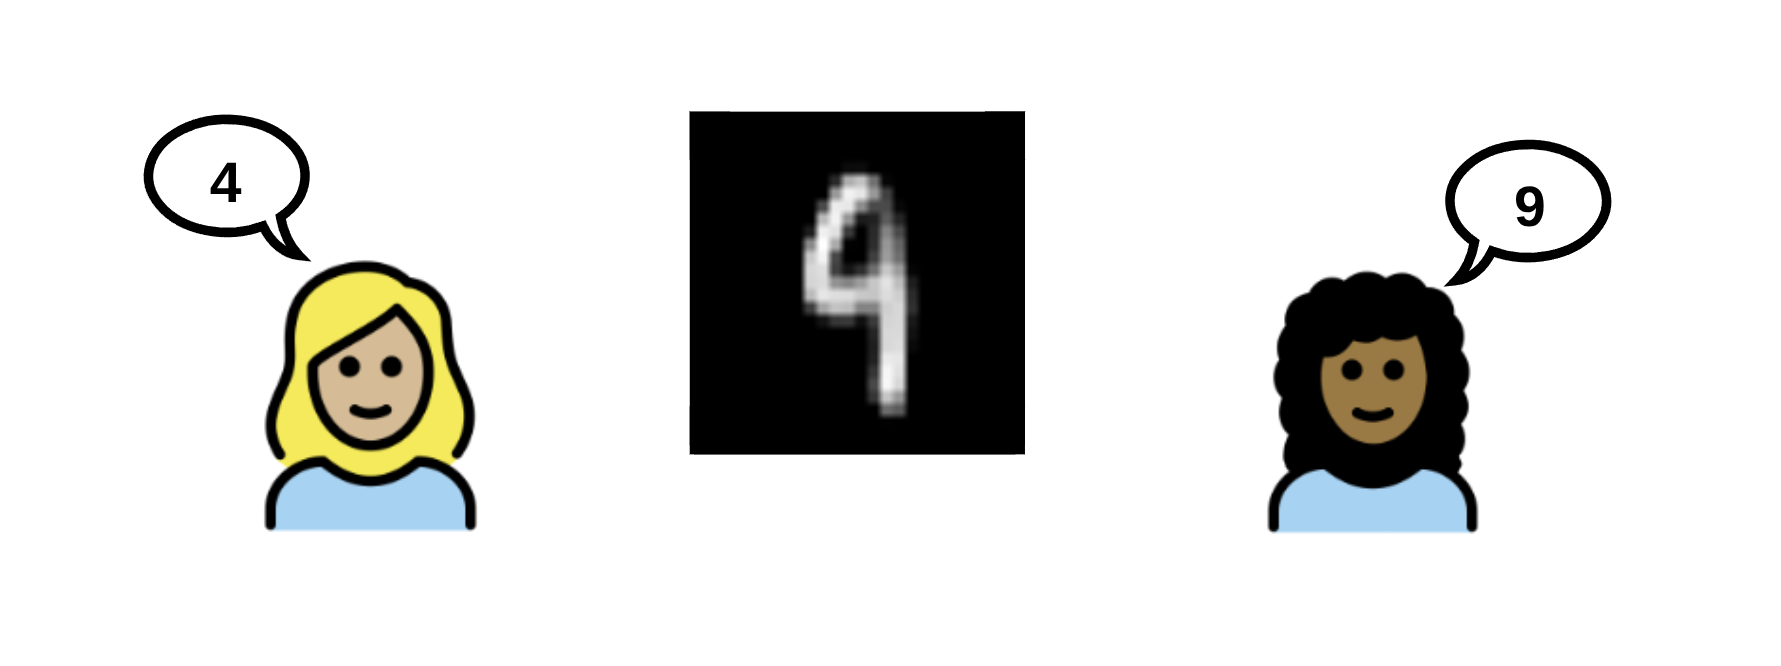
带有人类不确定性标注的软标签 MNIST 数据集
本文介绍一个为不确定性探索而设计的重新标注、受控数据集。我们简要涵盖以下内容:
通过 Hugging Face 快速获取
多模态扩展:文本
如需了解更多细节,请查看论文本身。
在如今这个时代,还需要再做一个数字数据集吗?
深度学习研究不断扩展规模,但超大规模数据集可能引入混杂因素,使人们很难理解深度学习的基本原理。尽管现代神经网络在清晰、无歧义的样本上表现非常出色,但它们在人类自身都无法达成一致的样本上的行为仍鲜为人知。当一个数据点确实存在歧义时(例如一个可能是 4 也可能是 9 的数字),模型应该如何学习并评估这类数据?
模型预测出 50/50 的分布,看起来像是犹豫不决,但它也可能只是模型在自信地表明答案本身存在歧义。将人类不确定性保留在标签中,已被证明能使分类更加稳健。为了更好地理解这类数据的益处,我们引入了两个精心设计的受控测试平台,用于探索困难且带歧义数据的影响。这些测试平台并非要取代大规模研究,而是让深度学习科学社区能够快速、低成本地迭代,从而帮助人们在更基础的层面上理解机器学习行为。
那么,为什么要重新标注数字?真实标签可能与人类的集体感知不一致:一个按照“写一个 4”的指令写出的数字,从书写者的意图看是 4,但看到这个数字的其他人可能大多会把它看成 9。解决这一问题的常见做法是对多个标注进行多数投票(例如 5 人中有 3 人看成 9,那么标签就被独热编码为 9)。见下图。另一种选择是保留所有标注,从而得到软标签(例如 4 为 2/5、9 为 3/5)。这样我们就得到了一个基于每位标注者首选结果生成的图像级软标签,但除了首选结果的差异之外,我们其实并没有真正衡量不确定性的手段。创建这类软标签的另一种方式,是让标注者选择多个标签,从而收集其个体不确定性(例如见下图最右侧部分)。
最后一种选项正是我们此处采用的方法:为每张图像从每位标注者处提取多个回答,以捕捉标注者个体的不确定性。不过,在深入标注细节之前,我们先来看看整体的处理流程。
数据集流程与标注简介
我们首先把数据集候选范围缩小到经典的 MNIST 数字,以及 Mukhoti 合成生成的一个变体,后者专门聚焦于生成有歧义的数字(以下称该数据集为 Mukhoti)。处理的第一步是移除数据集中的任何重复图像。随后,我们从每个数据集中抽取一个子集(更多细节见论文),并让人工重新标注这些数字。
对于每一张图像,标注员被要求针对每个可能的数字选项选择「是」「否」或「不确定」(理由见论文)。在下面的示例中,该标注员清楚地看到的是 9,因此对选项 9 选择「是」,并对其他所有数字选项选择「否」。
在下面的下一个示例中,标注员对标签不那么确定,对选项 5 和 6 都选择了「不确定」,同时用「否」排除了其他选项。这产生的是标签分布,而不是上面那种 one-hot 目标。对于下面这张图像,我们现在得到的是 50/50 的软标签。
这类标注为每个数字提供了标注员级别的软标签,我们再对给定图像上各标注员的分布取平均,将其聚合成图像级别的软标签:
这样得到的数据如下所示:
左侧,所有标注员都对 8 选择「是」,对其他所有选项选择「否」。由于该数字相当清晰,没有人选择「不确定」。右侧,大多数标注员同样选择了 8,但有一部分标注员还看到了 5、3 或 9。与左侧图像相比,这张图像不那么明确,因此有若干标注员在这张图像上选择了「不确定」。
MNIST 子集包含 3,046 张已标注图像,Mukhoti 子集有 2,484 张。每张图像有 3 到 10 名标注员;平均每张图像约有 6 名标注员。
我们将原始标签与重新标注后的数据进行比较,发现当对一组新标签进行多数投票时,原始标签会发生改变。例如,假设某人收到的指令是写下数字 7,并遵循了该指引,因此标签标注为 7。但大多数观察者(标注者)看到的是 1,而不是 7,于是这张图像就被重新标注为 1(改变了其众数标签)。在 MNIST 中,只有约 3% 的数据以这种方式改变了原始标签,而在 Mukhoti 的合成变体中,约有 33% 的标签发生了改变。
以上考虑的是只有单一标签的传统视角。如果我们现在来看人类标注标签差异,也就是软标签,会得到下面这幅图景:
MNIST 子集中的数字大多清晰/简单,标注者在真实标签上能够达成一致。约 40% 存在一定的标签差异。Mukhoti 中的图像则明显更难、更具歧义。只有约 20% 的数据不存在人类标注标签差异。
*注:我们有意不清洗标注(我们招募的是高质量标注者,但仍可能存在一些噪声或草率的标注)。
数据已在 Hugging Face 上提供
该数据集以 image-level-soft-label-digits 之名发布在 Hugging Face 上。以下是部分可用列:
图像(images):灰度图像,形式为大小为 [1, 28, 28] 的列表
原始标签(original_labels):与源数据相关联的原始标签;对 MNIST 而言这是独热标签,而对 Mukhoti 而言这是合成生成的软标签:
平均不确定性(human_uncert_mean):这个数字给出的是某张图像上所有标注者平均的不确定程度。假设一张图像总共有三位标注者,每个人都要对每个数字选项选择是/否/不确定。那么如果第一位标注者有四次选择“不确定”,该标注者在这张图像上的不确定性就是 4/10 = 0.4。我们随后对三人的不确定性取平均,如下所示:
不确定比例(pct_ann_unsure):这个数字告诉我们,在给定图像上至少表达过一次不确定的标注者所占的比例。以上面同样的例子来说,这意味着三位标注者中有两位至少不确定过一次,因此得到 ⅔。
软标签(soft_label_yes_unc_equal 与 soft_label):我们采用两种简单方法把标注者的选择转换为标注者级别的软标签,再对其取平均,得到最终的图像级软标签。为更简单地说明,设想我们只有 3 个选项:0、1 或 7(而非全部 10 个数字);见下图。
在方案 1(soft_label_yes_unc_equal)中,“是”和“不确定”两种选择都获得权重 1,以构成每位标注者各自的概率分布。因此对于第一位标注者,其选择了“是”和“不确定”,我们得到的分布是:1 的概率为 0.5,7 的概率为 0.5。
而在方案 2(soft_label)中,“不确定”的权重是“是”的一半,因此“是”为 1、“不确定”为 0.5,得到的标签为:1 的概率为 0.67,7 的概率为 0.33。
这些绝非把这些标签聚合为分布的唯一方式,其他方案我们留待未来探索。
新的多数标签(soft_label_argmax):新的多数投票标签(majn)。这是一个独热编码(one-hot)标签,代表从人类标注者处获得最高共识的类别,直接由图像级软标签导出:
import jsonimport matplotlib.pyplot as pltimport pandas as pddf = pd.read_parquet("hf://datasets/majapavlo/image-level-soft-label-digits/image_level.parquet")row = df.iloc[5113] # 示例图像索引image = row["images"].reshape(28, 28)soft_label = json.loads(row["soft_label"])header = " ".join(f"{d:>4}" for d in range(len(soft_label)))values = " ".join(f"{p:>4.2f}" for p in soft_label)plt.imshow(image, cmap="gray")plt.axis("off")plt.subplots_adjust(bottom=0.4)plt.figtext(0.5, 0.06, f"{header}\n{values}\n\nsource: {row['source']} annotators unsure: {row['pct_ann_unsure']:.0%}", ha="center", family="monospace", fontsize=14)plt.show()
这样应会得到如下图表的输出结果:
由上方代码片段生成的图像
更多详情请参阅:
论文将发表于 NeurIPS 2026 Evaluations and Datasets Track:https://arxiv.org/pdf/2605.18648
在上述数据收集工作之后,该数据集近期通过语音转文字的标注流程进行了扩充。标注员查看图像并大声说出分类结果,随后处理得到以下内容:
未经过滤的思考过程(asstring):不再强制给出单一的最终标签,而是将语音逐字转写,有意保留诸如“umm”或“maybe”这类犹豫与含糊的措辞
原文较长,译文为节选;译文由英文原文机器翻译,术语按行业惯例统一,可在文末展开原文核对。
查看英文原文(A Soft-Label MNIST Testbed for Human vs. Model Confidence)
Soft-Label MNIST Dataset With Human Uncertainty Annotations
This article introduces a re-labelled, controlleddatasetdesigned for uncertainty exploration. We briefly cover the following:
Quick access via Hugging Face
Multi-modal extension: text
For more details, please check out the paper itself.
Yet another digit dataset, in this day and age?
Deep learning research keeps scaling, but massive datasets can introduce confounding factors that make understanding fundamental principles of deep learning rather challenging. While modern neural networks do really well on clear, unambiguous examples, their behaviour on examples that humans themselves can’t agree upon is still poorly understood. When a datapoint is genuinely ambiguous (e.g. a digit that could be either a 4 or a 9), how should a model learn and evaluate such data?
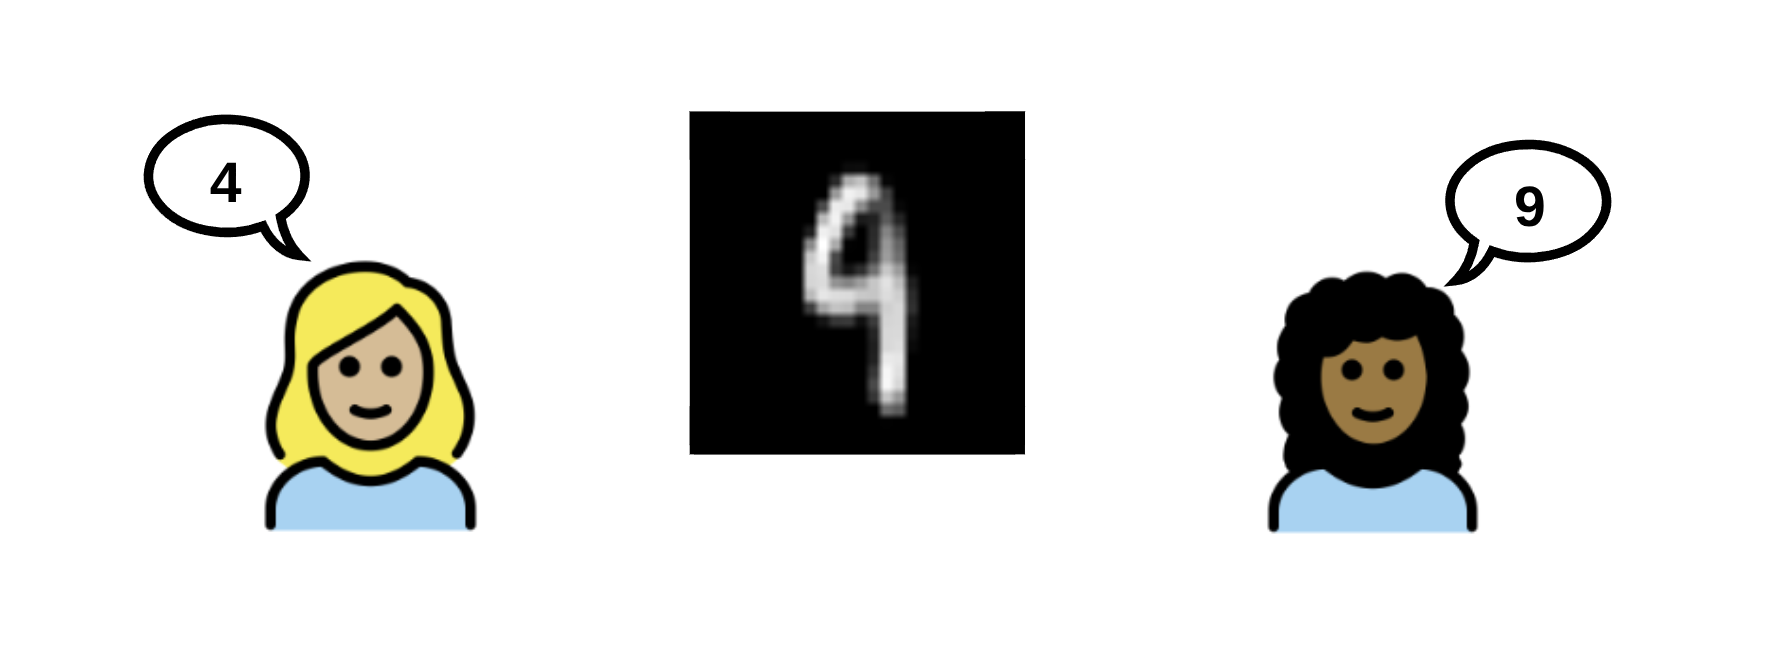
A model predicting a 50/50 split could look like indecision, but it might just be the model confidently reporting that the answer is ambiguous. Keeping human uncertainty in labels has been shown to make classification more robust. To understand the benefits of such data better we introduce two carefully-controlled testbeds for exploring the impact of difficult and ambiguous data. Rather than replacing large-scale research, these testbeds allow the science of deep learning community to iterate quickly and cheaply to help with understanding machine learning behaviour at a more fundamental level.
So why re-label digits? Ground truth labels can diverge from collective human perception: a digit created under the instruction to write a 4 is a 4 by the writer's intent, but others observing that same digit may mostly see a 9. A common approach to resolve this is to take a majority vote over multiple annotations (e.g. 3 out of 5 people see a 9, so the label is one-hot encoded as a 9). See image below. Another option would be to keep all annotations, which results in soft-labels (e.g., 2/5 for 4 and 3/5 for 9). This gives us an image-level soft-label that was created from each annotator's top choice, but we don’t really have a measure of uncertainty beyond the differences in top choice. Another way of creating such soft-labels is to collect individual annotator uncertainty by letting them choose more than one label (e.g. see right most part of the image below).
This last option is the approach we take here: extracting multiple-responses for an image per annotator to get a sense of individual annotator uncertainty. Before we go into annotation details, however, let’s first look at our high level pipeline.
Brief Dataset Pipeline & Annotation
We first narrowed down our dataset candidates to the classical MNIST digits and a synthetically created variant from Mukhoti, which specifically focused on generating ambiguous digits (we’ll refer to this dataset as Mukhoti). The first step in processing was to remove any duplicate images from the dataset. We then sampled a subset of each dataset (see paper for more details) and had humans re-label the digits.
For every image the annotators were instructed to either select yes, no or unsure for each potential digit option (see paper for reasoning). In the example below, the person clearly sees a 9, thus selects yes for the option: 9, and no for every other digit option.
In the case of the next example below the annotator is less certain about the label and selects unsure for both option 5 and 6, while discounting the other options with a no. This results in a label distribution rather than a one-hot target as in the case above. We now have a 50/50 soft-label for the image below.
Such annotations give us annotator-level soft-labels for each digit, which we then aggregate to an image-level soft-label, by averaging the distributions from individual annotators over a given image:
This gives us data that looks as follows:
On the left side, all annotators choose the option yes for 8 and no for all other options. None of them select unsure as the digit is rather clear. On the right hand, most annotators choose an 8 again, but a portion of annotators also see a 5 or 3 or 9. The image is less clear cut compared to the left one, and so several annotators select the unsure option on this image.
The MNIST subset contains 3,046 labelled images, the Mukhoti subset has 2,484. Each image has between 3 and 10 annotators per image; on average there are about 6 annotators per image.
We compare the original labels with the newly-relabelled data and find that the original label changes when we take a majority vote over the collection of new labels. For instance, say someone got the instruction to write down a 7, follows the guideline and so the label says 7. But the majority of observers (annotators) sees a 1, not a 7, so this image gets relabelled as a 1 (changing its mode). In MNIST only about 3% of the data changed the original label in this way, while in Mukhoti’s synthetic variant about 33% of the labels changed.
The above considers the traditional view of only having one label. If we now look at human label variation, so the soft-labels, we get the following picture:
The MNIST subset has mostly clear/easy digits where annotators agree on the ground truth label. Around 40% have some label variation. Mukhoti has considerably more difficult/ambiguous images. Only around 20% of the data has no human label variation.
*Note: we intentionally don’t clean the annotations (we recruit high-quality annotators but some noise/sloppy annotations may still exist).
Data available on Hugging Face
The dataset is released on Hugging Face as image-level-soft-label-digits. These are some of the available columns:
Images (images): the grayscale images as a list of size [1, 28, 28]
Original labels (original_labels): the original labels associated with the source data; for MNIST this is the one-hot label, while for Mukhoti this is the synthetically generated soft-label:
Mean uncertainty (human_uncert_mean): this is a number that gives us the average magnitude of doubt across all annotators for an image. Say we have three annotators in total for an image, each has to select yes/no/unsure for each digit option. So if the first annotator chooses unsure four times, that person's uncertainty for that image is 4/10 = 0.4. We then take the average uncertainty over all three, see below:
Unsure proportion (pct_ann_unsure): this is a number that tells usthe fraction of annotators who expressed uncertainty at least once for a given image. So for the same example as above this would mean 2 out of 3 annotators were unsure at least once, so we have ⅔.
Soft-labels (soft_label_yes_unc_equal & soft_label): we take two simple approaches to converting the annotator choices to annotator-level soft-labels, which we then average to get the final image-level soft-labels. To illustrate this more simply, imagine we only have 3 options: 0, 1 or 7 (not all 10 digits); see image below.
In option 1 (soft_label_yes_unc_equal) both yes and unsure selections receive a weight of 1 to form each annotator’s individual probability distribution. So in the case of the very first annotator, having selected yes and unsure, we get a distribution that gives 0.5 to 1 and 0.5 to 7.
In option 2 (soft_label), however, unsure gets a half the weight to yes, so we have 1 for yes and 0.5 for unsure which results in a label that gives 0.67 to 1 and 0.33 to 7.
These are in no way the only ways to aggregate these labels to a distribution, we leave other options for future exploration.
New majority label (soft_label_argmax): New majority voted labels (majn). A one-hot encoded label representing the class that received the highest consensus from the human annotators, derived directly from the image-level soft-labels:
import jsonimport matplotlib.pyplot as pltimport pandas as pddf = pd.read_parquet("hf://datasets/majapavlo/image-level-soft-label-digits/image_level.parquet")row = df.iloc[5113] # sample image indeximage = row["images"].reshape(28, 28)soft_label = json.loads(row["soft_label"])header = " ".join(f"{d:>4}" for d in range(len(soft_label)))values = " ".join(f"{p:>4.2f}" for p in soft_label)plt.imshow(image, cmap="gray")plt.axis("off")plt.subplots_adjust(bottom=0.4)plt.figtext(0.5, 0.06, f"{header}\n{values}\n\nsource: {row['source']} annotators unsure: {row['pct_ann_unsure']:.0%}", ha="center", family="monospace", fontsize=14)plt.show()
That should result in an output that plots the following:
image generated by code snippet above
For more details have a look at:
Paper to appear in NeurIPS 2026 Evaluations and Datasets Track: https://arxiv.org/pdf/2605.18648
Following the data collection described above, the dataset was recently expanded using a voice-to-text annotation process. An annotator viewed the images and classified them aloud, which was then processed into the following:
Unfiltered thought process (asstring): instead of forcing a single final label, the speech was transcribed word-for-word, intentionally keeping hesitation and hedging such as “umm” or “maybe”
Duration (in seconds): the time it took to label the digit was also included in the add-on data
Note: This data is saved as a separate file (data_multimodal_addon.csv) on a differentHugging Face repository(image-level-soft-label-digits-addon) as an independent extension and was collected separately from the original paper's dataset.
The soft-digits dataset is released under the CC-BY-SA 4.0 license. This dataset is a combination of a...
Re-annotated subset of the MNIST dataset, originally created by Yann LeCun and Corinna Cortes. (released under CC-BY-SA 3.0)
Re-annotated subset of the distributional Ambiguous-MNIST dataset, originally created by Jishnu Mukhoti, Andreas Kirsch, Joost van Amersfoort, Philip H.S. Torr, and Yarin Gal. (released under MIT license)
Isolation Forest, Local Outlier Factor, One-Class SVM, Autoencoders, Robust Covariance Estimator and Time Series Analysis
May 14, 202122 min read
In this post, I am decoding the major building block of current state of art object detection, and see how it compares with some of the...
September 12, 20205 min read
How multi-armed bandits can help Starbucks send personalized offers to its customers.
Learn how to train a decision tree model for churn prediction.
January 26, 20197 min read
How can you get started, and who should implement your first AI projects?
April 22, 202515 min read
A Resource-Saving and Performance-Competitive Alternative to Vision Transformers
April 28, 20228 min read
Embarrassing situations where you and your data might find yourselves
September 21, 202111 min read
Statistics is vital in Data Analytics. We will go over some fundamentals about statistics and how to apply it in Python Programming...
August 11, 20201 min read
Find your way through a random forest of terminology
February 7, 20226 min read
原文为英文,正文由自动抓取并保留原文。
原文发布于 Towards Data Science(A Soft-Label MNIST Testbed for Human vs. Model Confidence),标题、摘要与正文由机器翻译,术语按行业惯例统一,未经人工逐句校订。